for decide
Does semantic iteration deserve its own syntax, or is it sugar for filtering?
This chapter reports a CPU experiment that ran here: the loop strategies over the Chapter 22 SciFact candidate lists and their cached cross-encoder scores. No language model was run in this chapter. The result is a rejection of the construct, which the chapter is allowed to make.
The question
Chapters 21 and 22 showed that something must select what a decision reads, and that the filter is where the end-to-end loss lives on SciFact. This chapter asks the next question: is iteration its own construct?
for decide relevant(doc, claim) in corpus:
    act(doc)
against its library form:
for doc in filter(relevant, corpus):
    act(doc)
The chapter question is whether the construct expresses anything the library cannot.
The hypothesis and prior work
Our starting hypothesis is that only early termination and ranked iteration differ, and both are better served by library calls.
Three papers frame the comparison: RankGPT, Pairwise Ranking Prompting (PRP) and DocETL. The DocETL figures below use arXiv v3, §5.1.2, Tables 2–3; RankGPT uses its primary paper, Tables 5 and 11 and Appendix H. Costs belong to the paper’s models, prices and experimental setup.
| Source | What it orders or optimises | How it works | What it costs | What it does not do |
|---|---|---|---|---|
| DocETL, Shankar et al. (2024), §2-§5 | A document-processing pipeline of LLM operators (map, reduce, filter, resolve, equijoin) | An agent-based optimiser rewrites the pipeline using 13 directives (e.g. splitting long documents, “gleaning”: a validator LLM critiques and the first LLM refines), then compares candidate plans | Optimised plans can cost more and run slower; optimisation itself cost $1.58 on a sample (§5.1.2). The v3 abstract and evaluation report 21–80% improvements in task-specific accuracy metrics over the evaluated baselines; this is not a uniform percentage-point gain | Has no iteration construct to add: iteration is the pipeline operators. Optimises accuracy only; cost and latency are future work (§4.1) |
| RankGPT, Sun et al. (2023), §3-§7 | The order of a candidate list | The model emits a permutation ("[2] > [3] > [1]") for a window of passages; a sliding window (size 20, step 10) covers the top 100 | About 10 API calls per query; about $0.60 per query with GPT-4, and 11 to 32 seconds per query (Appendix H) | The tested open models perform poorly in this setup; very sensitive to the initial order (random order drops TREC-DL19 nDCG@10 from about 66 to about 25); sometimes duplicates or omits identifiers |
| PRP, Qin et al. (2023), §2-§5 | The order of a candidate list | Ask which of two passages is more relevant, each pair twice with the order swapped. Three variants: all pairs, O(N^2) calls; heap-sort, O(N log N); sliding passes, O(N) per pass | One call per comparison, so the cost grows with the variant | No transitivity guarantee for sorting; all-pairs is quadratic |
Two things in the table bear directly on for decide.
First, the two ranking papers disagree on mechanism (listwise permutation against pairwise comparison) and agree on the structure: both order a candidate set as a separate step, then something else uses the order. Neither proposes a loop form. DocETL is the closest to this chapter in spirit, since it also asks what semantic operators the system should expose, and it answers with operators and rewrites rather than with syntax.
Second, ordering a set is not free. Ranking 10 candidates needs a score for every candidate, or a number of LLM calls that ranges from linear to quadratic in the list length. This matters for how the experiment below should be read.
Both rankers order a candidate list before iterating it. That is the shape the construct claims: an iteration whose order is itself decided.
The build
src/arbiter/iteration.py implements five loop strategies and a comparator.
from arbiter.iteration import (
    filter_then_loop,
    for_decide,
    for_decide_early,
    for_decide_ranked,
    library_early_stop,
    ranked_is_sort_plus_loop,
)

DOCS = ["no", "yes", "no", "yes", "no"]
is_yes = lambda d: d == "yes"
# 1. The two forms agree when neither stops early.
print("1. eager filter-then-loop vs lazy for-decide")
eager = filter_then_loop(DOCS, is_yes)
lazy = for_decide(DOCS, is_yes)
print(f"   decision equal: {eager.decision == lazy.decision}")
print(f"   evidence equal: {eager.evidence == lazy.evidence}")
print(f"   docs consulted: eager={eager.docs_consulted} lazy={lazy.docs_consulted}")
# 2. Early termination consults fewer documents.
print("2. early termination (stop at the first relevant doc)")
early = for_decide_early(DOCS, is_yes)
print(f"   decision={early.decision} evidence={early.evidence} consulted={early.docs_consulted}")
# 3. The library form is identical.
print("3. the library form (takewhile)")
lib = library_early_stop(DOCS, is_yes)
print(f"   consulted equal: {early.consulted == lib.consulted}")
print(f"   evidence equal: {early.evidence == lib.evidence}")
# 4. Ranked iteration is a sort plus the same loop.
print("4. ranked iteration")
scores = [0.1, 0.5, 0.2, 0.9, 0.0]
ranked = for_decide_ranked(DOCS, scores, is_yes)
print(f"   visit order (original indices): {ranked.consulted}")
print(f"   is sort+loop: {ranked_is_sort_plus_loop(DOCS, scores, is_yes)}")
# 5. The decision the construct makes, and the library form of it.
print("5. the decision, and its library form")
print(f"   for decide relevant(doc) in corpus -> {early.decision}")
print(f"   any(relevant(d) for d in corpus)   -> {any(is_yes(d) for d in DOCS)}")
The walkthrough prints:
1. eager filter-then-loop vs lazy for-decide
   decision equal: True
   evidence equal: True
   docs consulted: eager=5 lazy=5
2. early termination (stop at the first relevant doc)
   decision=True evidence=('yes',) consulted=2
3. the library form (takewhile)
   consulted equal: True
   evidence equal: True
4. ranked iteration
   visit order (original indices): (3,)
   is sort+loop: True
5. the decision, and its library form
   for decide relevant(doc) in corpus -> True
   any(relevant(d) for d in corpus)   -> True
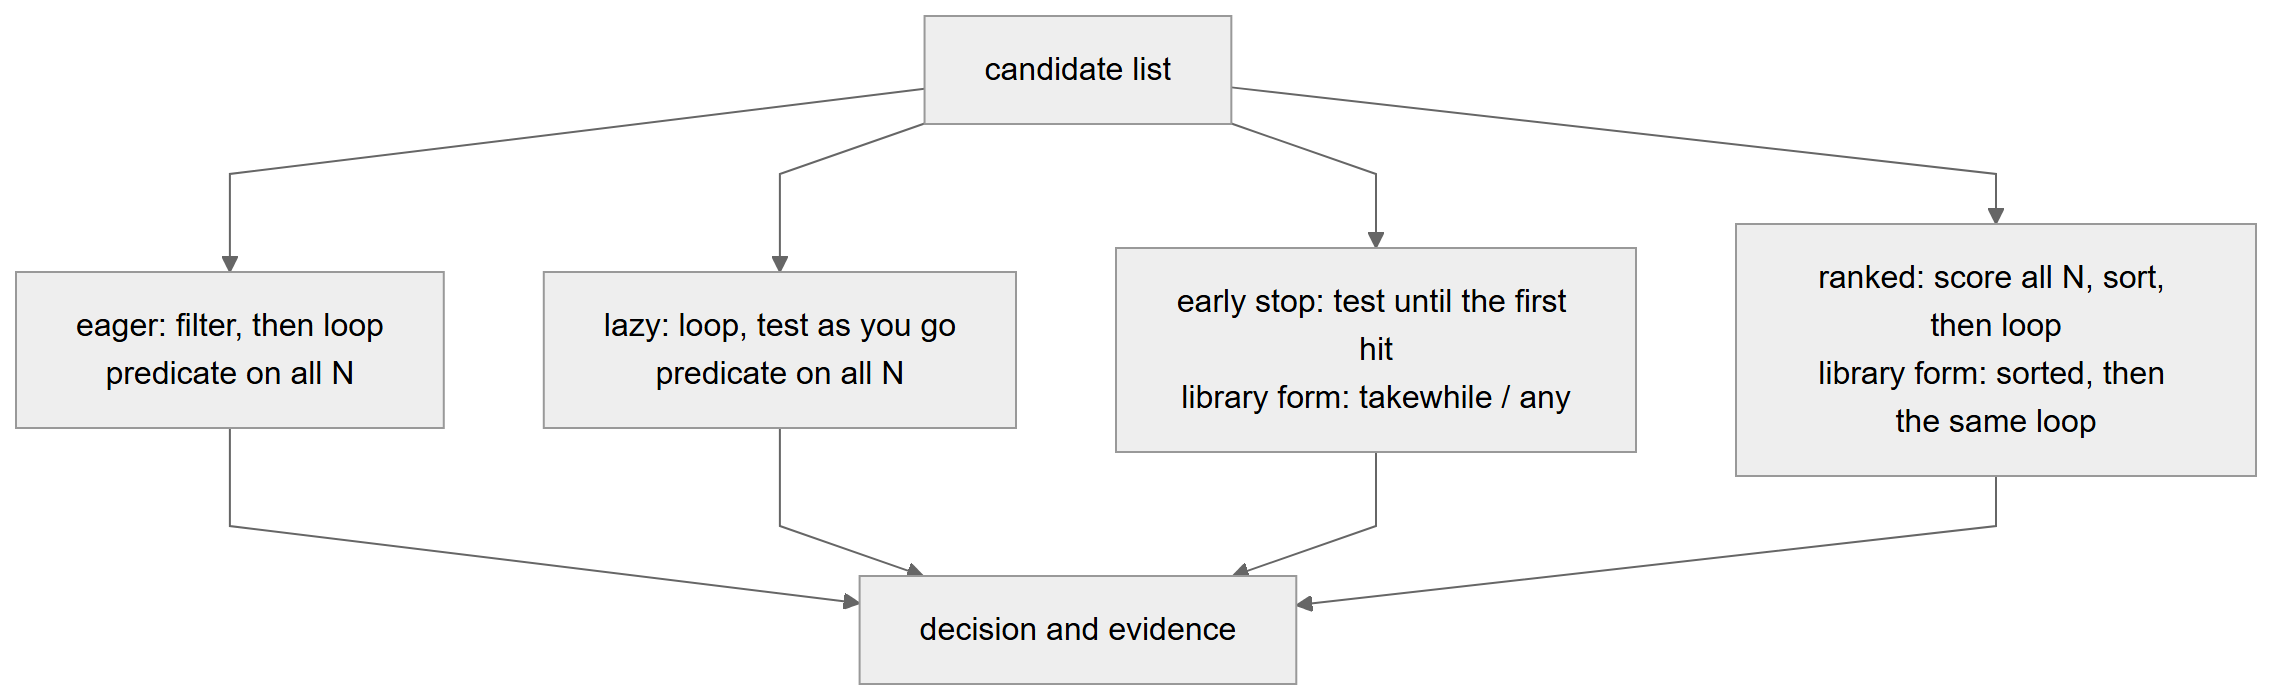
Four strategies, one decision. The question the rest of the chapter asks is whether any of the four does something its library form cannot, and what each costs in predicate evaluations.
The rejection rule, stated before the comparison
REJECT for decide if: (a) its decision and evidence equal filter-then-loop’s whenever neither stops early, and (b) every difference is reproduced by a library call — early termination by takewhile/any, ranked order by sorted — at equal or lower cost. ADOPT if some task needs a behaviour neither the library form nor a sort provides.
The experiment
python examples/ch23-for-decide/run_ch23.py runs the strategies over the Chapter 22 candidate lists: SciFact, BM25 top-10 per claim, the same 188 test claims, with the cached ms-marco cross-encoder score per candidate and the Chapter 22 threshold (tau 3.3733) deciding “evidence”.
Test split (results/ch23.jsonl):
| Quantity | Value |
|---|---|
| decision agreement (all four strategies) | 1.000 |
| evidence equality, eager vs lazy | 1.000 |
| ranked iteration equals sort + loop | 1.000 |
| mean documents consulted (eager) | 10.00 |
| mean documents consulted (lazy, no stop) | 10.00 |
| mean documents consulted (early stop) | 4.04 |
| mean documents consulted (ranked) | 3.92 |
mean documents consulted (library takewhile) |
4.04 |
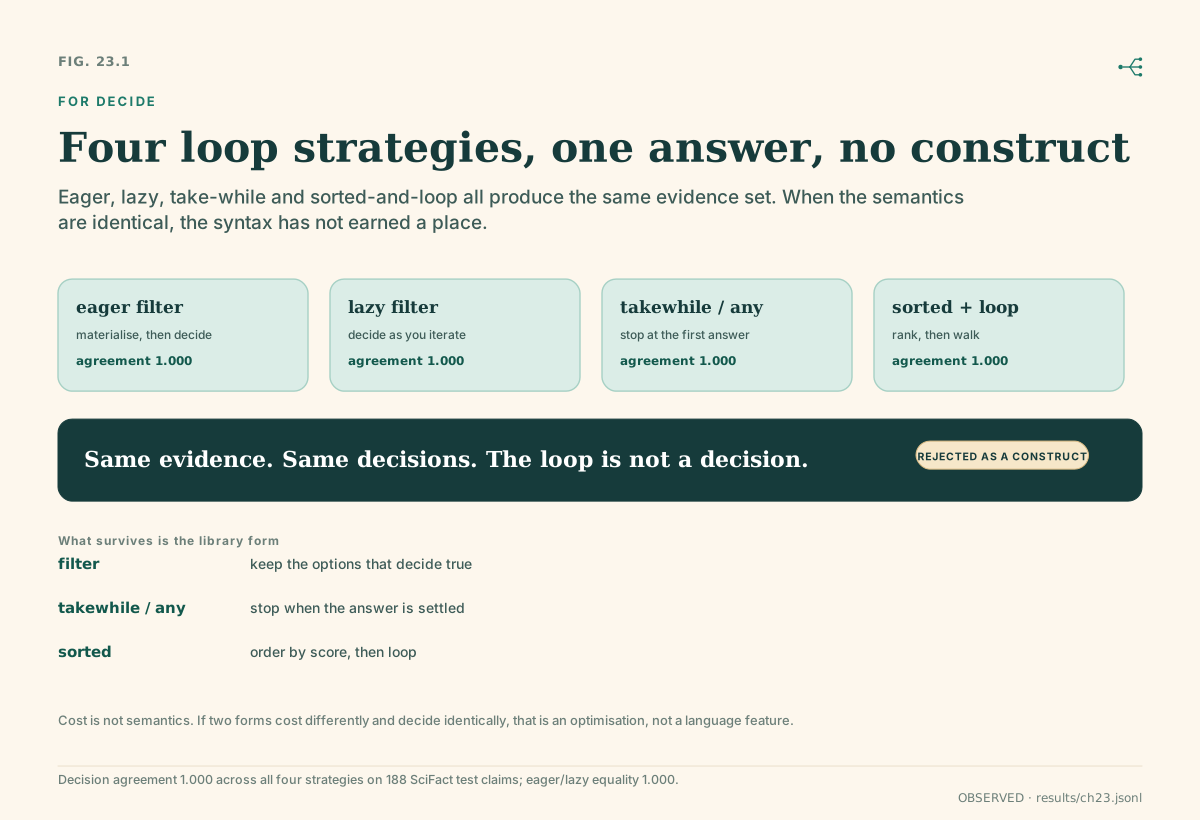
Applying the rule: (a) holds (1.000 evidence equality and decision agreement); (b) holds (the library form consults exactly 4.04 documents, the same as the construct’s early stop; the ranked form is a sort plus the same loop, and the comparator returns true on every claim). The verdict is REJECTED.
What the results show
-
Lazy and eager are observationally identical with a pure predicate. The construct’s supposed advantage over
filteris that it interleaves evaluation with action. With a pure predicate that interleaving has no observable effect: same decision, same evidence, same count (10.00 both). The difference only appears with early termination — which is a separate mechanism, not iteration order. -
Early termination is a library call.
takewhileconsults exactly as many documents as the construct’s early stop (4.04 both), on all 188 claims. Nothing about the language form is needed to get the saving. -
Ranked iteration barely helps, and it is a sort. Ranking the candidates by the cross-encoder before iterating saved only 0.12 documents on average (4.04 to 3.92), because the cross-encoder predicate itself misses evidence for about a third of claims (the Chapter 22 decision error), and those claims scan the whole list either way. The ranked form is exactly
sorted(...)followed by the same loop (ranked_is_sort_plus_loopreturns true on every claim), so it adds no semantics beyond a sort.The 3.92 counts documents the loop visited, and it leaves out what ranking cost. To rank the candidates the predicate must be evaluated on all 10 of them first (here the cached cross-encoder scores were computed for every candidate, 10 forward passes per claim), while the lazy early-stopping loop evaluates it on 4.04 on average. So in provider calls the ranked form is the most expensive, 10.00 against 4.04, and its “saving” of 0.12 loop visits is paid for with 5.96 extra predicate evaluations. With an LLM predicate the gap would be larger still, since the ranking papers above need one call per comparison or per window. Ranked iteration pays off only if ranking is much cheaper than the predicate it orders, for example a cheap first-stage score used to order candidates for an expensive judge. This experiment does not test that arrangement.
-
The decision it computes is
any. With the default sufficiency (one relevant document is enough), the construct’s decision isany(relevant(d) for d in corpus)— a library call, with no new type and no new failure mode.
Wrong / Correct. Wrong: “
for decideis a construct because it lets the program act while it searches.” Correct: on a pure predicate, acting while searching isfilterplustakewhile. Early termination is also expressible withanyor an explicit loop andbreak. The verdict is REJECTED.
Prior art
DocETL optimises pipelines by rewriting them (decomposing the data or the task); it does not introduce a new iteration construct. RankGPT and PRP order a candidate set before using it — a ranking step, not a loop primitive — and they disagree with each other on whether the ordering decision should be listwise or pairwise. Nothing in the three papers requires a new loop form, and this chapter claims none. What they do add is a caution about the construct’s best case: ordering candidates is a modelling decision with its own cost and its own failure modes (input-order sensitivity, intransitive comparisons), and a loop keyword would hide all of that.
What the result means
A loop over decisions is not a decision. for decide mixes iteration (a control-flow concern) with the semantic decision (a provider concern). The decision belongs to the predicate; the iteration belongs to for. Keeping them together in one keyword is what makes the construct look like it adds something, when the two halves are separately expressible.
Cost is not semantics. For a task asking only whether a pure predicate accepts any candidate, stopping at the first acceptance preserves that Boolean answer. A task that needs every accepted item must continue; early termination would change its result. A construct that only changes cost is an optimisation, and optimisations belong in the library or the compiler, not the syntax.
What to carry forward
If for decide is rejected, which constructs remain? On this evidence, decide, if decide and where decide stand (Chapters 16, 17, 22), and for decide becomes for ... in filter(...) plus takewhile. The next chapter asks a different question: how do decisions about decisions compose, and does a chain of decisions need a controller?
Limitations
- One corpus (SciFact), one scorer (ms-marco cross-encoder), one threshold (tau 3.3733 from Chapter 22). The loop comparison is deterministic given the scores.
- DocETL is cited for §2–§5 of arXiv v3. The checked abstract and evaluation both give 21–80% improvements in task-specific accuracy metrics; the earlier abstract/body discrepancy was a transcription error.
- The ranked-iteration cost comparison counts predicate evaluations only. Cached cross-encoder scores were free at loop time; the 10 forward passes per claim were paid when the cache was built.
- The early-termination saving depends on the scorer’s decision error: with a perfect predicate the first document would nearly always suffice. The 4.04 figure is a property of this scorer and corpus.
- The rejection rule was written before the comparison and is applied as written; a different rule (for example, adopting on any cost saving) would give a different verdict.
What this chapter establishes
If this is rejected, which constructs remain? The iteration form does; the language construct does not. Chapter 24 turns to composition.