Learning the Router
What happens when a router learns from the outcomes it observes, and those outcomes were chosen by the router itself? A simulated selection-bias failure and the priced audit that corrects it.
This chapter is a simulation over assumed provider profiles. Every accuracy curve, cost, signal noise and audit fraction is assumed and swept; every number is a consequence of them. No real router (RouteLLM, LinUCB) is measured.
The question
Chapter 29’s router used explicit rules over a signal you could read. Chapter 30’s cascade used stage confidences and thresholds you fitted once. Both treated the providers’ qualities as known: a curve, a profile, a number you supplied. Real systems do not know them. They estimate them from what they have seen, and the obvious source is the log of what the router itself did.
That is a trap. A router that sends easy requests to the cheap provider will only ever observe the cheap provider on easy requests. Its estimate of the cheap provider is therefore optimistic. The estimate then justifies sending even more to the cheap provider, which produces more easy-skewed data. The router’s policy generates the evidence that confirms the policy.
The chapter asks: what does a router learn when its own routing decides what it observes, and what does it cost to correct that?
You will leave able to say why “learn the router from logs” is not a neutral instruction, to read an audit fraction as a priced remedy, and to recognise the same structure in learning-to-defer and contextual-bandit papers.
What the literature gives you
Mozannar and Sontag are cited for §3-§6, Li et al. for §4, §5.1 and §5.2.1.
| Source | The setting | What the learner sees | Why it matters here |
|---|---|---|---|
| Mozannar and Sontag (2020), §3-§6 | A classifier h and a rejector r decide who predicts: the model, or a downstream expert | Samples (x, y, m), where m is the expert’s decision, so both arms are observed on every example. §6.4 relaxes this to limited expert labels | The method gives a consistent convex surrogate for the system loss (Theorem 1). It does not face our problem, because it is trained on logs where the expert answered too. Most of its experiments use simulated experts, and it needs a weight to be tuned |
| Li et al. (2010), §4, §5.1, §5.2.1 | A contextual bandit for news recommendation, with an offline evaluator | Only the payoff of the arm that was shown. Evaluation keeps the logged events where the evaluated policy agrees with the logging policy | Theorem 1: if the logging policy was uniformly random, the retained events are an unbiased sample. They collected a random bucket of traffic for this reason. That is the audit idea |
| Madras et al. (2018), §2-§5 | Learning to defer: the model predicts or passes to a decision-maker, with the pass penalty replaced by the decision-maker’s own per-example loss (rejection learning is the special case of a constant penalty, §2.3) | The decision-maker’s loss on each training example, so both arms are observed. Their decision-makers are simulated (COMPAS, Heritage Health), and results are medians of 5 runs (§5) | Deferral is a real route, and a learner that knows where the other arm is strong can do better than a constant-penalty reject. It shares Mozannar and Sontag’s assumption that both arms were logged, which a deployed router does not have |
The comparison with Mozannar and Sontag is the useful one. Their learner sees what the expert would have said on every training example. A router that has already been deployed sees only the arm it chose. Our setting is the harder one, and it is the setting Li et al. were solving: partial feedback from a policy that is not random. So what separates “learning to defer” in a lab from learning to route in production is not a better loss function. It is whether the log contains the counterfactual.
Our expectation therefore leans on Li et al.: a random audit sample gives a direct way to estimate performance outside the traffic a provider normally receives. This is a sufficient design for the simulation, not a claim that random logging is the only possible correction for selection bias.
The hypothesis and prior work
Our starting hypothesis (HYPOTHESIS, preregistered in metadata/31-chapter.yaml) is that a router that only sees the outcomes of providers it selects learns a biased value, and a random audit sample is the mitigation.
Stated so it can fail: with no audit, the learned estimate of the weak provider will exceed its true marginal accuracy by a clear margin, and a deployment built on that estimate will do worse than the oracle. As audit fraction grows, the bias will shrink. The prediction would be refuted if bias were negligible at zero audit, or if audit failed to reduce it.
The build
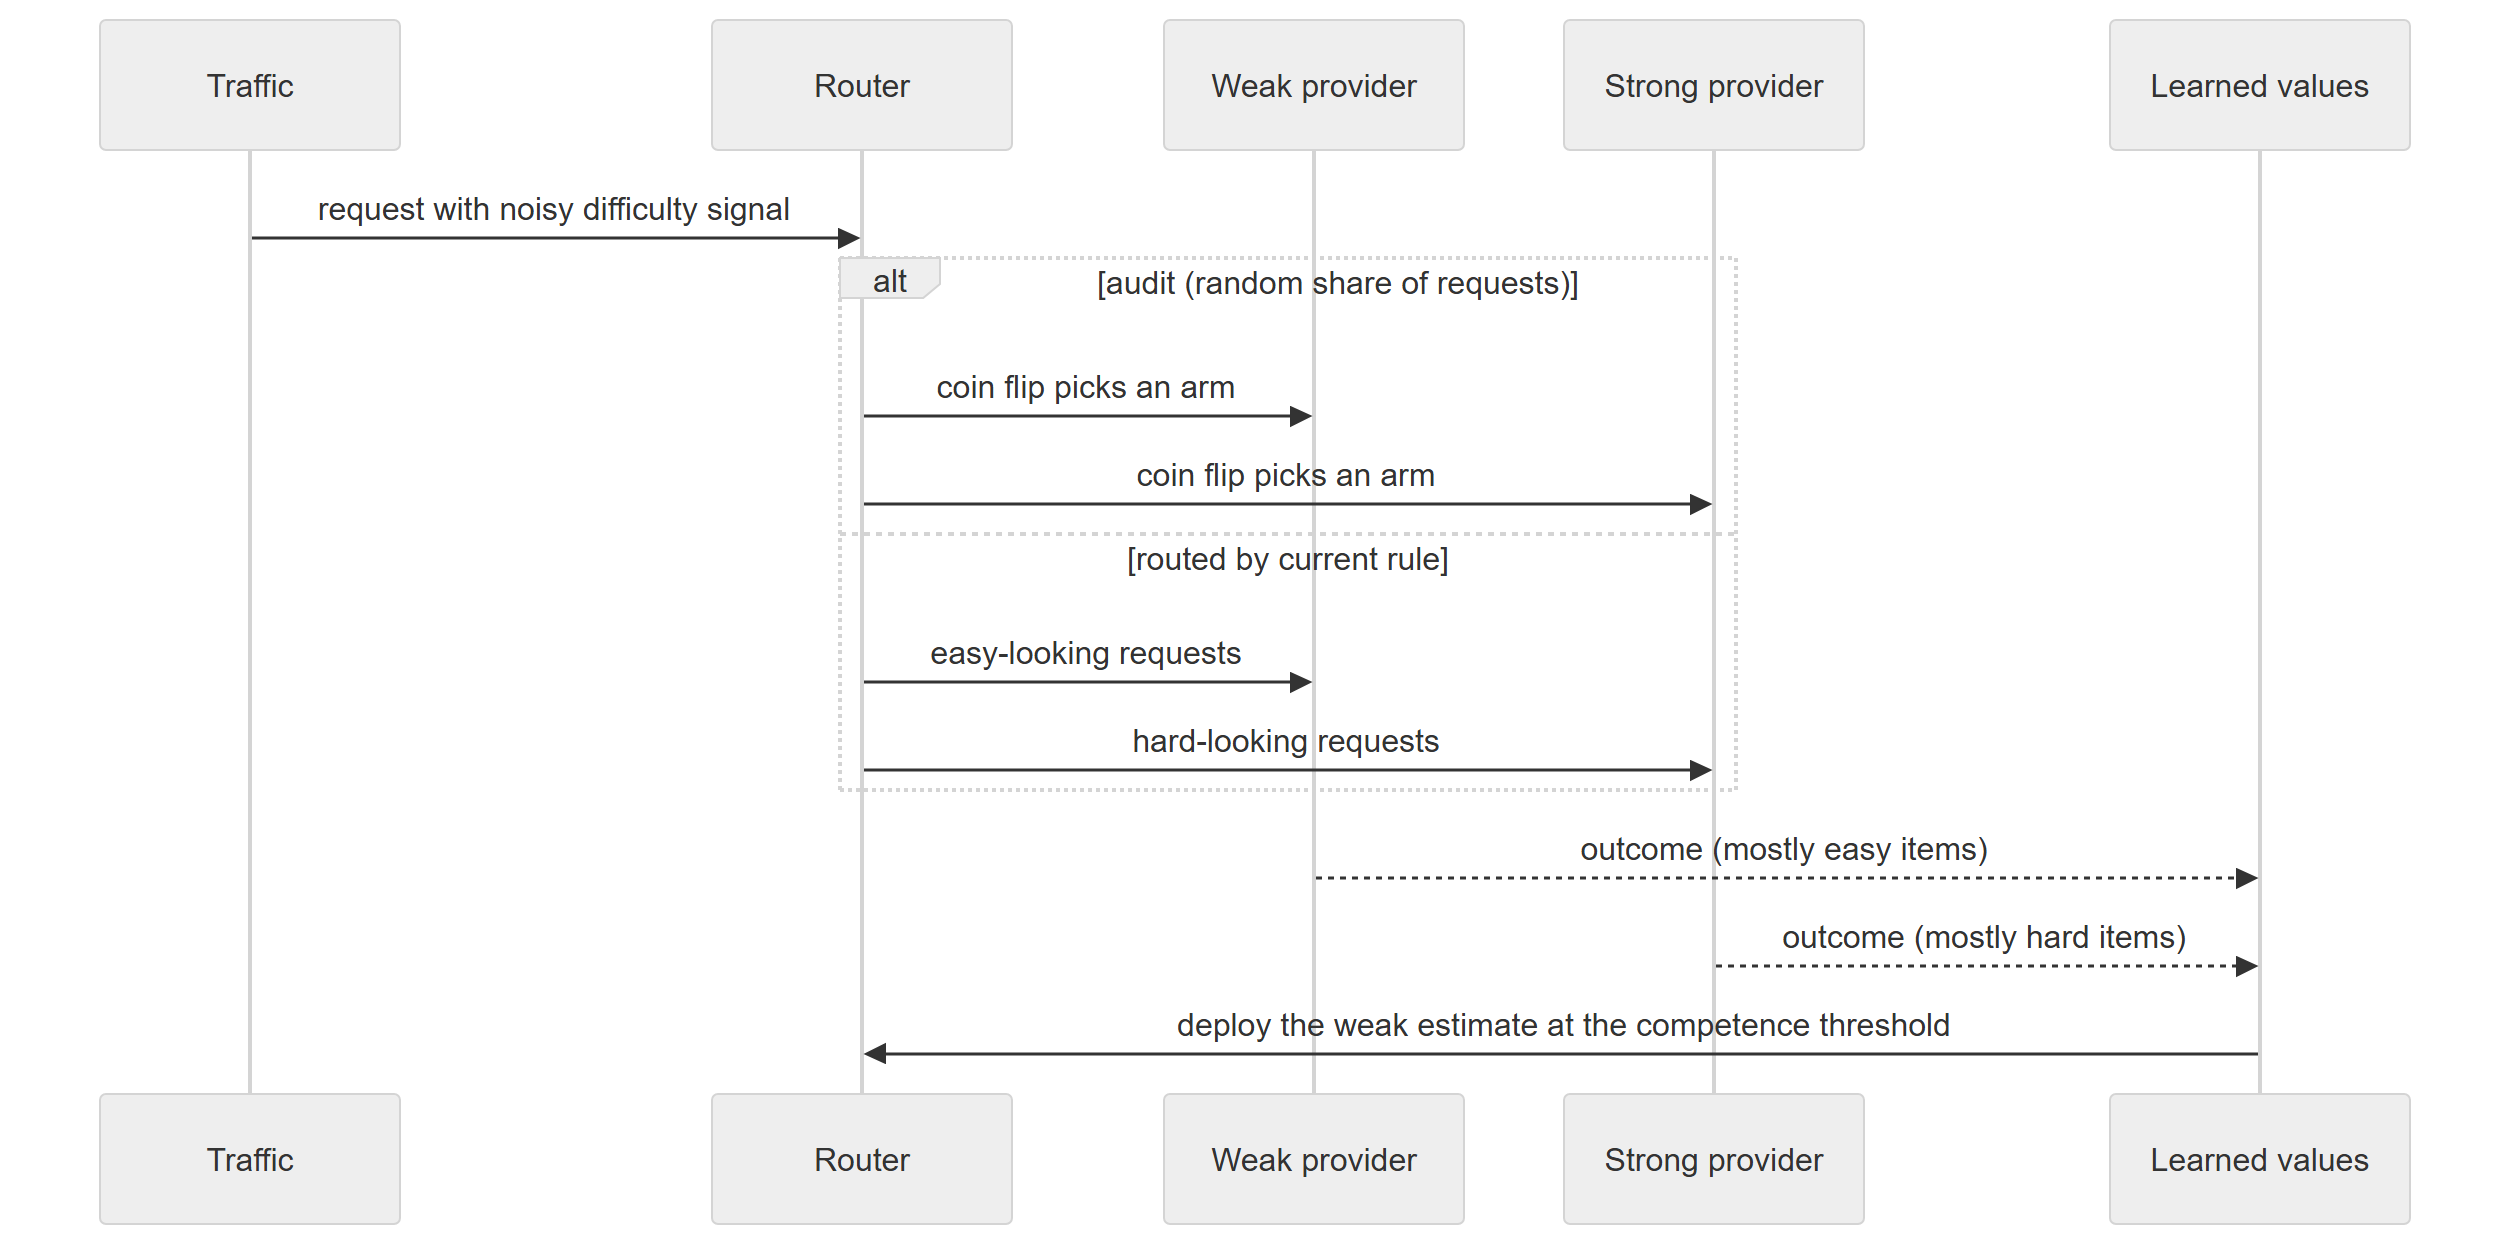
src/arbiter/learning_router.py simulates two providers, weak and strong, with assumed difficulty-scaled accuracies. Phase 1 routes requests by a noisy difficulty signal (the weak provider is chosen when its predicted accuracy at the signal clears 0.80) and learns each provider’s value only from the items routed to it. A fraction of requests, the audit, is instead sent to a randomly chosen provider. Phase 2 deploys the learned weak-provider estimate on fresh traffic.
Be clear about what Phase 2 is. It is not a per-request router. It reads one number, the learned weak estimate, and if the number clears 0.80 it sends all fresh traffic to the weak provider, otherwise all of it to the strong one. That is deliberately crude: it isolates the question “does the learned value cross the threshold?” from every other router design choice. It also means the deployment outcome flips abruptly, which the fourth point below returns to.
from arbiter.learning_router import LearnedValue
# 1. The bias mechanism: weak only ever sees easy items.
print("1. why the estimate is biased (hand numbers)")
weak = LearnedValue()
for outcome, d in ((True, 0.1), (True, 0.2), (True, 0.3), (False, 0.6)):
    weak.correct += outcome
    weak.n += 1
print(f"   weak saw easy items -> estimate {weak.estimate:.2f} (true marginal 0.68)")
# 2. An audit gives weak a representative sample.
print("2. the audit fixes the estimate")
weak2 = LearnedValue()
for outcome in (True, True, False, False, True, False, False, True):
    weak2.correct += outcome
    weak2.n += 1
print(f"   weak sees mixed items -> estimate {weak2.estimate:.2f}")
1. why the estimate is biased (hand numbers)
   weak saw easy items -> estimate 0.75 (true marginal 0.68)
2. the audit fixes the estimate
   weak sees mixed items -> estimate 0.50
These two blocks use hand-typed outcomes, not simulated ones. Four easy outcomes give 0.75 against a true marginal of 0.68 that the code comment supplies; eight mixed outcomes give 0.50. They show the direction of the effect with numbers small enough to check by eye, and nothing more. The measured effect is the next section.
The sweep
run_ch31.py varies the audit fraction from 0 to 0.25 (n=8,000; curves and competence threshold in every row). results/ch31.jsonl:
| audit | weak estimate | weak marginal | bias | deploy accuracy | regret vs oracle |
|---|---|---|---|---|---|
| 0.00 | 0.864 | 0.673 | +0.190 | 0.680 | 0.238 |
| 0.05 | 0.861 | 0.673 | +0.188 | 0.682 | 0.236 |
| 0.10 | 0.844 | 0.673 | +0.171 | 0.684 | 0.234 |
| 0.25 | 0.791 | 0.673 | +0.117 | 0.949 | −0.031 |
Oracle accuracy is 0.918. This is a single run per row (one seed, n=8,000), so no interval is reported, and differences in the third decimal between the first three rows are not distinguishable from noise here. “Regret vs oracle” is oracle accuracy minus deployment accuracy.
What the results show
-
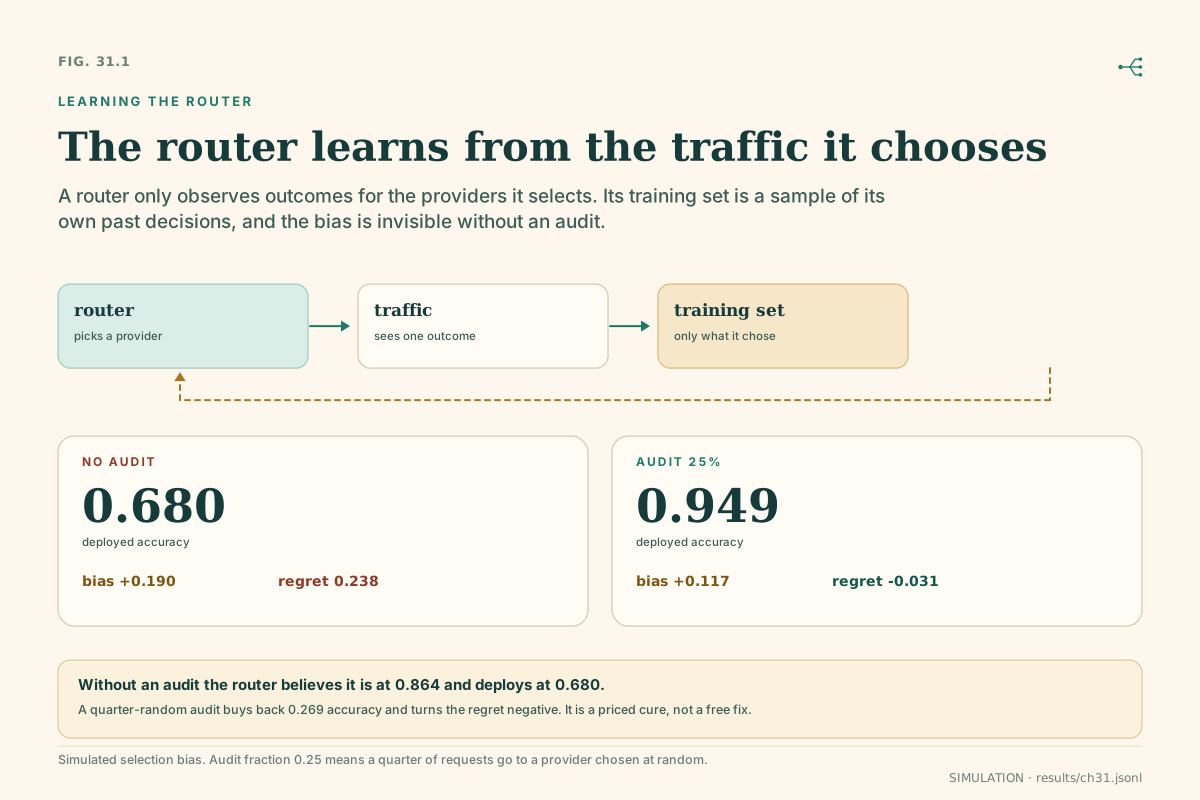
The self-reinforcing failure is real and measurable. With no audit, the router’s learned value of the weak provider is 0.864 against a true marginal of 0.673, an optimism of +0.19, because weak only ever sees the easy items the router sends it. Deploying that belief sends all fresh traffic to weak and lands at 0.680, the lowest accuracy in the sweep and 0.238 below the oracle. The router’s own policy created the data that confirmed the policy. The prediction’s first half holds in this simulation.
-
The audit is a priced cure, and a partial one. Every audit point pulls the weak estimate towards its marginal (bias +0.190 → +0.117) but not to it: even at 25% audit, three quarters of the weak provider’s data are still easy-skewed. The estimate falls below 0.80 only at the last point, which flips the deployment to the strong provider and 0.949. The audit also has a cost the table hides: audited requests are routed at random, so they are served worse than routed ones. The benefit is in the model, not in the audited traffic.
-
The negative regret is a warning about the oracle, not a victory. −0.031 means the deployment beat the “oracle”. That oracle is defined as the cheapest provider whose accuracy at true difficulty clears 0.80, not as the accuracy-maximising choice. Sending everything to the strong provider (accuracy about 0.945 on this curve) exceeds it. So at audit 0.25 the router is not outperforming an ideal one; it has stopped being cost-aware. This deployment ignores cost: weak costs 1 and strong 20, and no saving is claimed. A cost-aware deployment is Chapter 33’s problem.
-
The abrupt flip is an artefact of the single knob. Between audit 0.10 (estimate 0.844, all traffic to weak) and 0.25 (0.791, all to strong) the deployment jumps. That is the competence threshold’s behaviour on a scalar estimate, and it is reported as such, a swept assumption and not a finding about audit. The sweep also has no point between 0.10 and 0.25, so where the flip occurs is unknown.
Wrong / Correct. Wrong: “A router learns its providers from the outcomes it sees.” Correct: “A router learns every provider it sends traffic to, and learns nothing trustworthy about the ones it avoids. The provider values it learns are a function of its own routing, and the correction — an audit sample — is a tax paid on purpose to see the arms it does not choose.”
What this means for the decide construct
PROPOSED. If a decision’s provider is chosen by a learned router, the evidence ledger (Chapter 26) must record not only what was answered but whether the routing was random. Otherwise the logs cannot later be used to learn a router without the bias this chapter shows. That is a requirement on the runtime’s record, not on the syntax of decide. It also makes “audit fraction” a runtime policy knob with a price, which Chapter 33’s compiler would have to set or expose.
What to carry forward
Chapter 30’s cascade needed an uncertainty signal; Chapter 29’s router needed provider profiles. This chapter adds the meta-lesson: if the router learns its own signals, it must audit, because selection confounds its training data. Chapter 33’s compiler plans from supplied profiles, and if those profiles are learned from routed traffic, the same audit discipline applies. Part VIII’s three simulations therefore end with a single shared dependency: every router, cascade or compiler is only as good as a signal whose provenance must be known.
Limitations
- SIMULATION over assumed curves, noise and audit fractions;
results/ch31.jsonlismode: simulationwith the assumptions in every row. One seed per row; no intervals. - The deferral comparison was checked in Mozannar and Sontag, Theorem 1 and §6.4, and Madras et al., §2.3 and §5. Madras et al. report medians of 5 runs; those runs are external evidence.
- Phase 2 deploys a single scalar estimate to all traffic. A genuinely per-request learned router (a bandit, a classifier over request features) is not simulated.
- The deployment is accuracy-only; cost-aware routing is deferred to Chapter 33.
- The competence threshold is a single swept knob; the 0.10→0.25 deployment flip is its artefact.
- The “oracle” is the cheapest-competent rule, not the accuracy-maximising one, which is why regret can be negative.
- The audit improves the model; the audited requests themselves are served worse on average, the tax, stated.
What this chapter establishes
How should a router learn when its own routing determines what it observes? Under this simulation: with an audit sample, priced and swept, and with cost in the deployment. Otherwise the router collapses to always-strong.