Programming with Decisions
On the evidence, what is a decision model, and is decision a programming primitive?
This chapter is a verdict over the ledger, not an experiment: one mechanical extractor (
run_ch35.py) reads the metadata preregistrations and writesresults/ch35.jsonl; every number below is from that file or from a cited ledger row. No model ran. The hypothesis classification follows one rule set in advance: no hypothesis is decided above INSUFFICIENT_EVIDENCE without a real measured provider.
The question
On the evidence, what is a decision model, and is decision a programming primitive? The book must answer from what it actually measured, and the answer is allowed to be narrower than the investigation set out to build.
What the evidence is
run_ch35.py reads all thirty-five chapters’ metadata. The mechanical
snapshot (results/ch35.jsonl, summary row):
1. mechanical snapshot (metadata only)
   chapters 35; with result files 25
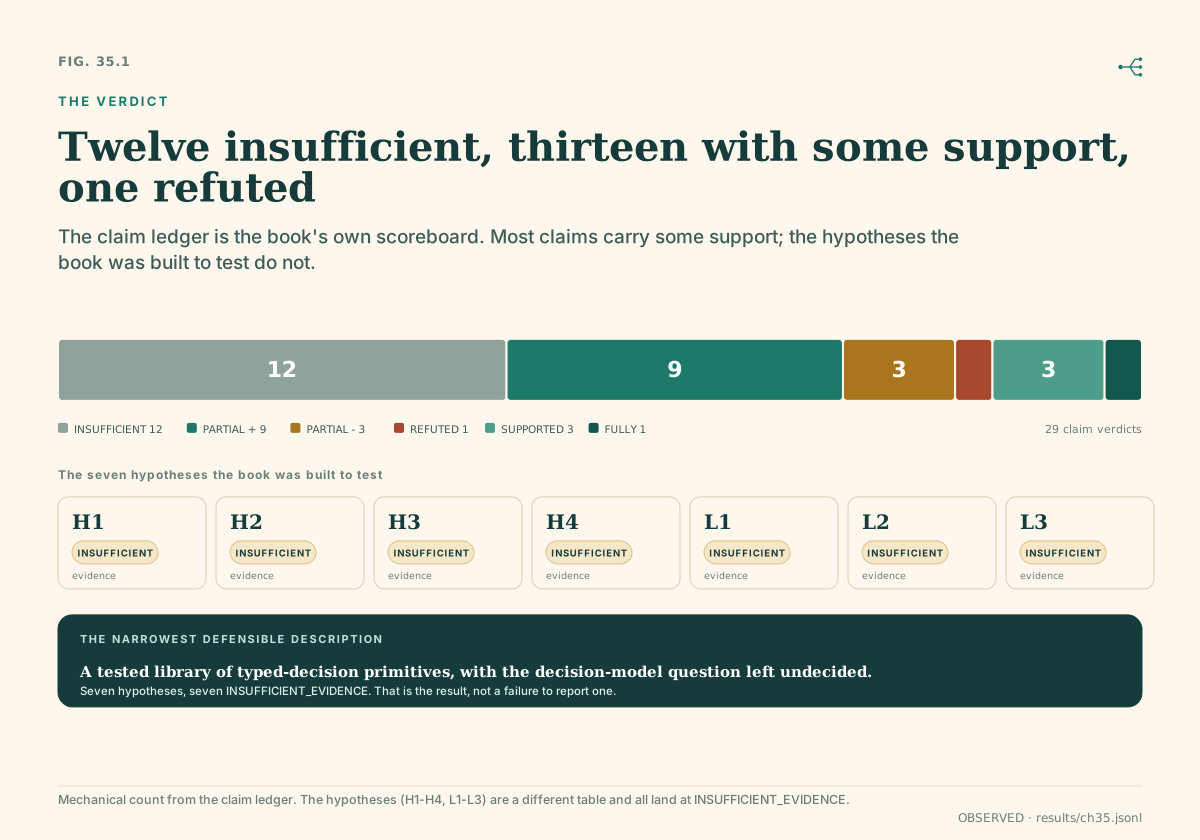
   verdict counts {'INSUFFICIENT_EVIDENCE': 12, 'PARTIALLY_SUPPORTED': 9, 'PARTIALLY_REFUTED': 3, 'REFUTED': 1, 'SUPPORTED': 3, 'FULLY_SUPPORTED': 1}
2. hypothesis verdicts (all INSUFFICIENT_EVIDENCE)
   H1 INSUFFICIENT_EVIDENCE: no trained decision model was measured (Ch7/15/28 deferred)
   H2 INSUFFICIENT_EVIDENCE: bug-class value shown by construction/deterministic tests only (Ch32)
   H3 INSUFFICIENT_EVIDENCE: transfer experiment that would decide it never ran (Ch15)
   H4 INSUFFICIENT_EVIDENCE: no decision family on a measured Pareto front (Ch28 compile-only)
   L1 INSUFFICIENT_EVIDENCE: for decide reduced to library forms (Ch23); survivors' discipline unmeasured
   L2 INSUFFICIENT_EVIDENCE: fail-silently-under-shift behavioural claim unmeasured (Ch17)
   L3 INSUFFICIENT_EVIDENCE: compiler behaviour within supplied profiles only (Ch33)
3. prediction hit-rate framing
   chapter-level experiments with a recorded verdict: 17
   hypothesis-level verdicts above INSUFFICIENT_EVIDENCE: 7 -> 0 by the author's floor
The import and the three step blocks that produce it are in
examples/ch35-programming-with-decisions/walkthrough_ch35.py, shown verbatim
below; the output above is byte-identical to its live run.
import yaml
from pathlib import Path
import sys
# 1. the mechanical snapshot
print("1. mechanical snapshot (metadata only)")
print(f"   chapters {len(rows)}; with result files "
      f"{sum(1 for r in rows if r['has_results'])}")
print(f"   verdict counts {dict(counts)}")
# 2. the hypothesis verdicts, under the author's floor
print("2. hypothesis verdicts (all INSUFFICIENT_EVIDENCE)")
for name, note in HYPOTHESES:
    print(f"   {name} INSUFFICIENT_EVIDENCE: {note}")
# 3. the hit-rate framing: verdict counts, not one number
decided = sum(v for k, v in counts.items()
              if k in ("SUPPORTED", "PARTIALLY_SUPPORTED",
                       "REFUTED", "PARTIALLY_REFUTED", "FULLY_SUPPORTED"))
print("3. prediction hit-rate framing")
print(f"   chapter-level experiments with a recorded verdict: {decided}")
print(f"   hypothesis-level verdicts above INSUFFICIENT_EVIDENCE: "
      f"{sum(1 for _ in HYPOTHESES)} -> 0 by the author's floor")
What the book actually measured breaks into three kinds:
- Real providers, measured — the tuned TF-IDF+LR on 77-way intent (0.8779, Ch4), the zero-shot embedding provider (Ch5), NLI (Ch6), the calibrated and shifted provider rows (Ch10), and the Part VI CPU encoders and cross-encoder on SciFact (Ch21-25). These are OBSERVED.
- Deterministic model-free logic — Ch16-19, 22, 23, 31-34: construct
semantics, validators, routers, the compiler, the semantic program, all
over supplied scores or hand-built stubs. These are ARITHMETIC/
mode: simulation/mode: analyticand are never evidence about a model. - Deferred or compile-only — Ch7’s model sweep, Ch13-15’s GPU runs,
Ch28’s winner table (17 cells from earlier rows; decision-model cells
NOT_OBSERVED). These are PENDING_RUN or inventory.
The hypothesis verdicts
Every hypothesis is classified INSUFFICIENT_EVIDENCE. The reason is the
same across all seven: the hypothesis needs a real measured provider (a
decision model, an LLM judge, a cascade on real traffic), and the book never
measured one — the GPU runs were deferred, and the router/compiler/program
chapters ran on supplied or stubbed numbers. The verdict table (full rows in
results/ch35.jsonl):
| H | Verdict | Deciding chapters | What would have decided it |
|---|---|---|---|
| H1 nothing new | INSUFFICIENT_EVIDENCE | 7, 15, 28 | a trained decision model beating NLI/first-token/classifier on held-out decisions, 3 seeds |
| H2 useful abstraction | INSUFFICIENT_EVIDENCE | 8, 16, 17, 32 | measured bug class + measured provider swap without caller changes |
| H3 general decision capability | INSUFFICIENT_EVIDENCE | 5, 15 | transfer: k diverse tasks > k relabelings of one task |
| H4 compromise region | INSUFFICIENT_EVIDENCE | 28 | a decision family on a measured Pareto front |
| L1 syntax adds nothing | INSUFFICIENT_EVIDENCE | 16, 17, 18, 19, 22, 23 | any surviving construct’s discipline measurably preventing failure |
| L2 uncertainty must be enforced | INSUFFICIENT_EVIDENCE | 16, 17, 32 | enforced vs optional handling differing behaviourally under shift |
| L3 provider selection is compiler’s job | INSUFFICIENT_EVIDENCE | 33 | compiler plans matching real hand-built cascades on real profiles |
The chapter-level rows that did decide something are recorded as chapter
verdicts: Ch23 REFUTED for decide as a construct (its library forms
reproduce it exactly — ledger 23.6), Ch21/22/24 PARTIALLY_REFUTED their
own pipeline predictions, and Ch26, 33, 34 SUPPORTED theirs (graph replay;
the compiler within its profiles; the semantic program’s boundary). Those
verdicts are about constructed or simulated systems and are reported as
such; they are not hypothesis verdicts.
Prediction-versus-outcome
The preregistrations predicted results chapter by chapter; the hit rate is reported as the verdict distribution, not a single number, because the distribution is the honest summary: of the 34 investigated chapters, 12 stand at INSUFFICIENT_EVIDENCE (including unrun provider studies), 17 recorded a chapter-level verdict (9 PARTIALLY_SUPPORTED, 3 SUPPORTED, 1 FULLY_SUPPORTED, 3 PARTIALLY_REFUTED, 1 REFUTED), and every row is mechanical from the metadata (results/ch35.jsonl; Chapter 35 is the summary itself and is not counted). The remaining 5 chapters have no recorded chapter-level verdict; this does not mean they contain no measurements. The 12 + 17 + 5 categories account for all 34 investigated chapters. The book was surprised where it tested: Ch22’s risk-controlled decision filter covered 2.6% of threshold pairs and reached end-to-end 0.202 (a P3 refutation), Ch23’s construct was rejected, Ch24’s product rule was refuted by its own arithmetic, Ch30’s cascade accuracy proved to depend jointly on every stage’s threshold (so per-stage numbers cannot be multiplied into an end-to-end guarantee), and under the supplied profiles Ch33’s cascade was Pareto-dominated. Where the book only designed, it was not surprised — because it did not test.
Protocol deviations are part of the record: Ch21’s run predated its preregistration edit (disclosed in that chapter and its metadata); Ch28 selected best-of-config on test (disclosed — an inventory, not a leaderboard); Ch34’s sampling seed deviated from its prereg placeholder (disclosed). Each was reported, none was hidden; that is the extent of what the ledger would have been accused of and what the audit below checks.
The audit (leakage, underspecification, weak baselines)
Three papers frame the self-audit: Kapoor & Narayanan (2207.07048) on data leakage; D’Amour et al. (2011.03395) on underspecification; Lipton & Steinhardt (1807.03341, reused from Ch4) on scholarship trends. The audit’s conclusions:
- Leakage — the strong item is the SciFact dev-set reuse. The same 188
labelled SciFact dev claims served as the
testsplit in Chapters 21, 22, 23 and 25. Each chapter touched it once and counted the touch, but across Part VI it behaved as a development set: later designs (which filter, which threshold, the Part VI pivot) were informed by earlier results on it. What that does to the Part VI claims: they are pipeline results on one corpus, positively selected by a process that saw the target; they are NOT evidence about Jev or H1-H4 (the chapters already say this), and their internal comparisons (filter vs filter, cascade vs single) must be read as within-corpus, not cross-corpus. A second, weaker item: most label and wording variants were authored by one writer with the chapter’s claims in view (Ch5 reports the 13-29 point wording swings, which is the mitigation, not the cure). - Underspecification — present and measured. D’Amour’s point is that predictors equal on held-out behave differently deployed; the book’s strongest analogue is Ch10: calibration that held in-distribution degraded under shift for every measured provider, and conformal coverage set for a nominal 0.90 fell to median coverage 0.5687/0.5611/0.8550 across fit seeds on the safety shift split (ledger 11.9/11.10). Equal-in-distribution does not mean equal-deployed; the book says so where it measured it.
- Weak baselines — engaged, not always fixed. Ch4’s majority bar is the boring baseline; Ch28’s table is honest about NOT_OBSERVED cells; but the fact that 15 of 17 filled Ch28 cells reprint Ch4/Ch5/Ch6 rows means the “where the tiny classifier wins” section is thin, and the LLM-judge and decision-model sections rest on NOT_OBSERVED — the audit says plainly the headline comparison the table invites is not supported by it.
The leakage audit draws on Kapoor and Narayanan’s taxonomy (§2.4) and D’Amour et al.’s method (§2.3-§4). Kapoor and Narayanan define eight leakage types and a “model info sheet” that asks authors to justify three arguments: a clean train-test separation, legitimate features, and a test set drawn from the distribution of scientific interest (§3.2). Applying the eight types to this book, with what was checked and what was not:
| Type (Kapoor and Narayanan) | Where it could apply here | Status |
|---|---|---|
| L1.1 No test set | Part VI reused the 188 SciFact dev claims as test across four chapters and informed later designs with earlier results |
Present, as described above: the claims behaved as a development set |
| L1.2 Pre-processing on train and test | Fitted vectorisers and scalers | The linear provider fits its TF-IDF vectoriser inside fit on the texts it is given (src/arbiter/providers/linear.py), so it sees only training texts when called as the harness calls it. Not audited for every chapter’s script |
| L1.3 Feature selection on train and test | Thresholds and hyperparameters | Chapters 4-10 choose them on calibrate or threshold splits by design, and Chapter 4 records a test-touch count. Part VI’s reuse above is the exception |
| L1.4 Duplicates | Near-duplicate texts across splits (Banking77, SciFact claims) | Not checked. No deduplication step was found in the harness; nobody looked for duplicates in the data |
| L2 Illegitimate features | A feature that encodes the label | None known. The Chapter 25 relation baseline reads only claim and evidence text. Not exhaustively audited |
| L3.1 Temporal leakage | Training on the future | Not applicable: the datasets are static and no model was trained on time-ordered data |
| L3.2 Non-independence of train and test | Claims sharing evidence documents; one author writing label wordings with the claims in view | Possible, not measured. SciFact claims can cite overlapping documents, and the second item is the weaker one named above |
| L3.3 Sampling bias in the test distribution | The test set is not the distribution of interest | Present and verified for Part VI. The 188 claims are those with gold evidence, so NotEnoughInfo never occurs (the Chapter 25 confusion matrix has only SUPPORT and CONTRADICT rows). Results say nothing about claims with no evidence |
Two of eight types are present, one of them (L3.3) newly named by this table; one is not applicable; and for two (L1.4, L3.2) the honest answer is that nobody looked. That matters more than the count: an audit that finds what it did not check is more useful than one that reports clean.
D’Amour et al. add the stress-test idea this book already uses in one place. Their method is to retrain with arbitrary changes such as the random seed, confirm near-equal held-out performance, and then see whether stratified, shifted or contrastive tests separate the models (§2.3, §4). Chapter 9 and 10’s shift split is a shifted evaluation of exactly this kind. The book did not retrain across seeds to see whether its providers are underspecified in their sense, so the claim above is that the book shows the consequence of equal-held-out and different-shifted, not that it ran their test.
What would not survive the audit: every Part VI number read as evidence
about decision models (they are pipeline results); every Ch29-33 number read
as a finding about real routers, cascades or compilers (they are consequences
of supplied, mostly assumed profiles); and any sentence that turned a
probability into a certainty — the ledger rows the audit script checks are the
guard against that. The mechanical check is python examples/audit_claims.py,
which verifies that every ledger row citing a results/chNN.jsonl selector
points at an existing row.
The ten questions
- Is a “decision model” distinct from known categories? INSUFFICIENT_EVIDENCE — no decision model was measured; the categories’ competition was only partially probed (Ch6: NLI lost to embeddings).
- Is “decision” a useful abstraction anyway? Argued and built (typed answers, mandatory uncertainty, provider independence; Ch8, 16-19, 32); as a measured claim, INSUFFICIENT_EVIDENCE — the bug-class value is construction/deterministic evidence (Ch32’s 5/5).
- First-class constructs or library calls? Mixed, and decided construct by construct: Ch23 rejected
for decide(library form);if decide,match decide,where decidesurvived as library compositions with enforced semantics. - Which syntax survived?
decide(Ch16),if decide(Ch17),match decide(Ch18),where decide(Ch22, typed and abstaining — LOTUSsem_filter, narrower). Survival required tested code, mandatory arms/ties, and honest prior-art placement. - Which construct was rejected, by which rule?
for decide(Ch23): its three candidate differences (lazy order, early stop, ranked iteration) each had an exact library equivalent (filter,takewhile/any,sorted); equivalence was measured over supplied scores; rejection is a result, not a failure. - Which provider per decision family? As measured: tuned LR for closed intent sets (0.8779, Ch4); embeddings for unseen labels (Ch5); the cross-encoder for relevance over the Part VI corpus — and nothing beyond that. Ch28’s table is an inventory with honest NOT_OBSERVED cells.
- What role do embeddings play? Candidate generation and cheap filtering (Part VI): retrieval over-recalls, decisions filter (Ch21-22); retrieval error is separate from decision error and each is reported separately.
- What role do generative LLMs play? Never measured here. The router/cascade/chapters (Ch28-33) treat them as supplied-profile entries only; the 2.6%-coverage risk-filter result (Ch22) is the closest the book came to an LLM-free operating-point lesson.
- How should uncertainty propagate? By construction: abstention is a first-class outcome (Ch11), match ties resolve to CONFLICTING_EVIDENCE (Ch18), the product rule does not compose (Ch24), a cascade’s end-to-end accuracy is a mixture over stages that depends on every threshold, so per-stage risk control does not give an end-to-end guarantee (Ch30) — propagation must carry distributions, not point wins; unmeasured as a behavioural claim (L2).
- What exists now that did not exist before? See the narrowest description below.
Four lists
What Jev gave us — the provocation and the terminology (decision models, typed decisions); the reason the investigation existed. Nothing measured here confirms or refutes its claims.
What existing ML already provided — classification (Ch4 LR bar), zero-shot embeddings (Ch5), NLI (Ch6), calibration maps (Ch10), conformal prediction (Ch10), BM25 and cross-encoders (Part VI), contextual bandits (Li et al. §4: the audit sample’s unbiasedness needs random logged traffic), cost-based optimisation (Selinger 1979; Palimpzest), declarative pipelines (Ludwig, Cedar, DSPy, LOTUS, DocETL, Palimpzest), agent loops (ReAct, PAL, Toolformer).
What this book discovered — measured: calibration degrades under shift for every measured provider; conformal coverage falls under shift; zero-shot wording swings results 13-29 points; the risk-controlled decision filter covered 2.6% of threshold pairs; in the simulated cascade the end-to-end accuracy is a traffic-weighted mixture of stage accuracies (0.830 measured; the product of stage accuracies, 0.577, is the wrong formula), so its guarantee cannot be read off per-stage numbers; the Part VI filter choice matters more than the syntax. Constructed: the Arbiter library (contract → types → control → match → abstain → calibration → retrieval → pipeline → graph → router → cascade → spec → compiler → semantic program), the Chapter 26 replay graph (provenance, why/where, drift by state hash, correct on chains), the decision-spec validator (5/5 seeded bug classes written by its author), the semantic program with its permit/deny/escalate boundary and 0 free-text decisions against an analytical ReAct count. Mechanical: a prediction-versus-outcome table every chapter contributed to.
What remains speculation — every H1-H4 and L1-L3 verdict; every Ch29-33 number as a statement about real systems; the shared-hidden-state hypothesis (Ch13, 27); the compression thesis (Ch14-15); hosted Jev’s behaviour; the judge/cascade/decision-model columns of the Ch28 table.
The SciFact disclosure, stated plainly
The same 188 labelled SciFact dev claims served as the test split in
Chapters 21, 22, 23 and 25. Each chapter touched it once and counted the
touch, but across Part VI it behaved as a development set: later designs were
informed by earlier results on it, so the Part VI comparisons are
within-corpus and positively selected on the target. They are pipeline-level
results about retrieval and filtering on one corpus; they are not evidence
about Jev or about H1-H4, and the strength of the Part VI claims is
correspondingly the strength of a single-corpus development-set experiment —
stated here so Chapter 35 cannot be read otherwise.
Defects found in review
A review pass read the later chapters against their own code and results. It found problems that a first reading of the evidence missed. None changes a hypothesis verdict, since all seven stand at INSUFFICIENT_EVIDENCE, but they change how much weight some chapter-level results can bear:
| Where | Found | Effect on this chapter’s reading |
|---|---|---|
| Ch30 | The “naive product” was read as evidence that independence fails. End-to-end cascade accuracy is a traffic-weighted mixture of stage accuracies (checked on every row); the product is the wrong formula | The sentences above about composition are restated: per-stage numbers cannot be read as an end-to-end guarantee because each stage’s accuracy depends on every earlier threshold |
| Ch25 | The lexical relation baseline never predicts SUPPORT, though 124 of 188 gold labels are SUPPORT; always-SUPPORT scores 0.660, the baseline 0.197 | “Errors concentrate in relation” is largely a property of that baseline |
| Ch26 | The state hash covers all earlier-recorded decisions; replay hashes in topological order. When the orders differ, a deterministic replay reports false drift (an xfail test pins it) |
Replay results hold for chains, which is what the study and the headline numbers use. The semantic program of Ch34 branches; its replay categories should be re-checked after any fix |
| Ch32 | The validator’s B2 missed an unknown first fallback and non-adjacent repeats; B3 missed duplicated names; B5 missed an empty handler. Fixed; 5/5 on the seeded bugs unchanged | The 5/5 shows the checks do what their author intended; remaining gaps are listed in Chapter 32 |
| Ch33 | The linear profile was labelled as seeded from the measured 0.8779 but its curve is the Ch30 assumed one | Cascade dominance holds under supplied profiles only |
| Ch28 | The best-of-config winner table had already been disclosed as selection on test; the capability map was added | The table is an inventory and not a leaderboard, as already stated |
A practical test the book did not run
The question that most readers will bring to this book is whether a decision API earns its place in an application. The book measured pieces of that answer (accuracy, calibration, abstention, routing cost) on public data, with stand-in providers. It did not run one workflow end to end with the quantities a deployment would weigh together: accuracy, coverage, escalation rate, latency, and what the downstream action costs when a decision is wrong. The refund workflow that opens Chapter 1 is the natural candidate, and Chapter 34’s permit, deny and escalate boundary is the shape such a test would use. PROPOSED, not planned: a follow-up with preregistered acceptance criteria and a real provider, which the paused-run decision currently prevents. Until then, the narrowest defensible description below is all the book can claim.
Constructs: survived and rejected
| Construct | Verdict | Ledger |
|---|---|---|
decide |
survived | 16.x |
if decide |
survived (mandatory arms) | 17.7 |
match decide |
survived (mandatory uncertain arm, tie rule) | 18.x |
where decide |
survived as the typed, abstaining filter | 22.8 (LOTUS sem_filter, no novelty) |
for decide |
rejected — library filter/takewhile/sorted |
23.6 |
The narrowest defensible description
On the evidence of this book, the thing that was built is:
A tested library of typed-decision primitives — an answer contract with mandatory uncertainty handling, abstention, calibration against shift, decision graphs with replayable provenance, a declarative decision spec with a validator, a cost-based compiler over supplied profiles, and a semantic program with a permit/deny/escalate runtime boundary — together with measured CPU results showing that calibration and coverage degrade under shift, that zero-shot wording swings accuracy, and that on one small corpus a typed cascade retains evidence on 0.601 of queries versus 0.606 for the full cross-encoder, using 940 versus 1,880 cross-encoder passes. Every tested filter still drops substantial retrieved evidence; the book establishes no small-loss advantage over keeping all candidates. Claims about decision models remain undecided for lack of a measured one.
That is narrower than the book set out to build, and it is what the ledger
supports. The book’s one rule-protecting result stands on its own: for decide reduced to library forms, and the surviving constructs earned their
place with tested code, not with syntax.
Wrong / Correct. Wrong: “The book showed how to program with decisions.” Correct: “The book showed how to program with typed decision objects, and was honest that the question the title asks — whether decision deserves to be a programming primitive in the Jev sense — is left INSUFFICIENT_EVIDENCE: the syntax that survived is the part the tests paid for, and the constructs that need a real decision model to justify them are the ones the book could not measure.”
Limitations
- Everything above is a summary of prior chapters; no new measurement was
made this chapter beyond the mechanical extractor (
results/ch35.jsonl). - The hypothesis verdicts follow the rule stated at the top; a reader who counts construction and deterministic tests as evidence would move H2 and L1 partially up, and the chapter says so rather than hiding the judgement.
- D’Amour (2011.03395) and Kapoor (2207.07048) are used for the sections named; Lipton (1807.03341) for §1 and §5.1, as in Chapter 4. The audit uses their framing, not their full taxonomies.
- The prediction-versus-outcome table is a verdict distribution, not a single hit-rate number; the distribution is the honest summary and is stated as such.
- Assumptions inherited from earlier chapters were re-checked in a final audit; any check that failed is listed in the repository’s audit record.
What this chapter establishes
What did we build that did not exist when the investigation began? A replayable decision graph with why/where provenance, a spec validator that catches bugs a library call cannot, and a semantic program with a permit/deny/escalate boundary running on the surviving construct set — all tested, all model-free, and all narrower than the question they were built to answer.