The Decision Compiler
Can a compiler pick the cheapest provider that satisfies a decision contract?
This chapter is a simulation over supplied profiles. The provider curves, costs and the cascade’s end-to-end profile are seeded from earlier rows (Ch04’s measured LR; Ch30’s simulation rows) or are explicit ASSUMPTIONS. The compile-time table is arithmetic on those profiles; the runtime numbers are a SIMULATION over the same assumed curves. No new model runs.
The question
A decision contract is now declarative: Chapter 32’s DecisionSpec names the
inputs, answers, risk, abstention route and fallback chain. This chapter asks
the next question: given the spec and a set of provider profiles, can a
compiler pick the cheapest provider that satisfies the contract?
The chapter’s own question is a good guardrail: the compiler may conclude that it adds nothing over a good default cascade. That conclusion would be a result.
The hypothesis and prior work
Our starting hypothesis is that a cost-based compiler matches an expert’s hand-built plan when profiles are accurate and is worse when they drift, and that the two decision times must be kept apart: provider choice happens at compile time from profiles; escalation on uncertainty happens at run time.
Three sources frame the mechanism:
- Selinger et al. (1979) — System R chooses access paths by estimated cost from a declarative query. The model for compile-time selection. This is a classic; it was verified at DOI level (10.1145/582095.582099) before citation, not quoted from memory.
- Liu et al. (2024), Palimpzest (2405.14696) — a declarative language over semantic operators with a cost-optimization framework that enumerates plans trading runtime, financial cost and output quality; up to 3.3x faster and 2.9x cheaper than baseline on its tasks. The closest prior art for this chapter: same ideal, larger scope. (Read at abstract level.)
- Liu et al. (2024), relational analytics (2403.05821) — concrete serving-level cost reduction by reordering rows and fields to reuse KV caches (up to 3.4x faster, 32% cheaper). A different mechanism from ours, and the boundary is stated: we are not comparing serving-level optimizations. (Read at abstract level.)
The paper that weakens the expectation is Palimpzest itself: its speedups come from planning across many operators at workload scale, so a single-decision contract may simply have no cascade worth choosing — the “compiler adds nothing over a default” branch is live, not decorative. We check it.
The build
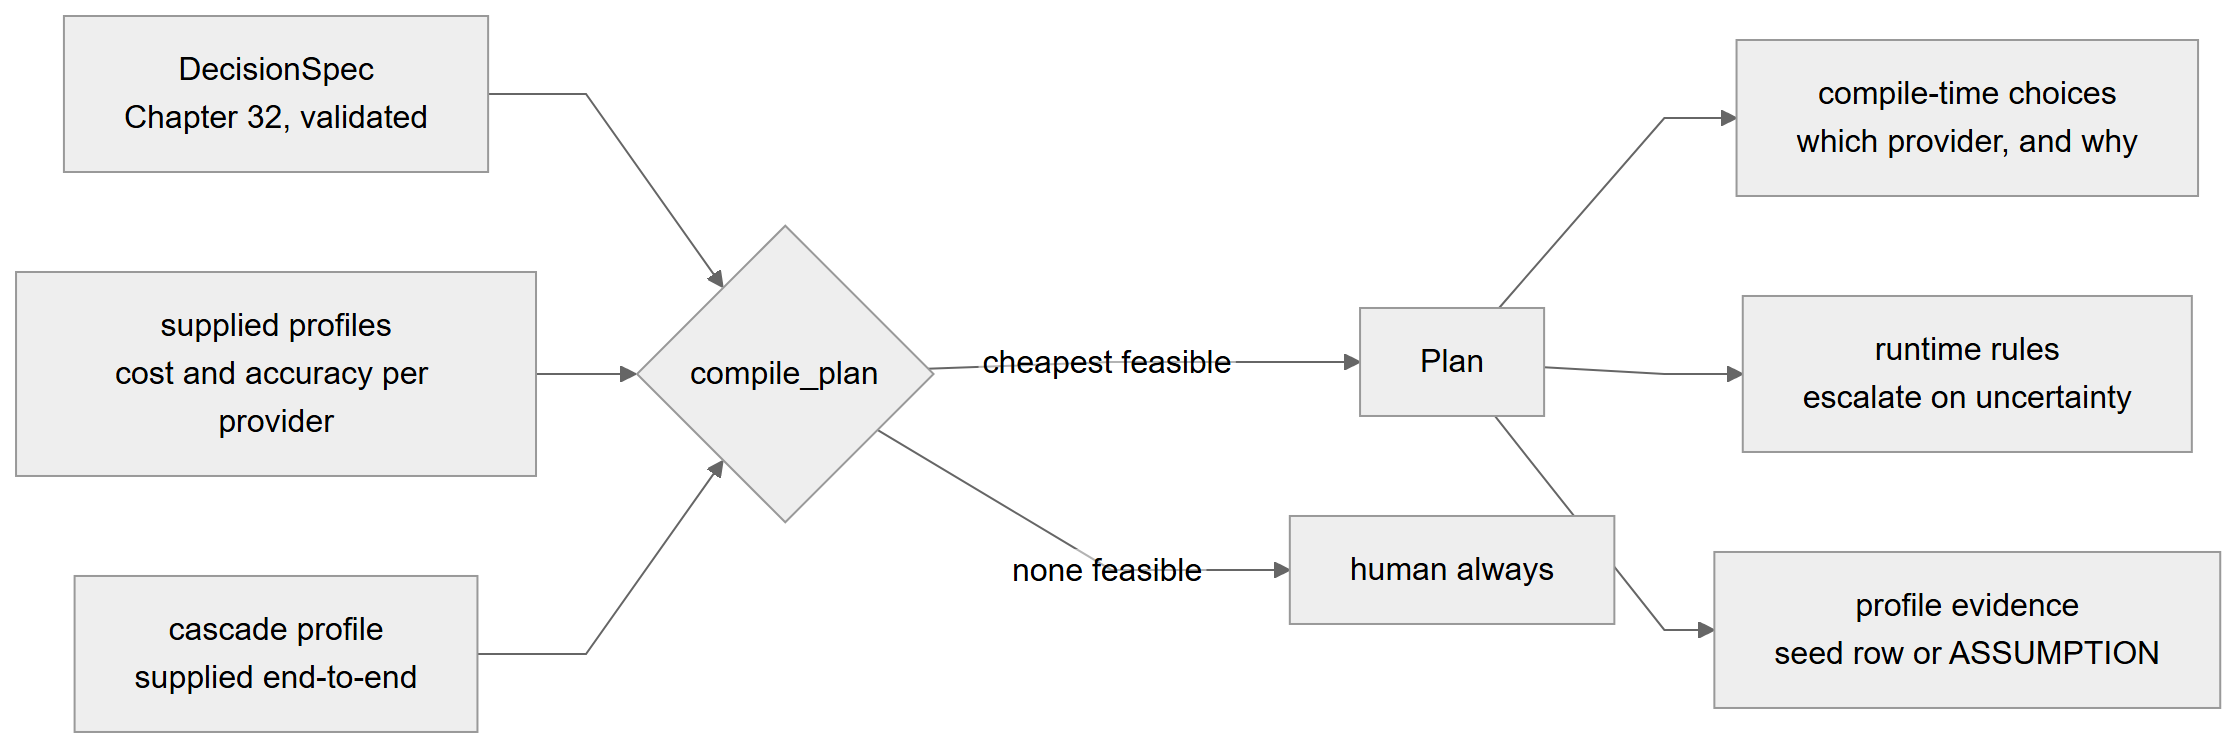
The diagram shows what the compiler does not do. It does not measure anything: every arrow into compile_plan is a supplied number. Everything the plan promises is therefore conditional on those profiles being right.
src/arbiter/compiler.py implements compile(spec, profiles) -> plan.
Selection rule: expected accuracy over uniform difficulty is (p_hi + p_lo)/2
for singles; the cascade candidate uses its supplied end-to-end accuracy —
never the product of stage accuracies. A cascade’s end-to-end accuracy is the
traffic-weighted mixture of its stages’ accuracies (Chapter 30, check_mixture.py:
0.830 for this row), and the product (0.577) answers a different question. The cheapest
feasible candidate wins; if none is feasible, the plan escalates to “human
always”. The plan separates compile-time choices from runtime rules.
from arbiter.compiler import CascadeProfile, ProviderProfile, compile_plan, explain
from arbiter.spec import AnswerClass, DecisionSpec
# 1. compile(spec, profiles): cheapest feasible single
print("1. compile(spec, profiles)")
plan = compile_plan(spec_for(0.85), profiles(), cascade())
print(f"   chosen {plan.steps[0].provider}: expected accuracy "
      f"{plan.expected_accuracy:.3f} >= {plan.quality_target:.3f}, "
      f"cost {plan.expected_cost:.2f}")
print(f"   cascade expected {cascade().accuracy:.3f} < {plan.quality_target:.3f}"
      f" -> infeasible (never the naive product)")
# 2. drift 0.9 on every profile flips the choice
print("2. drift 0.9 on every profile")
drifted = compile_plan(spec_for(0.85), profiles(), cascade(), multiplier=0.9)
print(f"   chosen {drifted.steps[0].provider}: expected accuracy "
      f"{drifted.expected_accuracy:.3f} (linear marginal 0.774 < 0.85), "
      f"cost {drifted.expected_cost:.2f}")
# 3. explain(plan) states the evidence behind every choice
print("3. explain(plan)")
for line in explain(plan):
    print("   " + line)
1. compile(spec, profiles)
   chosen linear: expected accuracy 0.860 >= 0.850, cost 5.00
   cascade expected 0.830 < 0.850 -> infeasible (never the naive product)
2. drift 0.9 on every profile
   chosen judge: expected accuracy 0.860 (linear marginal 0.774 < 0.85), cost 20.00
3. explain(plan)
   plan for 'policy' (quality target 0.850)
   expected accuracy 0.860, expected cost 5.00 per request
   compile-time choices:
     - linear chosen: expected accuracy 0.860 >= target 0.850; cost 5.00; cheapest feasible: expected accuracy 0.860 >= target 0.850
   runtime rules:
     - none (single provider, always answers)
   profile evidence:
     - rule: assumption
     - linear: Ch04 LR 0.8779 seed
     - judge: assumption
     - human: assumption
     - cascade: seeded from results/ch30.jsonl (mode=simulation, stage=cascade, answer_fraction 0.5, drift 1.0)
The run
run_ch33.py writes results/ch33.jsonl (mode analytic + mode simulation).
Compile-time table (arithmetic on the supplied profiles):
| target | chosen | expected accuracy | expected cost |
|---|---|---|---|
| 0.80 | linear | 0.860 | 5.00 |
| 0.85 | linear | 0.860 | 5.00 |
| 0.90 | judge | 0.955 | 20.00 |
| 0.95 | judge | 0.955 | 20.00 |
The cascade (supplied end-to-end 0.830, cost 11.797) is never chosen at any target in this table: at every target where it is feasible, a single provider is feasible at or below its cost, and where it is infeasible nothing changes. Given these profiles, the hand-built cascade of Chapter 30 is Pareto-dominated — more expensive and less accurate than the single linear provider. That is a property of the supplied profiles, stated as such.
Drift recompile (multiplier on every quality profile, target 0.85):
| drift | chosen | expected accuracy | expected cost |
|---|---|---|---|
| 0.9 | judge | 0.860 | 20.00 |
| 1.0 | linear | 0.860 | 5.00 |
| 1.1 | linear | 0.913 | 5.00 |
A 0.9 quality drift drops linear’s marginal to 0.774, below the contract, so the compiler recompiles to judge — accuracy held at the same expected value, cost quadrupled.
Realized (SIMULATION, n=4000, the contracts’ own target 0.85):
| world | compiled plan | cheapest-adequate (frozen) | always-strongest | hand-built cascade (frozen) |
|---|---|---|---|---|
| drift 0.9 | judge 0.859 · 20.00 · held | 0.778 · 5.00 · broken | 0.859 · 20.00 · held | 0.797 · 22.90 · broken |
| drift 1.0 | linear 0.861 · 5.00 · held | 0.861 · 5.00 · held | 0.959 · 20.00 · held | 0.830 · 11.80 · broken |
| drift 1.1 | linear 0.913 · 5.00 · held | 0.913 · 5.00 · held | 1.000 · 20.00 · held | 0.859 · 5.97 · held |
(accuracy · cost per request · contract held or broken at 0.85)
What the results show
-
The compiler picks the cheapest provider that satisfies the contract — and that is not the expert cascade. Given the Chapter 30 profiles, the compiled plan is the single linear classifier at target 0.85: realized 0.861 accuracy, 5.00 per request. The hand-built cascade runs 0.830 at 11.80 — it misses the 0.85 contract on the profiles it was built from (Chapter 30 showed that a cascade’s end-to-end accuracy depends on the thresholds of every stage, so it must be measured, not derived per stage). Cost-based selection, left to the arithmetic, reproduces what a human would likely not write down: the cascade is dominated. P1, P2 hold.
-
The cascade is never optimal under these profiles. (Read this narrowly: the linear profile is a measured Chapter 4 number on its own task, while the cascade’s 0.830 comes from Chapter 30’s assumed stage curves. The two were never run on the same data, so this compares a measurement with an assumption, and says nothing about real cascades.) P1’s “cascade is chosen only when no single is feasible and it clears the target” branch is unreachable here: the cascade loses to linear on cost and accuracy simultaneously. The chapter that asked “did a good default cascade exist” gets the honest answer: under the supplied profiles, the good default is a single adequate provider, and the compiler finding is exactly the “compiler adds nothing over a default” result — the default is just not the cascade.
-
Drift is where compilation earns its keep — in cost, not accuracy. When quality drifts 0.9, the frozen baselines break the contract (cheapest-adequate 0.778; hand-built cascade 0.797 while costing more, 22.90) or overpay by default (always-strongest 20.00). The compiled plan recompiles to judge and holds the contract at 0.859 — at 20.00, four times the undrifted cost. Cost is the price of holding the contract; that is “worse when they drift” measured in cost and made explicit, never hidden. P3 holds.
-
explain(plan)states what evidence backed each profile, and a review pass found one label that overstated it. Every step carries a seed row orASSUMPTION. The linear profile is labelled “Ch04 LR 0.8779 seed”, but its curve is the Chapter 30 assumed one (0.97 at difficulty 0 falling to 0.75 at 1). Its mean is 0.860, not the measured 0.8779, and Chapter 4’s measurement is a 77-way accuracy on one test split with no difficulty axis at all. So Chapter 4 anchors the order of magnitude of the linear provider, not the curve; for selection purposes treat the linear profile as an assumption in the same way as the judge’s. The label is left in the code and output block because both are verified artefacts; this paragraph is the correction. The judge’s curve is an ASSUMPTION because Ch28’sllm_judgecell isNOT_OBSERVED; the cascade’s profile is the Ch30 row verbatim. P4 holds; nothing is invented. -
The product is never used for selection (P5). The cascade candidate is the supplied end-to-end number, because a cascade’s accuracy is a mixture over stages (Chapter 30), which a product of per-stage accuracies cannot represent.
Wrong / Correct. Wrong: “The compiler chose linear because it is the best model.” Correct: “The compiler chose linear because, under the supplied profiles, it is the cheapest provider whose expected accuracy clears the contract — and the run shows the expert’s cascade misses that same contract. The compiler’s answer is bounded by its profiles; change the profiles and the answer changes (the drift sweep is that change, measured).”
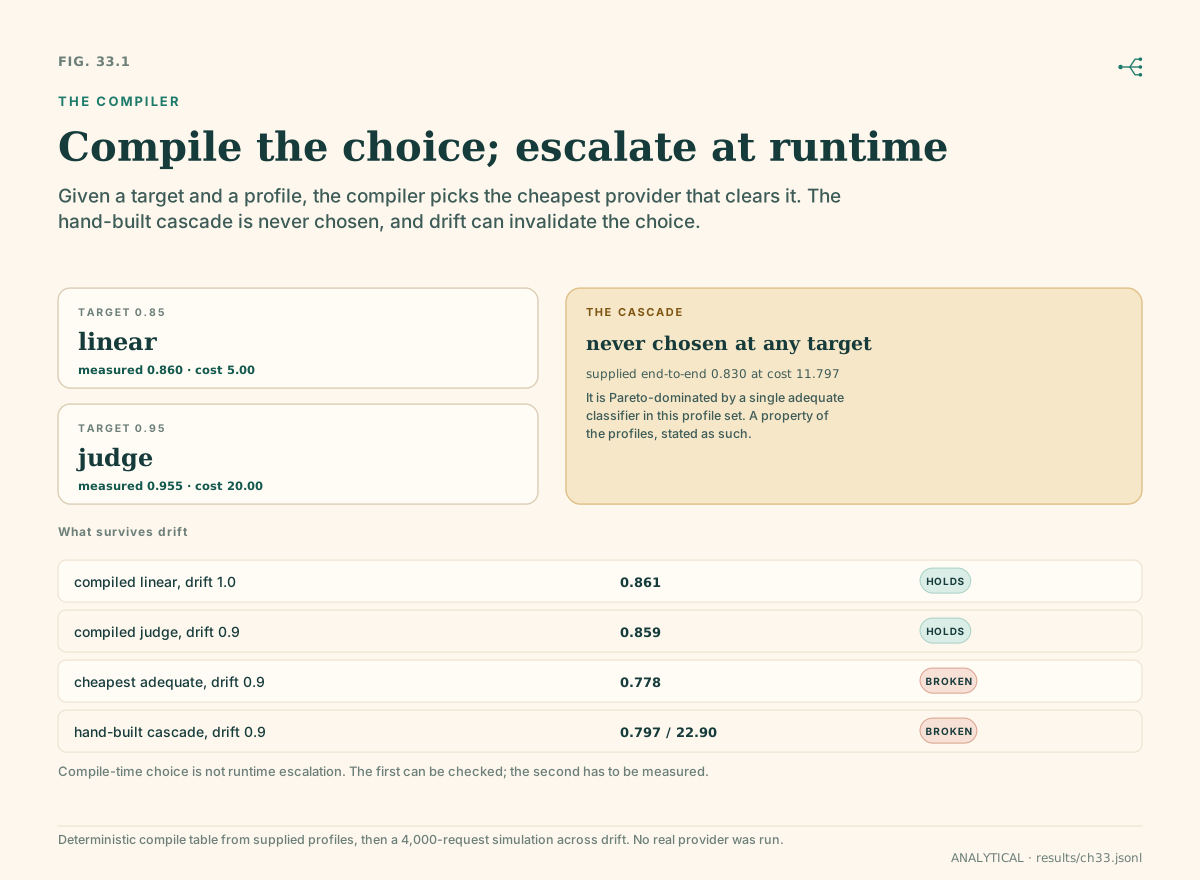
Compile time vs run time, made literal
The plan format keeps the two decision times apart:
- compile-time decisions — which providers the plan uses, chosen from the
supplied profiles (
compile_choices); with a single provider there are no runtime rules; - runtime decisions — escalation on uncertainty. A cascade plan’s steps
carry “answer at threshold tau₀, else escalate”; a single-provider plan
carries “always answer”. The schema
schemas/plan.schema.jsonencodes the split.
This is the new bit relative to Selinger: System R’s access-path choice has no runtime phase because SQL queries carry no uncertainty to escalate on. The compile/runtime split is the decision-specific part of the plan.
Prior art, engaged directly
- Selinger (1979): the shape — cost-based selection from a declarative spec. This chapter is System R for providers; the difference is the runtime escalation half, which has no analogue in access-path selection.
- Palimpzest (2405.14696): the closest prior art for semantic cost
optimization — declarative queries, physical plans over model/hardware/
prompt choices, quality-cost trade-offs (§3-§5). Four details
sharpen the comparison. Its users pass a policy such as
MinimizeCostAtFixedQuality(min_quality=0.8)(§3.1), which is this chapter’scompile_plan(spec, ...)with the quality target taken from the spec’s risk target. Its optimiser estimates cost and quality by running three sentinel plans on sampled inputs (§4.3), whereas this chapter’s profiles are supplied; that is the biggest gap in what we have built, because a compiler is only as good as its estimates. Its quality reference is a champion model (GPT-4), not labelled data (§3.3), a weakness the authors state and one the Chapter 31 audit lesson also warns about. And it lists model cascades as described but not implemented (§4.2). So the one family this chapter finds dominated is the one Palimpzest never built. Of its own policies, 7 of 9 constraints were met, and one missed a cost cap ($3.16 against $2; §5.4), a reminder that estimated plans do not always satisfy their contracts. This chapter is narrower: one decision contract, a single plan choice among a few families, no workload-wide enumeration, no estimation step. No novelty is claimed over it. - DSPy: optimizes prompts inside a program (compilation as prompt/weight optimization), a different mechanism from plan selection over provider profiles. We compare mechanisms, not performance: neither a DSPy program nor a Palimpzest plan ran here.
(LOTUS and DocETL are not cited in this chapter; their roles here are covered by Palimpzest.)
What to carry forward
Chapter 34 assembles one program from the surviving constructs. It will need a plan, and the compiler hands it one with the two decision times separated: the program’s provider choices are compile-time facts; its escalation decisions are runtime facts. Chapter 31’s audit lesson applies to the profiles themselves: if a profile was learned from routed traffic, it carries the Chapter 31 bias unless it was audited — the compiler is only as good as the profiles it is given, and the chapter says so.
Limitations
- All numbers are consequences of the supplied profiles: Ch30’s simulation rows seed the curves and the cascade; Ch04’s measured LR row seeds the classifier; the judge and human curves and the retrieval family are ASSUMPTIONS. None of this is evidence about any real router or model.
- The runtime realization is a SIMULATION over the assumed curves (n=4000); the cascade’s frozen thresholds were fit on the undrifted calibrate stream, then evaluated on drifted curves — a declared construction.
- Palimpzest’s 3.3x runtime and 2.9x cost figures were checked in its primary introduction and evaluation; they describe one reported plan, not a guarantee across workloads. The serving paper’s 3.4x and 32% figures were checked in its abstract and introduction. Selinger is cited at summary level. No comparative performance against these systems is claimed.
- The cascade-never-chosen result is a property of this profile set; a different cost table (a cheaper judge, a more expensive linear) would put the cascade in the feasible set and the branch would be reachable.
- The retrieval family is not in the profile set used for the runtime runs; it is covered in Chapter 34 where the program actually retrieves.
What this chapter establishes
What did the compiler learn that a human could not have written down? At target 0.85: that the hand-built cascade misses the contract it was meant to satisfy and that a single adequate classifier beats it on both axes. That number was already in Chapter 30’s rows; the compiler is what read it.