Similarity Is Not Discovery
When a system puts one piece of information beside another, what relationship is it claiming exists between them? Similarity is only one relation, and it is not the one that usually matters.
Language Outline — Part 1 · Representation
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- When a representation is transformed, how do we decide whether the transformation preserved what mattered?
- Source and meaning units
- Pseudo-text and causal faithfulness
- Preservation obligation
- Fidelity and truth
- Content and function
- Profile and proxy
- Three-valued assessment
- Regular expression and keyword stuffing
- Instrument validation
- Architecture decision record (adr)
Candidate source sections: Declaring what has to survive; The check is an instrument too. These locators do not certify the interpretation.
- Capability introduced
- Defines survival, loss, addition and gain; separates content fidelity from task function.
- Proposed reader control
- Run the existing prepared retry-policy comparison, flawed compression and local correction. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Non-idempotent scope; three total attempts; separate idempotent recovery; unresolved timeouts; consult D-17 before change.
- Important limitation
- Avoid claiming: Claim coverage or wording guards being called semantic acceptance or reader benefit.
- Demonstration or source fallback
- Open the prepared Language companion
Reference implementation example: npm run example:ch10; supplied/scripted inputs, not a browser feature.
- Actual implementation
- Website: PREPARED_CHAPTER10. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Prepared example
A prepared website companion exists for this chapter only. Existing offline tests cover structural behavior, not independently judged semantics. No live model result is implied.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
The sidecar has a regular guest, and it is an embarrassing one. A researcher is reading a paper on retrieval evaluation and opens the side panel. Ranked first is a paper with nearly the same vocabulary: the same benchmarks, the same metrics, the same dataset family. She opens it. It contributes nothing to her present question: same conclusions, weaker experiments, no new evidence, no disagreement, no useful extension. In the index it is a close neighbour. For this researcher’s task, it is a poor recommendation. The retrieval mechanism may have ranked exactly what its similarity objective rewarded, but that is not the same as doing the discovery job well. Here “discovery” means helping the reader find what they actually need. Nor would novelty alone guarantee value. A close replication might be precisely what she needed if she were checking whether a result survives.
That failure points at a question the previous chapter left open. A sidecar can bring other material beside a source. But putting two items together in an interface invites an interpretation: this belongs here, and perhaps bears on what you are reading. That implication is stronger than the retrieval score warrants. The chapter asks what relation, if any, has actually been established, what evidence supports it, and whether knowing it helps with the reader’s declared task.
the sidecar can bring in other information
        ↓
but "related" says almost nothing
        ↓
similarity is only one relation
        ↓
different relations support different uses
        ↓
the interface must know which relation it is exposing
What similarity measures
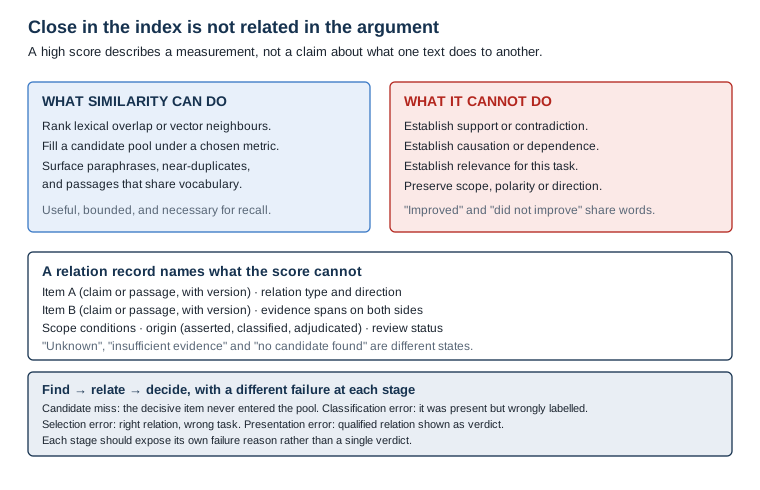
Most systems that find “related” material use a measure of closeness. A lexical retriever scores documents by how many terms they share with the query. An embedding retriever compares vectors, which are lists of numbers that a particular model produces to represent a text. Those vectors depend on the model, its training objective, its preprocessing and the distance metric used to compare them. Both approaches can be useful for generating candidates, the pool of items worth looking at more closely. But their scores describe a relation under those chosen measurements. They do not claim that one text supports, refutes, updates or explains the other. Even a good neighbour ranking does not tell the reader what the neighbour is for.
The difference shows up wherever relationships matter. “The treatment improved outcomes” and “the treatment did not improve outcomes” share almost every word and disagree about the outcome. Depending on the embedding model and corpus, their vectors may also be close. A paraphrase, a qualification and a contradiction can all be plausible high-scoring neighbours. The score is not necessarily calculated incorrectly. It is being asked to answer a question it was not designed to settle. What the reader needs is a claim about the relation, grounded in the relevant passages and their scope. Neither lexical overlap nor vector distance supplies that claim on its own. The parallel investigation in Embeddings From First Principles makes the same distinction: proximity is evidence about a representation, not verification of a semantic relationship.
similarity ≠ relationship
A vocabulary of relations
If resemblance is one relation among many, it helps to name some of the others. The list below is a proposed vocabulary for the sidecar. It is not a mutually exclusive classification of every pair of documents. It mixes relations between claims, relations between works, and relations between implementations and ideas. The two endpoints of each relation must be typed before the labels become usable. A paper might both extend and qualify an earlier result, and for some pairs no useful label may be established at all.
similar to      is analogous to     is an example of
supports        contradicts         qualifies
explains        depends on          causes
updates         supersedes          duplicates
extends         implements          replicates
The terms fall into rough groups, and each group raises a different question. Evidence relations such as supports, contradicts and qualifies bear on a particular claim, but only if the population, assumptions and outcome actually match. Explanatory relations such as explains or causes require especially careful justification, since a proposed mechanism is not the same as demonstrated causation. Succession relations such as updates or supersedes depend on version and authority, not merely on publication date. Practical relations such as implements or extends connect an idea to a system or to a later contribution. Resemblance relations such as similar to, analogous to and duplicates help with orientation and deduplication. A source’s claim that it “replicates” another result is itself a claim about a study. It is not proof that a replication succeeded. These relations can coexist, conflict or remain unknown. Their types describe what is asserted, not how trustworthy the assertion is.

What to do with a candidate depends on both the proposed relation and the reader’s task. A possible contradiction may deserve a check, not an alarming badge. A verified duplicate may be folded away when the reader wants breadth, yet kept when provenance or independent replication matters. A genuine prerequisite may decide reading order. A formally issued correction may change which version to use, while a later paper on a different question need not. An analogy can invite exploration without serving as evidence. Flattening all of this into “related items” loses the distinctions the reader needs. Acting automatically on a relation label would repeat the opposite mistake. A label is not authority to suppress, replace or endorse a source.
This also sharpens what similarity does not tell you:
similarity
   ≠ support
   ≠ contradiction
   ≠ causation
   ≠ dependence
   ≠ relevance
Two passages can sit near each other without one supporting the other. A relevant contradiction may be harder to retrieve because it uses different terminology. Causal relations and dependencies require their own evidence. Even “relevant” is conditional: a relation may be correct but useless for the current task. This list separates three things: a property measured for a pair of items, an asserted semantic relation between identified things, and a decision about what to show this reader now. The last decision should begin with the declared task, not with a persistent guess about the person’s interests.
Making the relation explicit
The architectural point follows directly. If relationships matter, the interface should expose the proposed relation rather than ask readers to infer it from rank or placement. The record can stay small, but it must identify what is related: whole papers, individual claims, a result under a particular condition, or a specific version. A document-level label without a claim-level anchor is often too coarse to check. The record below is therefore a minimum sketch, not a guarantee that its fields are sufficient.
item A
relation type
item B
evidence or source for the relation
standing: how much the system trusts this label
For example: this passage possibly contradicts claim 3 of the paper being read, under the same stated population and endpoint, on the evidence of these two quoted spans. The word “possibly” matters until that scope comparison has been checked. The record should store the source and target identifiers and versions; the direction and type of the proposed relation; the spans supporting each end; the conditions, dates or populations under which it holds; who or what asserted it; and whether it has been reviewed. A confidence score may be stored, but without calibration it is a model output, not a probability that the relation is true. “Not assessed”, “insufficient evidence” and “no matching candidate found” must remain different states. Otherwise, the absence of a record is mistaken for evidence that no relation exists.
This is why the semantic record of Chapter 7 has a place for relationships. Within a source, the record attempts to preserve what that source asserts. Across sources, a new step compares statements made in different places and may propose a relation that neither author asserted. That proposal needs provenance back to both source passages, and a separate origin for the inference itself. Reusing an internal relation record helps with consistency, but it does not promote a cross-document classification into a verified fact. The source remains canonical, the semantic records remain derived, and the cross-source link remains open to challenge.
Scope deserves particular emphasis. “A improves B” in one population and “A does not improve B” in another do not, without further qualification, establish a logical contradiction. They may instead reveal differences in effect across groups, changed conditions or incompatible measures. Before labelling two claims as contradictory, compare the subject, intervention, comparator, outcome, population, time window, assumptions and modality where applicable. Scope that is missing is unknown, not silently shared. A reader may still want to see the difference as a question worth investigating. In that case the interface should say “apparently different findings” rather than manufacture a refutation. Relation type and applicability are separate verdicts.
Where relations come from
Relations can enter the record through several routes, but the route and its authority must stay visible. The next three are different kinds of evidence about a proposed label. They are not three rungs that automatically climb toward truth. A relation may also remain unclassified, or be challenged after an earlier review.
Asserted by a source. A paper says it replicates, refutes or extends another work. Store that as the author’s assertion, with the cited passage and the versions of the works involved. The citation verifies where the assertion appeared, not that its methodological conclusion is sound. A retraction, correction or later replication may change its standing without changing what the original paper said.
Classified by the system. A rule, a supervised classifier or a model compares identified claims and proposes a relation, ideally with evidence spans and scope conditions. The result remains a proposal however polished its explanation sounds. Different classifiers make different kinds of errors. Calling this route always the least reliable would be as unwarranted as treating model confidence as verification. Its measured precision, false-contradiction rate, coverage and calibration determine which tasks it can support.
Adjudicated by a person. A reader or editor confirms, rejects or revises a specific relation against stated evidence and criteria. This grants a reviewed status for that decision, not infallibility. People disagree, overlook conditions and change their minds when new evidence appears. Preserve the reviewer, basis, time and any later corrections. Do not let a human ruling erase the earlier claim or pass itself off as universal ground truth.
Similarity still has a role, and it is an important one. Lexical search, embedding neighbours and hybrid retrieval, which combines the two, are candidate-finding methods. Each covers cases the other may miss. The pool they return places a ceiling on what any later relation classifier can find. A semantic similarity score can sometimes serve as a useful feature in a trained relation predictor, but it does not establish that relation. A safer division of labour is to retrieve plausible candidates, identify claims and their scopes, propose or abstain on a typed relation, and then decide what is worth showing for this task. Each stage should expose its own failure reasons. If the contradictory study was never retrieved, the classifier never had a chance to fail.
find candidates   →   determine the relation   →   decide whether it is worth showing
(similarity can)      (similarity cannot)          (depends on the reader's task)
That ordering lets failures be located rather than explained away. A candidate miss means the important item never entered the pool. A classification error means the item was present but its relation was wrong or was stated with unjustified certainty. A selection error means the relation was described well but was not useful for the stated task, or a useful one was withheld. A presentation error means a qualified relation was shown as a categorical verdict. Evaluate each stage separately, including the legitimate outcomes of uncertainty and silence. Timing and interruption are further decisions for the attention part of the book. A correctly labelled contradiction may still be unwelcome in the middle of a difficult paragraph.
Why the label is hard to get right
None of this makes labelling easy. A negation word does not prove contradiction. The sentence “this does not hold for datasets under a thousand examples” may agree with a broader claim that expressly excludes small datasets. A real disagreement need not use the word “not” at all. Contradiction also differs from a failure to find support. A passage that says nothing about the question is not counterevidence. Relation direction can reverse. An entity name or a time condition can silently change the target. Two studies can measure different endpoints under the same headline. A classifier that treats each passage as a bag of words will miss precisely the scope, polarity, direction and qualifications this chapter asks it to preserve.
The author’s RELATE project explored typed relations as a response to these limits of geometric closeness. Its motivation can inform this chapter without importing its results as a measurement of the sidecar. The separate Embeddings From First Principles work offers a useful warning: near neighbours and high similarity are not reliable tests for negation, contradiction or directional relations. The new claim here is architectural and not yet earned. Making proposed relations explicit might improve discovery for a reader performing a real task. It might also add unreliable labels, distracting ceremony and delay. Until that comparison is run, the label is a hypothesis, and “unknown” is often better than a confident error.
Any claim that typed relations improve discovery must beat serious alternatives. The fair question is not whether labels beat bare keyword overlap. It is whether a typed, source-linked relation layer improves task outcomes beyond competent retrieval and a simpler relevance reranker, at acceptable cost and error rates. A conventional classifier trained for the relation task is also a baseline, not a straw man. The choice of label vocabulary is a further hypothesis. Adding types is not automatically better than using a smaller set that users can interpret reliably.
A proposed discovery test
Freeze a collection of papers, target reading tasks and adjudicated source passages before comparing systems. Include easy near-duplicates, paraphrases, scoped qualifications, findings from different populations, actual claim-level contradictions, corrections, and useful but lexically distant evidence. Have independent reviewers establish task relevance and relation labels from the passages, allowing for disagreement and for “insufficient evidence”. A useful external reference point is SciFact (Wadden et al., 2020), which separates retrieving scientific evidence from classifying support or refutation and selecting rationales. It does not itself measure this sidecar or establish the wider relation vocabulary.
Give each arm the same tasks and attention budget. Compare (1) strong lexical or hybrid retrieval, (2) retrieval plus an ordinary relevance reranker, (3) retrieval plus a simpler support/refute/unknown classifier, and (4) the proposed typed-relation sidecar. Test the relation layer both on a shared frozen candidate pool and end to end with each retriever. This keeps candidate recall from being confused with relation accuracy. Predeclare whether the primary outcome is useful evidence found, correct reader decisions or time to a justified decision. Report false-contradiction alerts, missed decisive sources, unsupported relation labels, abstentions, source-click verification, distraction and cost separately. Use held-out tasks and assessors who do not know which arm they are judging. A positive result on relation classification alone would not establish improved discovery or comprehension.
The null result matters. If simpler reranking offers the same useful discoveries, or if typed labels raise false conflicts and review costs, the chapter’s architecture should contract rather than become another permanent layer. No such reader comparison has been run for this chapter.
Running it
The reference implementation (ernanhughes/project-language) includes npm run example:ch10. It uses a cue-based, model-free classifier on constructed pairs. It records how each label arose and filters labels by a declared task. The separate Pi host adapter is exercised with a scripted stand-in for a model, not a live model evaluation. These are demonstrations of interface and bookkeeping rules. The reported tests do not measure corpus-scale retrieval recall, typed-relation accuracy or improvements to reader decisions.
The example separates candidate finding from relation labelling. Its classifier outputs remain proposals. For support and contradiction, an undeclared or unshared scope is displayed as possible and unconfirmed rather than silently assumed. Corrections create new records instead of rewriting the historical ruling. In the host adapter, a model may request a label through a tool but has no tool to adjudicate it, so a reader can review it instead. The host refuses a later model attempt to replace the reviewed label for that pair. This shows one permission boundary. It does not show that the reviewed label is correct, or that it should remain unchanged after new evidence appears. A person’s confirmation of a label does not independently establish shared assumptions unless that was also checked.
The scope safeguard is especially informative. The cue-based classifier labels a constructed scope-condition example as a contradiction. The display marks the result as uncertain, because the classifier has not learned the right reading. Matching two declared scope strings would not, by itself, prove that the studies share an endpoint or assumptions. The tests establish what the adapter stores, marks and refuses under constructed conditions. They do not establish reliable scientific discovery, human benefit or a trustworthy reviewer oracle. The opening researcher’s problem remains unsolved by this demonstration. The architecture is still a proposal to be compared against simpler systems, not a result imported from RELATE.
Where this leaves us
When the sidecar puts one item beside another, it creates an opportunity for the reader to infer a relationship. A similarity ranking offers one measurable kind of relationship, resemblance under a chosen metric. It does not offer the evidential, explanatory, temporal or practical relations the reader may need. Explicit records can name a proposed type, direction, scope, evidence, origin and review status, including “unknown”. They are useful only if the labelling is reliable enough and the relation changes what a reader can discover or decide. Similarity helps generate candidates. Neither retrieval nor a typed label verifies a claim.
The system is now compressing sources, re-rendering passages, adding external material and proposing links between claims. Each transformation can lose a qualification, reverse a relation or make an unsupported inference look like a discovered fact. What was preserved, what was added and what was promoted in standing must each be tested separately. The next chapter takes up that obligation directly. A fluent or source-linked result is not yet a faithful one, and an apparently consistent relation graph is not yet evidence that the relationships hold.
References
- The author’s RELATE project (https://github.com/ernanhughes/relate), cited as the origin of the typed-relation motivation only. Its results are not treated as evidence of the Language sidecar’s performance.
- Reimers, N. & Gurevych, I. (2019). Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks. Proceedings of EMNLP-IJCNLP 2019, 3982–3992. DOI 10.18653/v1/D19-1410. (A primary reference for embedding-based similarity search, not for the truth of relation labels.)
- Wadden, D., Lin, S., Lo, K., Wang, L.L., van Zuylen, M., Cohan, A. & Hajishirzi, H. (2020). Fact or Fiction: Verifying Scientific Claims. Proceedings of EMNLP 2020, 7534–7550. DOI 10.18653/v1/2020.emnlp-main.609. (SciFact as a precedent for separating evidence retrieval, relation labels and rationales; not a result for this proposed system.)
Research
Not yet researched
This chapter has not yet been researched.