There Is No Universal Best Interface
Learning-style labels do not justify automatic matching. A trustworthy adaptive interface instead separates stated preferences, task demands, prior-knowledge evidence, accessibility constraints and permission to use each input.
Language Outline — Part 3 · Personal mediation
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- How can a system remember accurately across interactions without letting historically true items misgovern the present?
- Source and meaning units
- Memory as historical evidence
- Applicability, standing and authority
- Quorum and replication path
- Supersession and contradiction
- Append-only history and lineage
- Durable history and current context
- Expiry, forgetting and deletion
Candidate source sections: Historical truth, applicability and authority; Revision is not contradiction. These locators do not certify the interpretation.
- Capability introduced
- Separates accurate historical memory from present applicability and authority.
- Proposed reader control
- Inspect old architecture evidence beside a new accepted revision without overwriting history. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Supersession differs from contradiction; retraction is not physical deletion; currentness is checked at use.
- Important limitation
- Avoid claiming: Calling one-process continuity durable storage or deletion propagation.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:personal -- ch23; use -- all for the lifecycle. Scripted inputs and fake services.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented bounded mechanism / scripted Pi demonstration; fake services and in-memory continuity; no reader adapter or measured personalisation benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
The previous chapter ended with a temptation. Iris’s behaviour leaves traces. In the constructed session, she opens tables more often than prose, expands mathematical detail and leaves some diagrams unopened. A system with memory could turn these events into a convenient description: this person is a certain kind of reader. It could then serve that supposed type everywhere, without asking again. But the trace does not record what alternatives were available, why she opened each view, or whether she performed better afterwards. The classification would already be claiming more than the observation showed.
This chapter examines that shortcut. It does not examine individual differences themselves. People differ, tasks differ, and a particular intervention can work better for some people than for others. The claim under examination is narrower: a stable label assigned to a person can reliably determine which representational format improves that person’s performance across tasks. Evidence for that claim needs more than a preference survey or a record of clicks.
A person possesses a reasonably stable representational type, and matching a representation to that type reliably improves how well they do.
Rejecting the shortcut does not mean rejecting stated preferences, task strategies, differences in prior knowledge or accessibility requirements. It means none of them should be quietly converted into a general-purpose category such as “diagram person”. These are different inputs with different evidential and authorisation requirements. The real question is not whether people vary. It is whether the proposed label predicts a benefit that simpler, more local decisions could not provide.
What the evidence does and does not say
Pashler, McDaniel, Rohrer and Bjork (2008) set out an experimental standard for educational learning-style matching. Measure the proposed style before treatment, randomly assign people within each style group to different instructional methods, and test everyone with the same outcome measure. Preference alone is not performance. For the matching hypothesis, the relevant evidence is a crossover: the method that works best for one labelled group must be different from the method that works best for the other. A main effect, in which everyone does better with diagrams, does not count, and neither does an interaction that never changes which method wins. Neither can justify assigning formats by style.
TYPE A:  representation A  >  representation B
TYPE B:  representation B  >  representation A
This is a demanding test. It asks whether the label changes the best instructional choice, not just whether two groups have different average scores. Pashler and colleagues found no adequate evidence base for adopting learning-style assessments in general educational practice. They did not claim to have disproved every possible aptitude-by-treatment interaction, meaning every case in which a learner characteristic changes how well a treatment works.
Clinton-Lisell and Litzinger’s 2024 meta-analysis, which pools results across many studies, reported a positive overall matching effect (a standardised effect size, Hedges’ g = 0.31) across 21 studies. Yet only about 26% of the assessed learning outcomes showed the crossover pattern that would support matching for at least two styles. The authors also identified low study quality and judged the benefits too limited and inconsistent to warrant broad adoption. Hattie and O’Leary (2025) argue that conflating styles with preferences and learning strategies helps explain why positive claims keep appearing.
These are results about educational interventions, not direct experiments on an AI interface. They justify caution about the proposed interface policy. They do not show that the policy has already been tested.
Things that are not the same thing
The word “style” is often made to cover several objects with different implications. An observed strategy is not a stated preference, and neither establishes a stable trait. Separating them gives an adaptive interface something concrete to store and something concrete to refuse:
TYPE CLAIM     "I am a visual learner."
               a proposed stable classification that must earn predictive value

PREFERENCE     "I prefer diagrams for comparisons."
               a stated choice, with a scope and possible expiry

STRATEGY       "For this problem I draw it out."
               an action used in a particular task, not evidence of a trait

AFFORDANCE     "This relation is easier to compare in a table."
               a property of the form, material and task together

PRIOR KNOWLEDGE  "I can already explain quorum intersection."
               a claim about a concept and sense, supported by dated evidence

ACCESSIBILITY  "I need keyboard operation and an accessible text alternative."
               an applicable interface constraint, not a learning-style label
Each of these is a different object, and the separations the chapter needs follow directly:
declared preference  ≠  observed choice  ≠  measured benefit
strategy  ≠  stable trait
prior knowledge  ≠  identity
accessibility requirement  ≠  optional preference
current condition  ≠  permanent category
confidence in an inference  ≠  permission to use it
A task’s structure often gives a better first explanation of which form helps than a global reader label does. Tables align exact comparisons, diagrams can expose topology, and prose can hold qualifications. A stated preference gives another reason to choose among forms that are all acceptable. Prior knowledge can change how much explanatory support someone needs. None of these observations establishes that it explains most variation in performance. Their engineering advantage is that each is a narrower, testable input, unlike a single inferred description of the person.
Expertise changes what helps, and it is scoped
One well-studied source of differences in instructional benefit is prior knowledge. The expertise-reversal effect describes circumstances in which more guidance helps learners with little background knowledge but becomes less useful, or even harmful, once that knowledge is already in place. Tetzlaff, Simonsmeier, Peters and Brod’s 2025 meta-analysis examined 60 experimental studies with 5,924 participants and found effects in both directions. This supports investigating assistance conditioned on relevant knowledge. It does not establish that an AI interface can accurately infer expertise from click history or choose the optimal view.
A newcomer may need terminology expanded, intermediate steps shown and dependencies made explicit. Someone who already knows those steps may prefer direct access to exceptions or primary evidence. The meta-analysis found that guidance mattered more, on average, for novices than withholding it mattered for experts. It also reported variation by educational setting and content domain, with less clear evidence in some groups and subjects. This is a reason to test assistance levels and to preserve an easy route back to explanation. It is not a rule to remove definitions whenever an expertise estimate looks high.
Nor does the evidence license an “expert type”. Iris can be experienced in distributed consensus and unfamiliar with a particular database’s recovery rules on the same afternoon. A knowledge estimate therefore needs a named concept or sense, supporting evidence, a date and conditions of use. As Chapter 17 showed, “known” does not make a source-specific definition safe to omit. Other aptitude-by-treatment interactions may also be real. Seufert, Schütze and Brünken (2009), for example, studied memory strategy skills and working-memory capacity in multimedia learning. The defensible rule is not that individual differences never matter. It is that an alleged difference must predict the outcome of the particular treatment, in the setting where the system proposes to use it.
A requirement is not a preference
Accessibility deserves its own boundary because it determines which representations are usable at all. Suppose an elaborate interactive diagram performs well on average, but Iris needs to complete the same task using a keyboard and a text alternative. A system that offers only mouse gestures or an unlabelled graphic has not found a slightly less convenient option for her. It has failed to provide an accessible way to do the task. That is an interface design obligation, not evidence that she belongs to an auditory, visual or other learning category.
preference           can influence a choice
accessibility need   constrains the choice
Preferences help choose among acceptable forms. Applicable accessibility requirements and source-preservation obligations define what counts as acceptable in the first place. Keyboard operability and appropriate text alternatives should be built into the interface, rather than made contingent on detecting a disability or storing a sensitive classification. WCAG 2.2 provides established criteria for those baseline capabilities. A person’s declared access needs may additionally specify a workable mode of presentation, but the system should not infer a diagnosis in order to provide one. When a requested form cannot yet be made accessible or faithful, the response is an accessible alternative with an explanation. It is not a hidden override justified by an average performance score.
Preference is real without becoming a type
It remains useful to know that Iris prefers diagrams for certain tasks. That can be treated as an explicit rendering instruction. It is not a licence to conclude that diagrams are the way she learns. The system must preserve the difference between a choice she authorised and a hypothesis it derived from her behaviour.
declared preference  →  authorised input within its stated scope
observed choice      →  evidence about one interaction
measured benefit     →  result of a specified task and outcome
none of these        →  permanent person type
“I prefer diagrams” may affect presentation where a diagram can preserve the source and serve the task. It should not become “diagrams are how this person learns”, let alone “never show this person prose”. A declaration has a context and a scope. An observed expansion of a table has only the meaning of that event, until a further inference is proposed and authorised. Performance can vary with the task even while a preference stays the same. The example of diagrams for topology, prose for qualified argument and tables for exact comparison is a design hypothesis consistent with Part I. It is not a measured result for Iris. When an applicable preference is not used, the interface should be able to give the specific reason and leave the reader in control of acceptable alternatives.
Testing adaptation without inventing a type
The rival designs can be compared instead of settled by intuition. A proposed experiment would give participants several tasks whose material calls for different operations: following a state transition, comparing exact figures and interpreting an argument full of qualifications. Outcomes would be fixed before testing. They would include answer accuracy, recovery of qualifications, transfer to a new case, time, subjective preference and the effort required to correct the interface. Accessibility and source fidelity would be eligibility constraints for every condition, not points added to a preference score.
The baselines should be serious. The study would compare a fixed, task-appropriate interface; a version in which the reader chooses and changes the format directly; a system that matches an independently measured stable style label; and an adaptive system that uses declared preferences, source affordances and separately assessed, task-specific knowledge. Formats would be randomised within appropriate task and participant groups, with comparable assessments throughout. The study would test whether the style label predicts a different best treatment, rather than merely higher satisfaction. It would also record both mistaken adaptations and the cost of maintaining or correcting settings. A strong result might show that ordinary reader-controlled switching is as effective as automated adaptation. If so, the simpler interface should win.
This is a proposed study, not an experiment run by this book. The educational learning-style findings supply a warning and a design standard. They do not supply the result of this human–AI interaction comparison.
What replaces the type
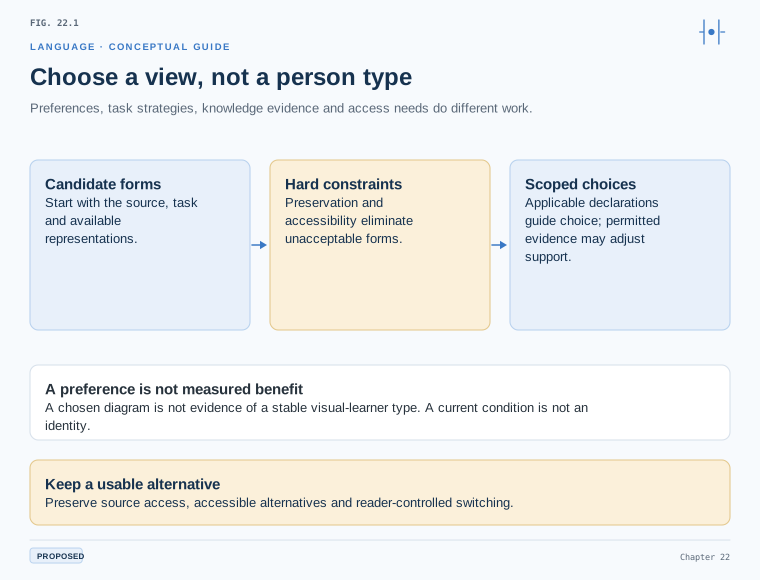
If the type is the wrong unit, adaptation can be organised as a constrained decision rather than a classification of the reader. The source and task determine which representations are candidates. Preservation and accessibility rules eliminate unacceptable ones. Applicable declared instructions then guide the choice. Separately authorised, scoped estimates of prior knowledge or current conditions may inform it where they have evidence behind them. The unchanged, accessible view and reader-controlled switching remain available as alternatives. A person does not need to become an inferred object for each interaction in order to receive a sensible representation.
source and task  →  candidate representations
preservation + accessibility  →  hard constraints
applicable declared policy  →  user-authorised choice
permitted, scoped knowledge evidence  →  optional assistance level
current declared/authorised context  →  optional local adjustment
              ↓
     chosen view + explanation + reader override
              ↘ unchanged accessible source always available
These inputs have different jobs. The task identifies the question. The source identifies what may be asserted, and preservation obligations and accessibility requirements constrain the acceptable outputs. A declared preference controls a choice within its scope. A dated knowledge estimate can suggest how much help to offer, but it cannot erase necessary assumptions. The immediate situation may alter a presentation when use of that context is permitted. Origin, evidential confidence, authority and lifetime are separate fields, and none can silently stand in for another. If an input is unavailable, unverified, inapplicable or unauthorised, the decision should fall back to a source- and task-driven view that Iris can change directly.
The design also changes what the system would need to retain, if Iris permits retention at all. Records should be separate, purpose-limited and inspectable. They should not be components of an unrestricted portrait. Each retained item needs its own origin, scope, evidence where relevant, lifetime and correction path. In particular, an observation may remain an event without becoming a preference. A knowledge estimate should not be displayed as an unquestioned fact about Iris.
declared     concise first view / design reviews / until changed
access       keyboard operation / applicable to every view
observed     expanded derivation / this session / no preference inferred
estimated    quorum intersection / probable / dated evidence required
policy       active-deployment interruptions / explicitly authorised
and not a profile:
IRIS
  visual learner
  expert
  detail-oriented
  cautious
The second form is seductive because its labels are short and seem predictive. But “expert” hides a domain and an observation date, “cautious” invents a broad psychological description, and “visual learner” carries an unsupported treatment rule. Collapsing distinct records into a type makes it difficult to contest the exact claim that changed a view. The alternative is not a larger, more accurate dossier. It is fewer, narrower claims, each used only for a stated purpose and each independently correctable or removable.

Running it
Running it. Run npm run example:personal -- ch22 in the reference implementation (ernanhughes/project-language). The constructed session records an earlier expansion of a derivation as an observation, and permits a scripted model to propose interpretations of that event. The host distinguishes storing the observed action, proposing an interpretation and authorising its use. A later planning step refuses the ungrounded leap from that one expansion to a claim that Iris already knows consensus foundations. The programme uses scripted model behaviour, not a live inference test.
What it shows: in this constructed run, an observed action remains evidence of that action. Proposed inferences carry provenance and scope, and a model’s confidence does not create permission to use one. The host applies record-shape and authority checks before an inference can affect presentation. It refuses person-type fields and inferred inner states, keeps declared accessibility requirements separate, and does not let a task strategy pass as a lasting trait or an expertise estimate pass as an identity. These are inspectable software boundaries. They are not evidence that the categories are complete or that a proposed inference is correct.
What it does not show: whether a real model could identify useful, accurate and sufficiently narrow preferences or knowledge states; whether reader permission and correction would remain usable across sessions; or whether any adaptation improves comprehension, transfer or efficiency against reader-controlled alternatives. A schema that refuses an overbroad inference shows only that this particular rule was enforced for the supplied inputs. It does not prove that every harmful inference has been excluded, or that the classifications that survive make good decisions.
Where this leaves us
Adaptation need not begin with a type of person. It can begin with a source, a task, accessible and faithful candidate views, and the choices Iris has actually made. Prior-knowledge evidence and local context may then help, when they are specific, authorised and independently checkable. The design does not deny individual differences. It denies that a global label is a sufficient reason to choose a representation. Its benefit over simpler, reader-controlled interfaces remains to be demonstrated.
That leaves the next practical problem. Even the narrower design accumulates dated and sometimes conflicting material: a declaration, a one-off strategy, a correction, an estimate supported by an old demonstration. Some items should expire, some should be superseded, and some should never have been kept at all. A statement accurately remembered from March may be the wrong instruction to apply in October. The next chapter asks how an observed or remembered fact acquires, keeps and loses the authority to shape the present.
References
- Pashler, H., McDaniel, M., Rohrer, D. & Bjork, R. (2008). Learning styles: Concepts and evidence. Psychological Science in the Public Interest, 9(3), 105–119.
- Clinton-Lisell, V. & Litzinger, C. (2024). Is it really a neuromyth? A meta-analysis of the learning styles matching hypothesis. Frontiers in Psychology, 15, 1428732. DOI 10.3389/fpsyg.2024.1428732.
- Hattie, J. & O’Leary, T. (2025). Learning styles, preferences, or strategies? An explanation for the resurgence of styles across many meta-analyses. Educational Psychology Review, 37, article 31. DOI 10.1007/s10648-025-10002-w. (Cited only for the point that matching research blurs styles, preferences and strategies.)
- Tetzlaff, L., Simonsmeier, B., Peters, T. & Brod, G. (2025). A cornerstone of adaptivity: A meta-analysis of the expertise reversal effect. Learning and Instruction, 98, 102142. DOI 10.1016/j.learninstruc.2025.102142. (Cited for assistance-by-knowledge results, reported asymmetry, and boundaries across settings.)
- Seufert, T., Schütze, M. & Brünken, R. (2009). Memory characteristics and modality in multimedia learning: An aptitude-treatment-interaction study. Learning and Instruction, 19(1), 28–42. DOI 10.1016/j.learninstruc.2008.01.002. (Cited only as an example that person-by-treatment interactions exist.)
- W3C (2023). Web Content Accessibility Guidelines (WCAG) 2.2. W3C Recommendation. https://www.w3.org/TR/2023/REC-WCAG22-20231005/ (Cited for baseline accessibility requirements, including text alternatives and keyboard operation; not as evidence that personalisation improves performance.)
Research
Not yet researched
This chapter has not yet been researched.