The Personal Experience
Part III begins by separating declared instructions, observed behaviour and inferred beliefs. It asks what a person may explicitly authorise a persistent interface to do, how that policy is scoped and corrected, and which source and accessibility constraints remain in force.
Language Outline — Part 3 · Personal mediation
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- Should adaptation discover a person's stable representational type and match to it, and if not what should organise adaptation instead?
- Source and meaning units
- Learning style, preference and strategy
- Crossover interaction
- Affordance
- Expertise-reversal effect
- Accessibility requirement
- Person-by-treatment interaction
- Meta-analysis
Candidate source sections: A requirement is not a preference; What replaces the type. These locators do not certify the interpretation.
- Capability introduced
- Rejects universal reader types and separates expertise, preference and accessibility.
- Proposed reader control
- Compare a task-based default with a declared format choice; inspect a refused person-type inference. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Do not derive a stable type from clicks; accessibility remains binding.
- Important limitation
- Avoid claiming: Using learning-style matching as an established adaptation method.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:personal -- ch22; use -- all for the lifecycle. Scripted inputs and fake services.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented bounded mechanism / scripted Pi demonstration; fake services and in-memory continuity; no reader adapter or measured personalisation benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
A few weeks into using the Radar, Iris notices that it behaves differently from the first day. Library updates no longer interrupt her. Papers arrive with the conclusion first and the method behind a click. Comparisons come as tables. Possible contradictions of her protocol arrive with the evidence attached, never as bare verdicts. Most of these changes are welcome. But when she asks why a particular item was presented that way, the answer is difficult to reconstruct. One rule came from something she explicitly said. Another may have come from a repeated action the system observed. A third may be a conclusion the system drew from that action. All three can change a view, but they do not have the same authority.
Iris and the sessions in this part are constructed for illustration, as in Part II. Where the book reports a study or a runnable demonstration, it says so. The scene does not establish that a real system has learned Iris’s preferences, or that these changes improved her understanding.
That is the situation Part III begins with. Part II ended with a channel (the part of the system that decides what reaches Iris, at what resolution and when) choosing content under declared interests, narrow knowledge estimates and delivery permissions. Some of the state it relied on already crossed decisions: subscriptions, knowledge evidence, policy revisions and delivery history. The new step is not the invention of memory. It is the decision to let observations about an interaction, and interpretations of those observations, govern a later one. Once the system can do that, the question becomes larger than how to select a useful interface:
What may a channel keep about a person across interactions, who decides, and what must stay explicit?
A remembered preference can be useful and still be wrong, stale or unauthorised. A memory that cannot show where it came from, what it applies to and which permission governs it is a hidden decision-maker. This part asks how a continuing channel can retain information without silently turning evidence of behaviour into authority over the person.
Three kinds of thing that persist
What the system may hold about Iris is not one undifferentiated profile. Three origins matter, because each supports a different claim and a different permitted use:
DECLARED   an instruction or statement Iris explicitly supplied
OBSERVED   an event the system was authorised to record
INFERRED   an interpretation the system proposed from evidence
declared ≠ observed ≠ inferred
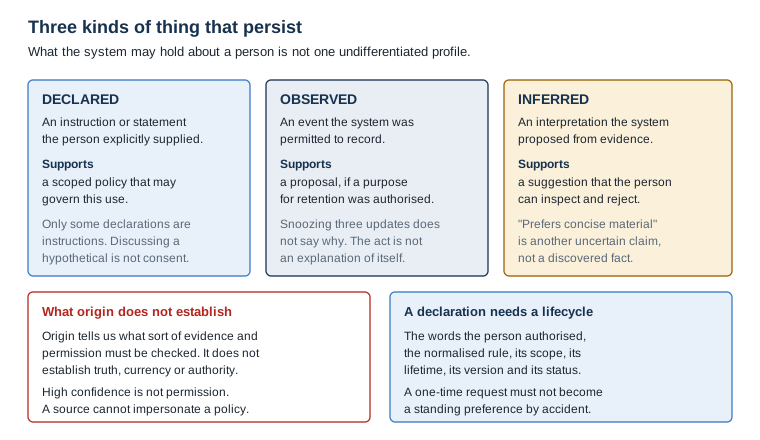

A declaration records something Iris said or deliberately set, but only some declarations are instructions. Quoting somebody else’s preference, discussing a hypothetical policy or asking what a setting means is not permission to save that setting. An observation records an event: Iris snoozed three updates or opened a table twice, if the system was permitted to retain those events. Neither act states why she did it. An inference, such as “Iris prefers concise material”, adds another uncertain claim. Origin alone does not establish truth, currency or authority. It tells us what kind of evidence is involved and which permissions must be checked.
An applicable, authorised declaration may govern how the interface behaves within its stated scope and lifetime. It does not outrank source fidelity (keeping the source’s claims intact), accessibility requirements, permissions or a later explicit correction. Observations and inferences may support suggestions, but they cannot silently replace an instruction or expand the purposes for which data are kept. High confidence is not permission. Nor should a source document or a model-generated reply be able to impersonate Iris and install a policy. This is the first boundary between remembering a conversation and letting something act as an instruction.
The simplest case is also the first: a presentation choice she explicitly makes. This chapter establishes that authorisation path before turning, in later chapters, to what observations and inferences might be permitted to do. It does not claim that those are already safe to use.
The recipient as a declared input
Start from a modest idea. A person may declare how certain kinds of material should be presented, and the system can use that declaration when the task and source allow it. The rendering decision still has to account for what the source says and what the task requires:
SOURCE + CURRENT TASK + APPLICABLE DECLARATIONS
                    ↓
    SOURCE FIDELITY + ACCESSIBILITY + PERMISSION GATES
                    ↓
         CHOICE AMONG ACCEPTABLE VIEWS
                    ↓
          inspectable, source-linked output
No preference has to be inferred in this first design. Iris supplies a setting, and the system records that act as a scoped declaration. The dimensions below are candidate controls, not eight experimentally validated or independent variables. Some overlap: a reader who asks for formal detail may also be asking for evidence-first ordering. A useful interface should expose understandable combinations and conflicts rather than pretending every slider can be applied independently.
depth           concise  ↔  detailed
form            prose / table / diagram / timeline
explanation     examples first  ↔  principles first
order           conclusion first  ↔  derivation first
evidence        synopsis first  ↔  source passages first
interaction     read-only  ↔  exploratory
technicality    intuitive  ↔  formal
navigation      guided  ↔  self-directed
These controls describe choices about presentation for a task or a class of material. They are not claims about the kind of person Iris is. A setting needs a scope, an effective time and a way to be superseded or revoked. “Prefer tables when comparing services” should not become “always show tables”, and a one-time request should not quietly become a standing preference. There is no field for “visual learner” or “technical personality”. Chapter 23 examines why such global types are a weak basis for adaptation. The absence of those fields is a design safeguard, not proof that the remaining settings cover what people need.
Preference, benefit and policy
A declared preference, a measured task outcome and a rule actually applied by the system are three different objects. None follows automatically from either of the others:
DECLARED PREFERENCE    what presentation Iris requests
MEASURED TASK OUTCOME   what a specified evaluation shows helped
APPLIED POLICY         what was actually rendered, and why
“I prefer diagrams” is a legitimate instruction about presentation, not a finding about learning. The system can honour it when a diagram preserves the claims and relationships the task needs. Whether Iris understood more, decided better or finished faster would require an independently measured outcome, not an inference from clicks or satisfaction. If she prefers a diagram but performs worse with it, there are two results to report: her preference was respected where permissible, and the measured outcome did not improve. The second should inform a conversation with her. It should not silently revoke her setting.
The applied policy is therefore not a popularity contest between four signals. The system first determines what the task needs, what the source supports, which accessibility and permission requirements apply, and which policy declarations are current. Only then does it use the applicable preference to choose among admissible representations. It records both the choice and any preference that could not be applied. A system can honour Iris’s authority over her interface while refusing to invent a fact or hide a necessary qualification.
Inside the limits
Four cases make the boundaries concrete. Iris asks for a diagram of an argument full of qualifications. A source-linked diagram with its conditions visible may work, but an attractive diagram that drops them does not. She asks for extreme brevity when a decision turns on two exceptions. The system offers the shortest version that keeps both, or the unchanged source if it cannot. She prefers evidence-first for quick scanning. That order can be honoured, with the cost of extra reading made visible rather than treated as failure. She asks for an intuitive explanation of an exact numerical comparison. A table retaining the precise values can sit beside the explanation. In each case, her instruction shapes an acceptable view. It does not change what the underlying material asserts.
The rule these cases share is one the earlier parts have already prepared:
A personal preference may choose how supported information is shown. It does not authorise the channel to change the source’s claims, discard necessary evidence or defeat an access requirement.
An accessibility requirement is not merely a strong preference. Keyboard operation, text alternatives and other applicable access constraints must shape the set of acceptable views before the system optimises presentation. The Web Content Accessibility Guidelines provide an established reference for such requirements. They do not prove that this proposed interface conforms to them. Iris may explicitly change her own preferences, and that is different from a system quietly treating an expressed preference as a waiver of preservation, access or permission rules. When a preference is not followed, she should be able to inspect the specific constraint and choose another acceptable form.
What if she never touches the settings?
Most people do not configure most things, and many should not have to. Without a declared preference, the system can use a view driven by the source and the task, keep the original accessible and provide ordinary navigation. It should not invent a personal policy from silence. Retaining cross-session observations or inferring lasting preferences requires a separate authorised purpose. Providing a usable default must not depend on that permission. Existing, explicitly authorised settings may still apply, including access requirements, but an unset preference is not evidence of consent to learn one. This is a bounded baseline, not a claim to have found the best interface for everyone.
The generic baseline must also be allowed to win on results. If configuring, interpreting, correcting and maintaining a personalised policy takes more effort than the customised views save, the extra machinery has not earned its place. That cost includes mistakes caused by stale settings, confusing scopes and overrides the reader does not understand, not just the time spent on the preferences screen. The comparison belongs in an experiment, not in the interface’s marketing.
What she sees
Iris should be able to inspect and change not only what is set, but who or what set it, where it applies and how long it lasts. A simple interface might look like this:
My interface — declared settings
  Default: source- and task-driven
  Comparisons: prefer tables (architecture review only)
  Processes: prefer diagrams when faithful (this project)
  Evidence: show source passages by default (all tasks)
  Accessibility: keyboard operable (required)
  [Edit scope]   [Use once]   [Reset declared preferences]
  Why was this view chosen?   View the unchanged source
  Observation-based adaptation: off unless separately enabled
The explanation link matters only if it reports the actual decision. For example: “Your table preference applied because this was an architecture comparison; the diagram request did not apply to this task; the source qualification remained visible.” A polished explanation written after rendering would not be an audit trail. The system needs to retain the policy version, the applicable rule and the rejected alternatives that produced the view. It should also tell Iris what a change will affect next time, without changing other scopes behind her back. Amershi and colleagues’ human–AI interaction guidelines offer relevant design precedents for correction, control and explaining behaviour. Their practitioner evaluation does not establish that this particular policy mechanism improves communication.
A declaration is a record, not a personality trait
An explicit instruction needs a lifecycle before it can safely travel between encounters. Its record must separate the words Iris authorised from the system’s normalised rendering parameter. The normalisation can itself be wrong. For example, “show tables for comparisons” might have meant comparisons of costs, not every architectural trade-off. If the scope is ambiguous, the system should ask once or keep the rule local, rather than making the widest interpretation persistent.
instruction      "Use tables for comparing service costs"
origin           Iris, explicit settings action
scope            service-cost comparisons
lifetime         until changed, or until the stated expiry
recorded_at      time of acceptance
version          policy revision identifier
status           active / superseded / revoked
transformation   normalised rule, linked to original wording
This is a proposed policy-record design, not a claim about the current fixture’s exact schema. At use time, the system should check whether the declaration is authentic, permitted, in scope and still current, and whether it is compatible with requirements that presentation choices cannot override. Where two declarations conflict, a newer, explicit correction for the same scope should normally supersede an older one. A narrow, task-specific instruction should not silently rewrite a broader standing rule. When precedence remains ambiguous, the system should use the generic view and ask. Editing or revoking a setting must affect future decisions, while past decisions remain attributable to the policy version under which they were made. No retrieved page, model proposal or inferred preference may create an apparently user-authored declaration.
A test worth running
The question is not simply whether the system obeys a setting. A proposed comparison would give readers the same source-backed tasks under three conditions: a strong generic interface, a reader-controlled one-time format switch, and the persistent scoped policy described here. The tasks would require exact numerical comparison, qualification-heavy reasoning and process reconstruction. Order would be counterbalanced, and the original source would remain available in every condition.
The study would measure whether the intended policy was applied, whether source obligations survived, whether readers answered and acted correctly, the time and effort involved, preference satisfaction, and the cost of editing, revoking or resolving conflicting settings. It would test a changed task and a stale preference explicitly. Accessibility conformance would be compared separately, as a requirement, not as an average that can be traded against task speed. The experiment could show that a simple on-demand toggle performs as well as a memory of declared preferences. Nothing in the scripted example below has answered that question.
Running it
Running it. The reference implementation (ernanhughes/project-language) offers npm run example:personal -- ch21. Part III uses a cumulative constructed example: selecting a chapter establishes the fixture stages it depends on before showing that chapter’s output. npm run example:personal -- all shows the full invented architecture-review morning through a Pi host, with a scripted stand-in for the model. The run is a demonstration of explicit policy records and routing. It is not evidence that a real model has inferred what Iris wants, or that a real reader benefits.
What it shows: declared policy, ordinary presentation preferences and accessibility requirements remain distinct kinds of record, each with an origin, scope, stated lifetime and an authority reference. The architecture-review policy and the keyboard requirement apply. A terse-triage preference does not apply to that review. Standing declarations pass through the memory provider (core/remembering), not through model-authored declarations. Within the running program, the same in-memory store is reused for a later interaction. A fixed set of invented records and explicit run events drives the example. Activity is not captured automatically, and no personal history is written to the repository or home directory. The model sees a prompt and a narrow proposal tool, not the complete personal history. These are observed properties of the scripted example, not proof that all possible conflicting or hostile inputs have been handled.
What it does not show: that the proposed dimensions fit real people’s tasks, that policy updates remain usable at scale, that preferences improve outcomes, or that any claimed retention lifetime is enforced across a durable service. Reusing a store inside one process does not establish persistence across restarts, deletion from backups or secure isolation between people. The checksum can detect some changes to session records. Without an independently protected integrity mechanism, it is not evidence of resistance to a malicious writer. The new lifecycle and comparison procedures above are proposals, not additional completed features of example:personal.
Where this leaves us
A declared presentation policy gives adaptation an inspectable origin, scope, authority and lifetime. It can be applied without converting a reader into a type or treating clicks as instructions. Preference and measured benefit are different. Source preservation and access requirements still constrain the result, and a generic or one-time choice may be better than a remembered one. The practical claim is deliberately limited: the system can represent and demonstrate the route from explicit declaration to a view, but it has not shown that persistent personal settings outperform simpler controls.
That is the easier case, because Iris can identify what she authorised. Even here, a declaration can be misunderstood, outlive its purpose or collide with another instruction. Observation adds a harder problem. The interface has traces of what Iris did, but those traces do not explain why. Opening a diagram twice is not agreement that diagrams should always appear. Dismissing an alert is not permission to suppress its topic forever. Chapter 23 asks whether the system should model a stable type of person at all. Later chapters then examine how observations, corrections and tentative conclusions may be carried forward.
References
- Amershi, S., Weld, D., Vorvoreanu, M., Fourney, A., et al. (2019). Guidelines for Human-AI Interaction. Proceedings of CHI 2019, Paper 3, pp. 1–13. DOI 10.1145/3290605.3300233. (Cited as design guidance on user control, correction and explanations, not as evidence of the effectiveness of this book’s architecture.)
- World Wide Web Consortium (W3C). (2023). Web Content Accessibility Guidelines (WCAG) 2.2. W3C Recommendation, 5 October 2023. https://www.w3.org/TR/2023/REC-WCAG22-20231005/. (Cited as an established accessibility reference; no conformance of the proposed system is claimed.)
Research
Not yet researched
This chapter has not yet been researched.