The Personal Information Radar
The Part II capstone: a source-bounded, permission-aware attention policy joining discovery, relevance, novelty, preservation, resolution and delivery, with explicit decision records and honest limits on what it can observe or prove.
Language Outline — Part 3 · Personal mediation
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- What may a channel keep about a person across interactions, who decides, and what must stay explicit?
- Source and meaning units
- Persistence
- Declared, observed and inferred
- Presentation policy
- Preference, performance and policy
- Technicality and derivation
- Preservation and accessibility constraints
- Generic default
Candidate source sections: Three kinds of thing that persist; Inside the limits. These locators do not certify the interpretation.
- Capability introduced
- Introduces declared communication policy while distinguishing observations and inferences.
- Proposed reader control
- Choose a session presentation preference and inspect origin/scope without creating a profile. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Preservation and accessibility constrain preference; ordinary default remains available.
- Important limitation
- Avoid claiming: Preference compliance being presented as improved performance.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:personal -- ch21; use -- all for the lifecycle. Scripted inputs and fake services.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented bounded mechanism / scripted Pi demonstration; fake services and in-memory continuity; no reader adapter or measured personalisation benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
Iris’s afternoon begins at 14:40. She is presenting in a design review that runs until 15:30, and a deployment is scheduled for 18:00. Four items have arrived in the sources she has explicitly authorised the system to watch. Her declared focus rule permits interruption for verified blockers affecting an active deployment. Unconfirmed research relationships must remain available for her to inspect, not be pushed to her. The Radar (the name this part gives to the attention side of the same Language layer built in Part I) has to decide what to do with each item without assuming that noticing it would help.
A  a new paper that possibly weakens the bounded-delay assumption
B  a major update to a library she uses often
C  an interesting new survey of consensus protocols, mostly material she knows
D  an incident report affecting tonight's deployment
Part I ended with the Semantic Browser, a source-linked way to choose and check representations for a task. This chapter assembles the corresponding attention architecture across changing sources. Its question is: what should reach a person, in what form and at what moment, when more candidates arrive than she can inspect? The radar metaphor is useful for three reasons. Its coverage is bounded, its detections are uncertain, and most signals do not warrant an alarm. The metaphor becomes dangerous if the system treats the person as the object of surveillance. The proposed Radar watches authorised information sources and declared interests, not Iris herself. Any context used for delivery needs a separate permission and purpose.
What the Radar is made of
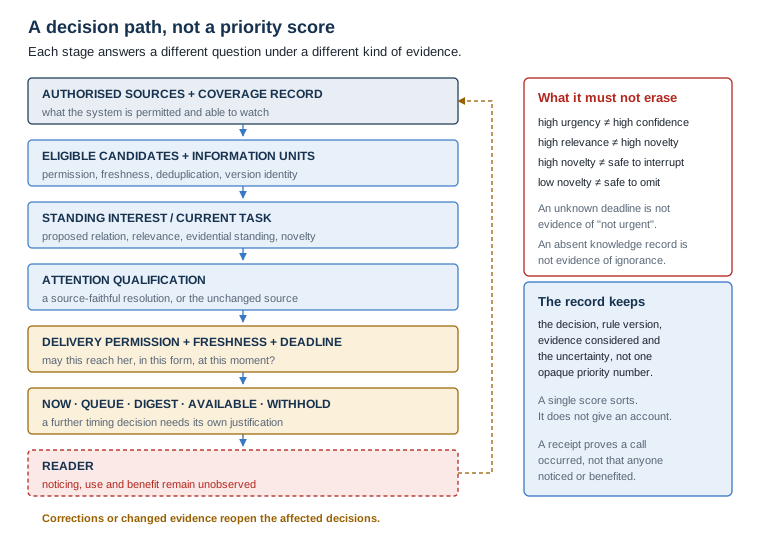
The stages are the ones the part has built, but their order is not a one-way ranking. Permission and source coverage constrain what enters. A source-linked unit may have to bring its qualifications with it. Delivery decisions must be reconsidered when a deadline, source or policy changes. The diagram is a proposed decision path, not a claim that the current application implements every stage:
AUTHORISED SOURCES + COVERAGE RECORD
   ↓  discover, deduplicate, identify versions
ELIGIBLE CANDIDATES + INFORMATION UNITS
   ↓  preserve source claims and dependent qualifications
STANDING INTEREST / CURRENT TASK + PROPOSED RELATIONS
   ↓  relevance, evidential standing, prior-knowledge evidence
ATTENTION QUALIFICATION
   ↓  select a source-faithful resolution (or keep source unchanged)
DELIVERY PERMISSION + FRESHNESS + DEADLINE / CONTEXT
   ↓  NOW · QUEUE · DIGEST · AVAILABLE · WITHHOLD
READER (noticing, use and benefit remain unobserved)
   ↺  corrections or changed evidence reopen the affected decisions
This is not a ladder that increases a candidate’s universal importance score. Each stage makes a different claim, supported by a different kind of evidence. A stage may decide that an item falls outside a subscription, that its relation is unconfirmed, that its qualification cannot be omitted, or that Iris has not authorised an interruption. Some gates are hard constraints, not preferences to average away. An implementation may use numerical estimates within a gate, and it will need an explicit tie-break when several authorised alerts compete. But no final scalar should erase which decision was made, under which rule and with which uncertainty. The proposed record therefore has decision dimensions plus an audit envelope, not merely a priority number:

candidate_id + source_id + source_version
coverage       which permitted source and scan exposed it
eligibility    permission, freshness, deduplication and scope
relation       proposed link to a declared interest or task
relevance      why it bears on the current purpose
necessity      claims and qualifications that must travel together
novelty        evidence about this reader's knowledge, or unknown
standing       source quality and relation status kept separately
urgency        deadline and consequence of delay, or unknown
interruption   authorised policy and estimated cost now
resolution     source-linked view or unchanged source
mode           NOW · QUEUE · DIGEST · AVAILABLE · WITHHOLD
reasons        evidence and rule version for each decision
history        changed facts, corrections, refusals and delivery receipts
A single score makes sorting convenient, but it does not account for a decision. The record must be able to explain why a highly relevant but unconfirmed paper was not pushed, why a seemingly familiar definition remained visible, and why a confirmed deployment blocker could interrupt. It must also say when a required field is unknown. An unspecified calendar is not evidence that Iris is free. An absent knowledge record is not evidence that she knows nothing. The distinctions throughout Part II survive only if the final router keeps them visible:
high urgency    ≠  high confidence
high relevance  ≠  high novelty
high novelty    ≠  safe to interrupt
low novelty     ≠  safe to omit
An urgent item with weak evidence, a relevant item Iris may already know, and a familiar prerequisite she still needs are not interchangeable. The record also makes revision possible. Correcting a relation should not silently rewrite novelty evidence or grant notification permission. A correction changes the affected decision, with a versioned reason, while earlier decisions remain inspectable.
Four candidates, four records
Consider a constructed policy at 14:40. The four candidates, their apparent relevance and their delivery outcomes are all invented to expose the distinctions. There is no observed Iris and no real notification. In this illustration, the subscription, source access and interruption rule are declared in advance. The records below abbreviate the fuller audit envelope. Any unspecified value is unknown, not silently favourable.
A  new paper concerning a bounded-delay assumption
   source standing: peer-reviewed in this constructed case
   relation: possible weakening; applicability to Iris's protocol unresolved
   task relevance: potentially high       novelty: provisionally high
   resolution: source-linked brief, labelled candidate
   delivery: AVAILABLE (reader-initiated; no push of unresolved relation)
   why: evidence about another mechanism does not prove a contradiction
B  major library update
   declared interest: library releases relevant to her work
   task relevance: low for the deployment, absent evidence of an impact
   urgency: no current deadline established
   delivery: DIGEST, subject to source freshness and active permissions
C  new survey, mostly familiar by the example's assumed knowledge evidence
   novelty: one potentially new classification of delay models
   preservation: retain definitions needed to interpret that classification
   resolution: GLANCE, with direct access to the underlying section
   delivery: AVAILABLE; do not suppress solely for low estimated novelty
D  verified blocker affecting tonight's deployment (constructed)
   relation: directly linked to the current deployment; evidence inspectable
   task relevance: high              urgency: high before 18:00
   permission: Iris opted in to immediate alerts for verified blockers
   resolution: short notice plus unchanged incident source
   delivery: NOW, after freshness and authorisation checks
Candidate C shows why estimated familiarity is not permission to remove source-specific meaning. The new classification remains reachable, with its definitions. B qualifies under a standing interest without becoming urgent for the current deployment. A is different again. Even an interesting, peer-reviewed paper may have an unresolved relation to Iris’s own safety argument. The subscription can help her discover it, but the strict delivery policy of Chapter 20 leaves it AVAILABLE until she requests inspection. D can interrupt only because both the operational evidence and her explicit exception rule warrant it. None of these example labels comes from measured relevance or a real model’s classification.
When two items compete
At 14:40 both A and D could matter, but only D qualifies for an interruption under the declared policy. Assigning them imaginary priorities such as 0.91 and 0.84 would obscure that difference. The Radar must first respect the permission gate and the status of each relation. It then explains how the remaining delivery choice was made. If two permitted blockers arrive together, a documented deadline and a deterministic tie-break rule can order them. This does not claim that one opaque score has settled every trade-off.
D interrupts because:
- a verified blocker bears directly on the active deployment
- Iris authorised immediate notices for this class of event
- waiting until her next break may remove the chance to respond
- source, deadline and permission were checked for this decision

A remains AVAILABLE because:
- its relation to Iris's protocol is unconfirmed
- her rule does not permit pushing unresolved research relationships
- she may request the brief and inspect both sources at any time
In the constructed sequence, the verified blocker is presented at 14:41 with its reason and source link. Iris can inspect or dismiss it. The example does not assume that she did either, or that the alert improved the deployment. The paper remains in her available list. At 15:35 she could choose to open its source-linked brief after the review. That is reader-initiated access, not a notification the scripted system claims to schedule. Before any queued or scheduled item is actually released, the source version, relation, deadline, permission and current policy would need to be checked again. B awaits an authorised digest, and C remains accessible. The trace explains dispositions, not observed human behaviour.
What the Radar has not seen
An integrated selector creates a particular kind of hidden failure. When Iris sees nothing, she cannot tell whether nothing qualified, whether the system judged something irrelevant, or whether the source was never within reach. A coverage report must therefore separate observed and processed, observed but rejected, failed to retrieve and outside the configured scope. It cannot list the identity of a paper it never observed, and it must not reveal the existence of material she lacks permission even to know about.
not surfaced may mean:
- observed, but failed a declared eligibility or relevance gate
- observed, but judged familiar (with potentially mistaken evidence)
- accepted, then held in QUEUE / DIGEST / AVAILABLE
- withheld under a stated authorised rule
- a configured source or scan failed
- the source was outside the configured coverage
- the system never encountered it (unknown, not a logged rejection)
The last three are limits of observation, not findings about relevance. Even a flawless relation classifier cannot discover a paper that never entered its candidate set. A successful query cannot establish that no relevant paper exists elsewhere. Conversely, an item rejected by a gate was observed, and it should be auditable within the reader’s permissions. The system can report source lists, query windows, last successful scans, failures, missing intervals and counts by stage. It cannot describe unseen items individually. Hence:
not selected  ≠  does not exist
radar coverage  ≠  the world
This is the danger of a polished Radar: silence starts to feel like evidence. Iris should be able to inspect what the system was authorised to watch, when it last checked, how many candidates it examined, which permitted candidates were rejected or deferred, and which scans failed. A coverage statement should distinguish not found in the observed set from not present in the world. Audit logs themselves need access controls and bounded retention, because titles, subscriptions and rejection reasons can reveal information. The system should make uncertainty and gaps visible without offering an impossible guarantee of complete discovery.
A correction that changes policy, not the person
At 15:40, while reviewing her declared notification settings, Iris adds a rule: “Don’t interrupt me for library releases unless they affect an active deployment.” This is a preference she is free to state, even though candidate B was routed to a digest rather than an interruption in the earlier example. What happens to the rule is more interesting than why she chose it.
The proposed system stores this as a scoped, versioned rule on library-release delivery. It can require evidence that a release affects an active deployment before using the exception. It does not infer that Iris dislikes software releases, and it does not turn the observation into an account of her personality. Nor may it silently override a stricter do-not-disturb rule with this more general preference. The applicable permissions and their order of precedence must remain explicit.
correction  →  policy refinement
correction  →  not a conclusion about the person
The changed rule is visible and reversible. Its receipt identifies what Iris said, when it applies, which prior rule it replaces, and whether any queued decisions need to be revisited. Corrections to relevance, evidence standing, novelty and interruption belong to separate gates. This is also an admission-control boundary familiar from context and memory systems. Observed behaviour is evidence for a possible proposal, not permission to write a new standing instruction. A single thumbs-down could not say which judgement was wrong, and even an explicit correction should not expand beyond its stated scope.
Adaptation without an unrestricted model
A broader principle has emerged through Part II, and the Radar makes its architectural form visible. Instead of letting all observed activity accumulate into a general personal profile, the design uses several narrow, purpose-bound objects:
knowledge state  ≠  dossier
explicit standing interest  ≠  inferred identity
observable context  ≠  inferred inner state
In the imagined system, the knowledge model holds evidence about particular concepts and senses, not general claims about Iris’s intelligence. Standing subscriptions record what she chose to watch. An interruption gate may use a calendar signal only if she authorised that use, and it does not need her meeting’s contents in a lasting profile. The Radar does not need to infer her mood, politics or character to make these proposed decisions. The design hypothesis is that useful attention adaptation can be achieved with bounded, inspectable state rather than an unrestricted personal model. The constructed afternoon illustrates the hypothesis. It does not demonstrate performance, privacy compliance or the absence of unintended inference.
What the selected alert says
A candidate can be correctly selected and still be badly delivered. Suppose, in a constructed example, a paper reports a performance improvement only under one evaluation condition. The Radar finds a genuine relationship to Iris’s task, but its alert says simply “the method improves performance”. Source interpretation and relevance selection may have succeeded, while the delivered claim loses its scope. Chapter 8’s A/B comparison could propose that difference for review before the alert is queued or shown.
That comparison supplies evidence for a delivery decision. It is not notification permission or proof of benefit. The alert should retain the qualification, or offer the source, when a short message cannot carry it. A later answer can be examined against Iris’s actual question. A click alone establishes neither comprehension nor value. The existing deterministic feed screen has not demonstrated this transcript or paper-analysis path.
What the architecture has not shown
This is a proposed architecture, not evidence that its integrated judgements are correct. Its components may introduce correlated errors. One misclassified relation can determine selection, resolution and delivery at once, producing a consistent but misleading experience. An unknown deadline can quietly become “not urgent”. An out-of-date knowledge estimate can hide a needed definition. A correct source link can point to an incorrectly interpreted claim. A hostile source may even contain text instructing the model to change its watch or delivery rules. Source content is data, not authorisation, and it must not cross that boundary. More candidates also create contention and duplication that the four-record illustration does not test. The decisive comparison is against competent, simpler systems, not only against a firehose of unsorted alerts. That requires a measured programme.
Testing the Radar as a whole
A first, proposed offline study would freeze a permissioned corpus of source snapshots and timed arrivals. The corpus would include duplicate reports, conflicting accounts, expiring deadlines, ambiguous relations, irrelevant near-matches, instruction-bearing hostile source text, and critical items outside some monitored sources. Independent reviewers would label the questions each item actually bears on, its evidential standing, its required qualifications, and the consequences of missing or delaying it. The Radar would not see these labels. The study would compare a chronological feed, a strong keyword-and-source filter, reader-configured alerts with ordinary do-not-disturb and digests, and the proposed stage-based Radar. Ablations would remove typed relations, knowledge estimates or preservation gates one at a time.
The study would report consequential misses, false urgent alerts, precision at a fixed attention budget, source and qualification fidelity, latency, duplicate burden, policy violations, retraction handling and coverage gaps separately. A second, consented task study would examine whether people actually noticed, correctly interpreted and used the material, whether interruptions harmed their work, and whether stage-specific corrections helped. Presentation receipts alone are not observations of attention. Finally, a limited shadow-mode study on live streams could compare proposed routing with what existing tools delivered, without withholding deployment-critical messages. These are designs to run, not studies the book has completed. Closed-world labels cannot certify discovery in an open world, so a live report must retain an explicit coverage boundary.
The outer edge in use
There is a smaller application, with an observed run, beside this design. Too Much YouTube (tmy) screens my YouTube subscriptions against a purpose file. In its first live run on 15 October 2026, it resolved 195 subscriptions, read 195 public feeds and screened 169 videos from the preceding week. A broad deterministic rule surfaced 49 videos; a tightened rule surfaced 19. These are counts from the run recorded for this book, not independent measurements of relevance. We do not yet know whether the 19 contained the most useful videos, or which consequential items either rule skipped. The numbers establish that the rule change altered selection. They do not establish that the narrower rule improved it.
The input is deliberately limited to each video’s title and the first 500 characters of its description. The file against which these are matched contains a declared purpose, terms, exclusions and a field labelled as known material. An assistant initially drafted that file from my work. Publishing it in a file makes the draft reviewable, but it does not make the draft automatically authorised or correct. The deterministic rules can compare words and exclusions. They cannot determine whether a talk’s decisive claim is at minute 53, what its speaker actually demonstrated, or whether a familiar phrase is understood. This is metadata screening, not the transcript decomposition or knowledge estimation proposed in Chapters 14 and 16.
Each screened video receives a disposition (LOOK, AVAILABLE or WITHHELD) and a recorded reason. The digest retains the other categories for review within the configured access scope. The run also reports feeds and entries it could not retrieve, the publication window, and the possibility that a public feed omitted older videos within that window. A record of 195 successful feed reads therefore does not imply complete coverage of those channels, let alone of YouTube as a whole. Showing the withheld list is useful for auditing the items actually observed. It cannot expose videos outside the scans, and it cannot justify revealing unauthorised source metadata.
This is the Radar’s outer edge in practice: a finite configured source set, a visible screening rule, recorded dispositions and a declared coverage limit. It is also a useful deterministic baseline for the proposed experiment, because it can be replayed on a frozen feed snapshot before more elaborate relation models are introduced. Its command and code are described in tmy/README.md. The invocation begins npm run tmy -- scan, with subscriptions and purpose supplied explicitly. A reproducible comparison would retain the exact input snapshot and both rule versions, then independently examine some of the videos that were kept and those that were withheld, rather than reporting a shorter foreground list as success.
It does not implement the full Radar. It does not read transcripts, identify timestamped units, detect relations across papers, check semantic subscriptions, choose preservation-checked resolution levels, or schedule permission-bound interruptions. It uses a declared known-material list rather than an evidence-backed knowledge model, and it makes no real-model calls. Neither the reduction from 49 to 19 nor the existence of a reason for each item establishes reader benefit, correct selection or a safe omission policy. An immediate next test is to adjudicate a frozen subset of the 169 observed videos, including the omissions, and compare both rules at the same attention budget. Evidence of missed relevant videos matters more than the aesthetic quality of the digest.
There are three distinct artefacts here: the conceptual Radar decision dimensions, the scripted Pi example’s typed stage trail, and the live tmy screening ledger. They share design principles but not an implemented end-to-end schema, and results from one do not validate the others. Keeping those boundaries visible is an important part of this capstone. The live edge establishes that a bounded real source stream can be screened and audited at the metadata level. The integrated selection and delivery claims remain hypotheses.
Running it
Running it. npm run example:radar exercises a separate, invented afternoon on a Pi host, with a scripted stand-in for the model. It does not call a real model. Its five constructed candidates are a preprint, a different mechanism, a qualifying contradiction, a brief that drops a qualifier, and a keyword-stuffed decoy. The run prints each stage’s typed decision and reason, the meeting-end delivery revisions, and a source-coverage boundary. It is a software trace designed to test refusals and bookkeeping. It is not a replay of Iris’s four candidates or of the YouTube scan.
What it shows: the scripted decisions can be routed and refused without an opaque total-priority score. A stage can report why it refused an item, and a later event can produce a revision rather than rewriting the past. Separate receipts for admitting material into a model’s context and for presenting something through an interface demonstrate a distinction from Context that matters here: information reaching the model is not information reaching the human. A presentation receipt proves that a presentation call occurred. It does not prove that Iris noticed, understood, used or benefited from anything. The strict unresolved-relation policy described in Chapter 20 still applies to this scripted example.
What it does not show: reliable candidate discovery, real-model relationship judgements, actual scheduled delivery, a validated unified decision schema, human reconstruction, or superiority over a chronological feed. No closed-world end-to-end comparison was run. The stage trail’s typed reasons and revisions overlap with, but are not identical to, the conceptual record. Some conceptual obligations are not executable gates in this demonstration. The example says only what its configured inputs and supplied scripted cases permit it to say. It should not be conflated with the live tmy run, which has real input but much less machinery.
Where this leaves us
Part II has brought together a set of independently risky decisions that sit between abundant information and a finite reader. What is the information unit? Which claims and conditions must stay together? What matters to the current task, what may be new to this person, and what relationship has she asked to watch? How much should reach her, and does she permit it to arrive now? The proposed Radar keeps these decisions separate, source-linked and revisable. The channel now has a role not only in how something is said, but in whether, when and on what authority it is allowed to enter the reader’s view. Whether that architecture improves decisions beyond competent simpler tools is still an experimental question.
In the constructed afternoon, Iris has authorised sources, subscriptions and an interruption rule, and the system has proposed dispositions without taking any operational action for her. A live system could accumulate a history of her corrections, requests and responses. That history is not automatically permission to build a personal model. Even the difference between a declared rule, a recorded click and an inferred preference would need to remain visible. Choosing what reaches her creates the possibility of memory, but it does not confer the right to use every observation as memory.
Part III begins at that boundary: what can persist from one encounter to the next, under whose authority, and how can Iris see, contest or remove an inference? The Radar has not solved personalisation. It has made clear why a system that remembers its encounters needs a stricter account of declaration, observation and inference than an attention filter alone can provide.
---

*Editor's note (not part of the chapter):* Two points for the author to check. The stage diagram and the candidate C record use "GLANCE", which is not one of the five delivery modes listed in the diagram (NOW · QUEUE · DIGEST · AVAILABLE · WITHHOLD); the term is kept as written, but it should be reconciled. The expert analyses supplied with the request were incomplete, so the revisions above follow the preservation constraints and the editorial intention (clarifying terms and sentence structure, keeping all headings, figure shortcodes, links, code blocks and claims unchanged) rather than their specific recommendations.
Research
Not yet researched
This chapter has not yet been researched.