The Language Between Languages
Between ordinary human language and executable machine state there is a ladder of representations. What does each make easier, what does each give up, and what happens to a person's intent as a statement becomes easier for a machine to check?
Language Outline — Part 1 · Representation
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- What does the Part I architecture look like when source, record, obligations, task, representation choice, sidecar and check operate as one system on a single report?
- Source and meaning units
- Semantic browser
- Incident report, telemetry and runbook
- Replication lag and failover
- Hypothesis, evidence and qualifier
- Gate, repair and fallback
- Per-view and per-row checking
- Composition and end-to-end benefit
Candidate source sections: Checking before showing; Running it. These locators do not certify the interpretation.
- Capability introduced
- Composes Part I while allowing lookup, refusal and unchanged-source routes.
- Proposed reader control
- From the same source choose lookup, comparison or original; inspect each view's separate check. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- No pooled score may hide a missing qualification in one view; procedure text is not execution authority.
- Important limitation
- Avoid claiming: Calling the single-passage reader the completed Semantic Browser.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:ch12; supplied/scripted inputs, not a browser feature.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented bounded mechanism / scripted demonstration (reported reference checks, not rerun here). Semantic accuracy and reader benefit unverified.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
A product owner asks for a job queue with two properties: “A job must never be executed twice” and “A job that fails for a transient reason should be retried up to three times.” These sound clear until a worker times out after charging a card. The caller cannot tell whether the charge happened, so it retries.
What does “executed” mean here? It could mean that the worker ran, that the queue recorded a completion, or that money actually moved. Under the first reading, another attempt breaks the prohibition. Under the second, the queue may record one completion even after two charges. Under the third, a retry is allowed only if it cannot commit a second charge. The ambiguity is not a linguistic curiosity. Each reading permits different observable behaviour. This is a constructed example, not an incident report.
Someone building the queue chooses the second reading: at most one recorded completion for each job. They implement a checker, run every test, and report that the invariant holds. But consider a trace. The first attempt charges the card, loses its acknowledgement, and is marked failed. The next attempt charges the card again and reports success. The system records one completed job and two external effects.
The checker is not necessarily defective. It checked the property it was given. The missing step was asking the owner whether “never executed twice” meant never charge twice. A specification can be internally consistent and still represent the wrong obligation. Real systems often use idempotency keys and durable effect records to address that boundary. Declaring a unique completion record does not implement those safeguards.
This chapter is about that mismatch between what was requested, what was formalised, what was checked, and what actually happened. Chapter 11 required preservation obligations to be declared before a transformation. Here we follow one obligation across forms: from a person’s request into structured requirements, machine-checkable properties, and an observable operation. At each boundary we ask who made an interpretive choice, and what evidence could expose a wrong one.
Between ordinary human language and executable machine state, what kinds of representation are available, and what does each make easier or harder?
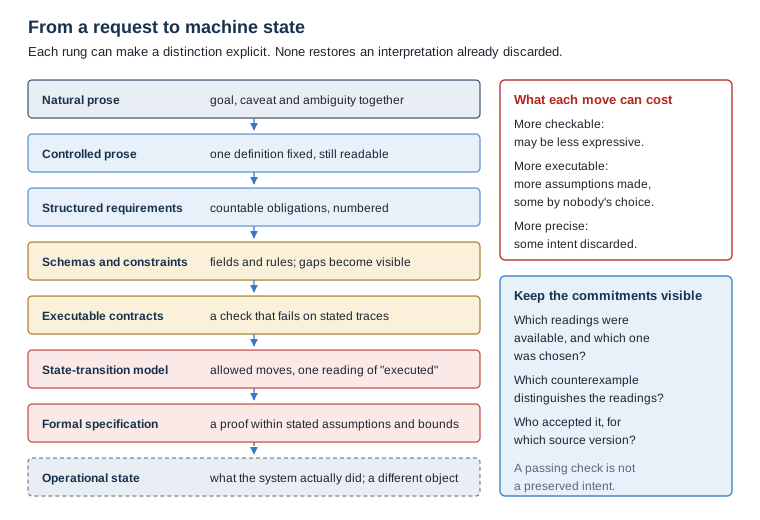
A ladder of ways to say the same thing
Take the queue requirement and make it successively more explicit. The sketch below deliberately follows the builder’s recorded-completion interpretation, not the owner’s later concern about duplicate charges. That is the trap: a series of mutually consistent representations can all inherit the same initial mistake. “Up to three retries” is also ambiguous unless we say whether the initial attempt counts. Below, retries exclude that first attempt.
natural prose
    "A job should never run twice, but transient failures should be retried."

controlled prose
    "Each job has at most one completed execution.
     A failed attempt marked transient may be retried up to 3 times."

structured requirements
        R1  recorded completions per job  <=  1
    R2  additional retries per job, cause = transient  <=  3

schemas and constraints
        fields: job_id, attempt, status, cause
    constraint: count(status = completed, by job_id) <= 1
    missing: external-effect identity and deduplication rule

executable contracts
    a test or runtime assertion that fails when the constraint breaks

state-transition representations
    states and allowed moves: pending → running → completed,
    or running → failed(transient) → pending (at most 3 times)

formal specification or proof
    a statement of the invariant in a logic, with assumptions stated,
    and a demonstration that the model satisfies it

machine-native operational state
    the queue's actual configuration and runtime records
Notice what happens as you move between forms. The controlled sentence fixes one definition. The constraint makes that definition countable. The transition model names possible movements through state. Those changes can expose ambiguity and permit new checks. They cannot recover an interpretation discarded at the first step.
The movement is not strictly one-way. A formal model can express behaviours that the prose never mentioned, while an operational log can reveal a failure that no abstract schema included. Readability does not always decline either. A well-chosen diagram or trace can make a constraint easier for its owner to inspect than an obscure paragraph. The useful question is which distinctions become explicit, which are lost, and which become newly testable in this move.
It helps to read the ladder as a set of orientation points, not a ranking. Its rungs are not guaranteed to grow in precision, expressive power, or fidelity. Some rungs are alternative views rather than refinements of one another. A state-transition model describes allowed behaviour. A test observes selected executions. A proof establishes a property under stated premises. A runtime trace records what occurred. None of these subsumes the others automatically. A useful traversal may move up, down, or sideways, and it should preserve the link back to the owner’s words.

Six things to ask of any rung
Six questions help compare representations. They are dimensions to investigate, not scores that the notation assigns to itself. The last three in particular require a stated task, a human or operational oracle (a trusted judge of what the right outcome is), and an account of what was actually observed.
| Question | What it asks |
|---|---|
| Expressiveness | Which distinctions, exceptions, and alternatives can this form state? |
| Ambiguity | Which interpretations remain open, and which were settled by whom? |
| Checkability | Which explicit properties can a checker test or prove, over which assumptions and states? |
| Intent preservation | Does the chosen reading retain what the requester would accept in the relevant cases? |
| Executability | Can a machine use the form to constrain or drive an operation, and with what authority? |
| Reconstructability | Can the affected person recover and challenge the operative meaning from this form? |
Natural prose often makes goals, caveats, and negotiations accessible. It can also conceal contradictions. A formal model may make particular claims decidable or provable while omitting the boundary the owner cares about. A readable diagram may outperform both for a particular review question. The six dimensions should therefore be evaluated on specified cases, rather than assigned universal high or low rankings for whole notations.
Intent preservation is different from syntax validity. It concerns the relationship between a representation and the requester’s actual purpose under the conditions of use. Asking the requester is often necessary, but a nod at a paraphrase is not sufficient evidence in a consequential case. Present concrete counterexamples, such as “a card was charged, but the completion was not recorded,” and ask whether the proposed requirement permits them. Keep the accepted choice, the source span, the examples considered, and the identity of the authority who accepted it. Even that establishes a bounded agreement, not access to someone’s complete inner intent.
More formal is not better
It is tempting to read the ladder as progress, and to conclude that the further down you go, the better. The trade-offs say otherwise.
more checkable
    may mean less expressive

more executable
    may mean more assumptions made explicit,
    some of which nobody chose

more precise
    may mean some human intent has been discarded
Precision can expose a question that prose left open. It can also conceal who answered it. In the queue, someone equated “executed” with “recorded as completed,” and every later constraint inherited that choice. The owner meant “one charge per intended payment,” an obligation about externally observed effects, not job status.
The safer move is to preserve the alternative readings until a decision is made. Record the chosen interpretation and its scope, and include a counterexample that would distinguish it from its rivals. Precision is only a gain when the interpretive commitment remains inspectable.
So the central claim of this chapter can be stated plainly:
A representation can become easier for a machine to verify while becoming worse at preserving what a human meant.
This is not an argument against formal representations. It is an argument against treating verification as if it were fidelity. Three things that are easy to run together need to stay apart:
intent preservation ≠ checkability ≠ implementation conformance
An implementation can conform to a specification while the specification omits the customer’s actual concern. The available assurances also differ in kind. A passing test establishes behaviour only on the executions tested. Finite-state model checking examines behaviours within its encoded model and bounds. A proof establishes a proposition from stated axioms and assumptions. Independent observations establish something about the deployed system. None of these alone proves that the original requirement was elicited correctly, that the model includes every relevant external effect, or that the mapping from code to model is sound. A perfectly valid proof of “at most one recorded completion” is compatible with a double charge if charging was excluded from the model. Formal methods make the claim checkable. They do not choose the claim on the owner’s behalf.
What a mediator could do here
If the ladder is a space of trade-offs, where does intelligence in the channel fit? Not in replacing ordinary language with formal notation. The more interesting possibility is a mediator that helps a person move between rungs without hiding the decisions made along the way.
Picture a mediator that helps rather than decides. It highlights the word “executed” in the owner’s original request and proposes three readings, each attached to a small trace that distinguishes it from the others. It asks what should happen when a payment succeeds but its acknowledgement is lost. The owner may select a reading, revise the request, or leave the issue unresolved. Only the settled obligations are compiled into checks. Unsettled ones remain visibly blocked, and no generated default is silently promoted.
The mediator then renders the chosen properties back into plain language. That rendering carries a trace to the original words, the examples used to settle them, and the checks that can actually run. A human confirmation is tied to that exact version, and it becomes stale when the meaning changes.
This is the preservation contract from Chapter 11, applied to specification work. Across each step, mark what survived, what was narrowed by agreement, what was added as a new assumption, and what remains unresolved. A renamed field, a missing exception, or a newly introduced definition can be legitimate if its origin and authorisation are visible. A check should distinguish “the new form is internally valid” from “the owner accepted this interpretation.” A reversible path matters as much as forward compilation. An affected person should be able to challenge a property and inspect the wording and evidence that produced it.
Whether this mediation improves anything is an experimental question. It may reduce silent assumption-making while increasing review time. Or it may simply move the labour of formalisation into a stream of generated proposals. A polished restatement may even increase false confidence. The appropriate comparison is not a caricature of unstructured prose. It is competent human clarification and ordinary requirements review, with both incorrect commitments and review effort counted. The proposed evaluation later in this chapter leaves those outcomes open.
The Understanding Compiler is one possible upstream source of candidate requirements and semantic constraints. It could mark “executed” as unresolved, propose its alternative readings, and attach their source conditions before a structured requirement is chosen. Parsing or classifying that request would not prove that the resulting specification preserves the sender’s intent. Natural-language interpretation, reviewed requirements, executable checks, and formal proof remain separate stages with separate evidence. A candidate must not become an operational constraint merely because it fits a machine-checkable schema.
Machines as an audience
This belongs in a book about communication because software has long been an audience for instructions. Command languages, configuration files, contracts, and programs already translate human purposes into machine operations. AI does not invent that boundary. It makes more of the interpretation at the boundary variable, generated, and conversational. That in turn creates new ways for a wrong reading to appear authoritative. The design problem is not to make every conversation executable. It is to decide which parts are ready to become operational commitments.
People often repair ambiguity conversationally, but they may also agree without sharing the same interpretation. Machines cannot rely on that repair when an action has consequences. The permitted effect, its triggering condition, and the actor authorised to cause it need an explicit contract. A mediated representation can help carry a human request toward such a contract, and carry a machine’s observed state back in understandable form. The two directions require different evidence. A request needs interpretation and approval. A report of execution needs independent observation. Neither becomes reliable simply by being fluent.
Operational state is not inherently a final, more advanced rung of language. It is a different kind of object: the records and effects of what a system actually did. A log entry that says “completed” can be wrong or incomplete about an external charge. Making that state legible to a person requires a rendering, but the rendering must link to observations and be clear about gaps. This matters later when Language considers delegation. The person must be able to contest not just a generated explanation of an action, but the authority and evidence for the action itself.
Words at the boundary
Return to “executed.” A mediator could expose it as a bounded, still unresolved interpretation, rather than allow the first generated definition to settle it. A choice among options does not by itself decide whether a duplicate charge is permissible. The meanings have to be attached to the source request and tested with distinguishing examples:
"executed" means:
    attempt
    completed job
    external effect
The value of a typed choice is that the available readings, their definitions, and any refusal to decide can be made explicit in the program’s interface. That is a useful constraint on a component’s output. It is not a guarantee that the component chose correctly, or that the programmer supplied every relevant option. Adding an UNRESOLVED outcome and requiring authorised confirmation prevents an uncertain model choice from silently becoming a requirement. When the choices themselves are defective, the correct response is to revise the option set, not to force the nearest label.
Classification, entailment, label-probability readouts, constrained decoding, and model cascades all predate today’s typed-decision products. Jev is a hosted commercial example, and Laya offers open-weight implementations. But the software-facing idea is wider than either product. A caller specifies a bounded decision and receives structured output without asking for a free-form justification.
The early evidence audit by Tang and Zheng (2026) did not establish a general accuracy advantage for the new readout over comparable existing techniques. Its reported efficiency benefits and limitations belong to the systems evaluated in that early literature. EvaluatorDPT offers a separate example of treating deferral as a learned output. None of these interfaces supplies authority to settle the owner’s requirement, and their probabilities are not automatically calibrated for this use.
One especially relevant reported failure concerns the names of the options. Sun and Xu (2026, v1) exchanged which option name was bound to each rubric while holding the question, state, and rubric wording fixed. In one reported 1,200-decision setting, replacing neutral 0/1 names with semantically loaded no/yes names produced 70.4 additional answer flips per hundred relative to the comparison reported by the authors (95% interval 67.6–73.1). AUC shifted from approximately 0.94 to 0.23, while the type-error rate remained 0%. These are results from the study’s specific models, predicates, and evaluation procedure. They are not a prediction for this queue or for every typed model. Their value here is that a schema-valid response can follow the label’s ordinary associations instead of the definition a programmer intended.
In the queue example, attempt, completed job, and external effect are not neutral strings. Their everyday associations might influence a model even when each is accompanied by a careful definition. The lesson is to preserve the binding among option identifier, rubric, evidence span, selected value, and version. It is also to test perturbations of names and order before trusting the decision. A successful schema check can show that the reply is one of the allowed labels. It says nothing about whether the interpretation, on which a consequential action would depend, is correct.
type conformance ≠ semantic correctness
A typed decision is not the ladder’s “most explicit rung.” It is one narrow way of resolving a named uncertainty at a boundary. A formal invariant, a state machine, and an external-effect receipt express different things, and none of them can be reduced to a single enum. The useful distinction is that a typed answer can be syntactically constrained, while its semantic binding and decision authority still require separate checks.
Context Language Models (Shao and colleagues, 2026) provide a relevant but separate line of work. They treat a model’s working context as an editable file and study what the model learns to retain and update. That is evidence about context management within the paper’s experimental arrangements. It is not evidence that an editable file accurately represents a person’s intent. The semantic record in Chapter 7 has another role: a derived interpretation of a particular source, with its own provenance and preservation duties. A plugin may also maintain a text file, but sharing the medium of storage does not make these mechanisms equivalent. In particular, a model’s ability to rewrite its working context must not silently grant it authority to rewrite an accepted requirement.
maintained state:  what currently applies
typed decision:    a bounded question asked of that state
renderer:          an optional human-facing presentation
A typed decision can consult maintained state and propose a bounded update, but state persistence is not semantic preservation. The accepted interpretation, the model’s latest proposal, the external evidence, and the operational state must remain distinguishable. Generated explanations are useful as presentation, but they are not causal logs. The record of why an action was permitted is the decision itself, its bound inputs, its authorisation, and the checks performed. This brings together the Context book’s distinction between available and admitted information, Memory’s distinction between a stored past and a useful one, and this book’s distinction between intent and reconstruction. It does not transfer measured results from those books to Language.
Hao and colleagues’ continuous latent reasoning work already explored feeding hidden states back into generation, without selecting an ordinary token at every step. Large Concept Models investigate a different approach, operating over sentence representations. The two mechanisms should not be equated. HybridAgent (Zou and colleagues, 2026) extends the latent-feedback setting through interleaved text and latent computation, tool interaction, and dedicated supervised and reinforcement training. Its learned HybridLink maps hidden states into subsequent inputs. What the authors call continuous working memory retains text, latent steps, and tool observations across turns. The paper reports performance on its reasoning benchmarks. It does not test whether the queue owner’s intended rule reaches another participant intact.
Three objects remain distinct: the internal computational representation, the external communication representation, and the transformation connecting them. Continuing a model’s working memory is different from maintaining our source-linked semantic record, or a person’s durable memory. An interesting model-level mechanism is not a preservation guarantee that a plugin can implement through an ordinary hosted-model interface. Nothing in these papers establishes that a latent state preserves a particular owner’s intended business rule. The relevant engineering obligation remains external and testable. What interpretation did the system use, what evidence supports it, and who permitted its consequences?
A proposed cross-rung test
The queue is a useful demonstration, but it is too small to establish that an AI mediator improves requirements work. A fair experiment would freeze several constructed, independently adjudicated task families: retry and side-effect ambiguity, scope-limited policy, temporal constraints, and deliberately underspecified authority. For each task, preserve the original request, a set of distinguishing traces, and the intended acceptance rules in a sealed reference packet. The reader-facing systems must not see that packet.
Compare four conditions using the same task material:
- Ordinary requirements review, with a human analyst clarifying the request.
- Direct formalisation, in which a model produces a structured contract for human review.
- Mediated formalisation, in which the model must expose readings, counterexamples, explicit approvals, and source bindings.
- A strong human-authored structured baseline, where feasible.
Allow UNRESOLVED in every condition. Do not reward a system for guessing when the requirement does not determine an answer. Freeze the model, tools, task order, and review budget, and vary only the mediation being tested.
Score separate outcomes:
- Whether the accepted requirement matches the sealed task oracle on held-out traces.
- Whether its checks find duplicate effects and other planted violations.
- The rate of unjustified or stale confirmations.
- Reviewer time and correction burden.
- Confidence before and after testing, to detect false assurance.
Inspect failures separately at the interpretation, formalisation, checking, and execution-observation boundaries. Repeat model-backed conditions rather than treating one fluent answer as a measurement. A mediator that produces better-looking contracts while raising false acceptance or review cost has not earned promotion. This test is proposed, not run. The scripted example below does not supply its results.
Running it
The reference implementation (ernanhughes/project-language) exposes npm run example:ch12. It uses a constructed job-queue trace and the three readings of “executed”, with a scripted stand-in on a Pi host. It makes no real model call. This is a demonstration of boundary and bookkeeping behaviour. It is not a measurement of semantic accuracy, user comprehension, or formal-proof correctness.
The implemented portion makes a particular interpretation inspectable, and it prevents a model proposal from silently becoming an approved requirement. A chosen option and its definition are bound to the source wording, and a change to that wording invalidates the binding. A check that depends on an unresolved reading returns inconclusive. The model can propose a reading and request a check, but only the reader can settle it, and a later proposal cannot displace a settled choice. Human confirmation is bound to the exact reading and becomes stale when that reading changes.
Under “completed job”, the constructed trace passes despite the two charges. Under “external effect”, it fails. This demonstrates how an explicit choice changes the property that is checked. It does not demonstrate that the choice was the owner’s true intent, or that the live external system prevents duplicate effects.
The example also varies option names and their ordering while keeping definitions fixed. Its deliberately defective scripted selector changes answers, so the local probe detects a constructed name-sensitivity failure. This neither reproduces Sun and colleagues’ model study nor tests a real model. The program does not implement all the ladder’s forms, prove a real queue correct, compare against competent human review, or measure whether a user benefits. Those are open questions, assigned to the proposed experiment rather than claimed as results.
Where this leaves us
Between natural prose and operational state lie several useful kinds of representation: controlled wording, structured obligations, executable checks, transition models, and formal specifications. They are not a universal hierarchy of truth. Making a requirement machine-checkable forces interpretations into the open. But a passing check may faithfully verify the wrong interpretation, and a valid proof may omit the effect the owner cares about. A typed choice is one tool for exposing a disputed reading. It is not a substitute for preserving its source, gaining approval, and checking observable consequences. The mediator’s possible contribution is to keep those commitments inspectable and correctable across forms. Whether it does so more effectively than ordinary review remains to be established.
The preceding chapters supplied the pieces: source-linked interpretations, rendering choices, external material kept distinct, and explicit preservation obligations. Chapter 12 adds a rule for moving among human-readable and machine-checkable forms without confusing a well-typed answer with an accepted meaning. The next chapter, The Semantic Browser, composes those pieces. Its first task is not to generate the most impressive interface. It is to show which source, interpretation, obligations, and checks produced each view, and when the responsible answer is to leave the source alone.
References
- Lamport, L. (2002). Specifying Systems: The TLA+ Language and Tools for Hardware and Software Engineers. Addison-Wesley. (Formal specifications and the limits of checking within a model.)
- Featonby, M. (2021). “Making retries safe with idempotent APIs.” Amazon Builders’ Library. https://aws.amazon.com/builders-library/making-retries-safe-with-idempotent-APIs/ (An engineering account of retries, externally visible effects, and idempotency; not a Language experiment.)
- Hao, S. et al. (2024; revised 2026). Training Large Language Models to Reason in a Continuous Latent Space. arXiv:2412.06769.
- LCM Team et al. (2024). Large Concept Models: Language Modeling in a Sentence Representation Space. arXiv:2412.08821.
- Zou, J., Qi, Y., Chen, S., Bianchi, F., Zhu, S., Lu, P., He, J. & Zou, J. (2026). Hybrid Reasoning Agents. arXiv:2610.18861v1. https://arxiv.org/abs/2610.18861v1. (Sections 3–4; a model-level case of latent computation with textual interaction, not evidence of communicative preservation.)
- Shao, R. et al. (2026). Context Language Models. arXiv:2609.37725.
- Chandrasekaran, S.P. (2026). Auditable Decision Models with Learned Abstention and Real-Time Steering (EvaluatorDPT). arXiv:2605.27768.
- Tang, L. & Zheng, Y. (2026). Typed Decision Models: An Early Evidence Audit and Evaluation Checklist. arXiv:2609.32160.
- Sun, Y. & Xu, J. (2026). Type-Safe Is Not Error-Free: A Constrained Decision Head Follows the Option Name, Not the Rubric Bound to It. arXiv:2609.26758v1. https://arxiv.org/abs/2609.26758v1. (Cited for one reported result in the setting the authors evaluated; the magnitude is not generalised.)
- TypeSafe AI (2026). Jev product description. https://typesafe.ai/blog/introducing-system-one-models-and-jev (accessed 22 October 2026). Vendor material, cited only as a current instance of the interface.
- Convai Innovations (2026). Laya model card and open implementation. Hugging Face, Apache-2.0. https://huggingface.co/convaiinnovations/laya (accessed 22 October 2026).
Research
Not yet researched
This chapter has not yet been researched.