Too Much Information
When a system can produce more potentially useful communication than a person can attend to, the problem stops being how to represent information and becomes which of it should reach them, when, and in what amount.
Language Outline — Part 2 · Attention
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- Before a system can decide what deserves attention, how must one hour of untidy media be broken into units smaller than the source itself?
- Source and meaning units
- Segmentation and decomposition
- Event, information unit and attention unit
- Consensus protocol
- Crash fault and bounded delay
- Round trip and clock drift
- Transcript and temporal grounding
- Lvbench
Candidate source sections: Three moments in one hour; Running it. These locators do not certify the interpretation.
- Capability introduced
- Separates storage segments, events, semantic units and attention units.
- Proposed reader control
- Join the definition at minute 4 to the qualification at minute 53 and open both spans. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Keep both timestamps and the dependency; exact transcript copying is not audiovisual validation.
- Important limitation
- Avoid claiming: Calling scripted span proposals automatic video understanding.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:talk; supplied units and judgments.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Observed evidence
Implemented mechanism / supplied or scripted demonstration; no reader integration. Dated real-feed/production observations are separate and selection remains unadjudicated. The real observation is the separately dated deterministic feed/production record, not a model or reader-benefit result.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
Return to the constructed incident manager from Chapter 13. Suppose the proposed Semantic Browser has produced a usable report view. She opens the account of Tuesday’s outage, and the system offers far more than the report alone. Forty earlier incidents look similar, though similarity establishes no shared cause. There is telemetry for the hour in question, documentation for three dependencies, and a runbook last revised before the migration. The system has proposed three possible contradictions between the report and other sources. Seven candidate diagrams present the causal story from different angles. Fourteen chat excerpts may bear on the incident, alongside the week’s change history and external accounts of similar failures. Some of this material may be wrong, stale or inaccessible to her. None of it has yet earned a place in her attention. This remains a worked design situation, not a successful live deployment.
Some of these items could change her decision. Others would waste her time or actively mislead her. Putting all of them on screen would defeat the reader-time rendering explored in Part I. That part developed ways to derive, check and present candidate representations. It did not establish that a complete Semantic Browser improves a reader’s work, nor that creating and verifying views is free.
Now assume that candidate production is cheap enough to outpace inspection. The bottleneck then moves from can the system make something to show? to which candidate, if any, deserves this person’s limited attention? That is the question Part II takes up.
PART I: representation
What could be shown, and what must it preserve?
        ↓
Candidate generation becomes cheaper than inspection
        ↓
PART II: selection
What may be considered, presented or withheld—and why?
        ↓
Reader outcome remains to be measured
Producing an illustration, an abstract or a related-work list once required substantial human effort. That effort limited supply, but it was never a reliable filter for truth or importance, and readers were overwhelmed well before generative models existed. The newer change is conditional but consequential: systems can now produce plausible candidates faster and more cheaply than people can inspect and verify them. Generating a candidate is inexpensive compared with establishing whether it deserves attention. Selection and checking therefore become first-order design work, rather than consequences of whatever happened to be expensive to produce.
From abundance to a ladder of decisions
It is tempting to call the problem “too much information”, as if quantity alone settled it. Information has long exceeded what one person can consume. What changes here is the rate at which a system can manufacture plausibly relevant objects: summaries, relations, diagrams, alerts and explanations. Each is a candidate for inspection, not a proven benefit.
To see where a selection policy can fail, we need to separate several things that are easily conflated: the existence of an item, the system’s permission to use it, its bearing on a task, the decision to show it, and what the receiver actually gains.
exists  ≠  accessible with permission
        ≠  relevant to this task
        ≠  selected under a budget
        ≠  presented to the reader
        ≠  noticed or used
        ≠  beneficial to the outcome
The following decision record makes the distinction concrete. The stages are ordered for explanation. In a real system, access controls must apply before sensitive content is read, summarised or exposed, and a candidate can be rejected without passing through every later stage.
AVAILABLE   a candidate was discovered
               incident reports, telemetry, chat records
     ↓
ELIGIBLE    permitted and admissible for this use
               access, source policy, sensitivity, usable provenance
     ↓
RELEVANT    plausibly bears on the declared task
               an incident may test the proposed explanation
     ↓
SELECTED    chosen under a space and time budget
               two incidents and a proposed contradiction
     ↓
PRESENTED   shown now or made available on demand
               a source-linked item in the view or margin
     ↓
NOTICED     the reader actually attends to it
               requires observation, not an interface log alone
     ↓
USED        it informs an answer, judgement or action
               may be correct, mistaken or ignored in practice
     ↓
HELPFUL     it improves the declared task outcome
               needs independent outcome evidence
Each boundary asks a different question. Discovery misses candidates outside the searchable collection. Eligibility excludes material the system must not use, even if it would appear valuable. Relevance estimates a relationship to the declared task, but it may miss decisive exceptions that share little vocabulary with the task. Selection allocates finite screen space and time among eligible candidates. Presentation can bury even the right item. An item can be noticed yet not used, or used to support a mistaken decision.
For this reason, helpfulness is an outcome to be measured, not a synonym for use. Improving one boundary may leave another unchanged or make it worse. The resulting record should therefore retain which boundary made which decision.
The compressed form is worth carrying forward, provided it does not erase the difference between permission and relevance, or between use and benefit:
available ≠ eligible ≠ selected ≠ noticed ≠ helpful
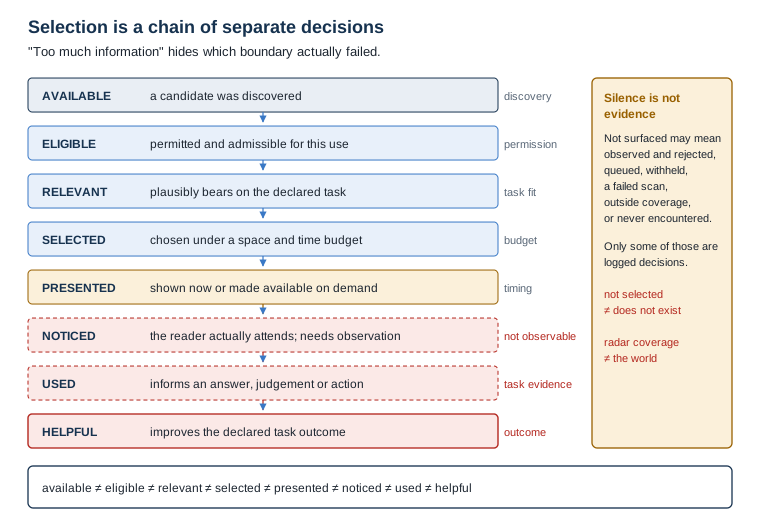

Availability is constrained by what the system can discover. Eligibility is constrained by permissions and source rules. Selection and presentation are constrained by the task, the available evidence and an attention budget. Noticing, use and benefit happen downstream of all of these. The system may observe clicks or dwell time, but these are at most proxies for attention, not access to the reader’s reconstruction of the situation. A system cannot infer improved understanding from exposure, or a changed decision from a click. The final stages need separate evidence from human tasks, just as Part I distinguished preservation from communicative gain.
Abundance is not overload
“Information overload” names a possible failure. It is not a property that can be read off a document count, so abundance and overload must be kept apart.
information abundance ≠ information overload
Abundance describes how much information could be encountered. Overload describes a mismatch between the demands of inspecting and integrating that information and the receiver’s available time, attention and task capacity. The same forty incidents could be manageable during a week-long investigation and overwhelming during a five-minute approval decision. Conversely, one short but ambiguous warning could itself impose too much work. More time or a narrower task can reduce the mismatch without changing the corpus. Surplus information that remains quietly available is not necessarily a burden, however. The burden also depends on how aggressively a system competes for attention.
The objective is therefore not to minimise what a reader sees. Aggressive filtering can hide the one item that would reverse a decision, while indiscriminate display can bury it. The system must allocate attention under competing costs: time spent on irrelevant items, delay in seeing urgent ones, and losses caused by excluding relevant evidence. These costs depend on the task, and they cannot be hidden inside an undifferentiated “relevance” score. As in Chapter 5’s preview problem, a false skip and a false open require separate accounting.
Herbert Simon made the economic point in 1971: abundant information consumes scarce attention, and attention must be allocated. The modern reading of that argument should include more than the instant of looking. Screen space, search effort, resumption after interruption, the cost of evaluating a candidate and the time before a decision are all distinct burdens. In human-computer interaction research, Bailey and Iqbal have examined how interruption cost varies across the boundaries of a task. Their finding is not a universal rule for AI notifications, but it supports treating when information appears as a separate design question.
An attention budget, then, is a declared constraint on a particular activity. It is not a hidden measurement of an individual’s mental capacity. A useful system records the budget it was trying to respect and whether it actually reduced the work.
One early example
This is not only a story about constructed colleagues. I keep a technical site, and in August 2026 I began writing technical books on it in earnest, with AI assistance. In a mid-October snapshot, my own front-matter counting script reported 18 books and 504 chapters dated from 3 August onwards: 1,688,352 words, or approximately 23,000 words a day across that interval. At a notional reading rate of 250 words per minute, the full word count would take about 113 hours to read once, without stopping to check code, evidence or diagrams. The folders also contain supporting files that were not included.
These are one author’s locally counted artifacts. They are not a verified estimate of newly written, distinct or reliable information, and chapter dates and word totals do not measure originality, comprehension or quality.
Two limits matter. First, the weekly figures I counted were uneven; the later weeks were not consistently larger than the early ones. A high sustained production rate is enough to create an inspection problem without an accelerating trend. Second, this example describes one author and one workflow. It is not evidence of the rate at which people in general are creating material, still less the rate at which worthwhile material is being created. Models can also generate images, audio, video and translations, though the costs, validation burdens and useful units differ by medium. The inference worth testing is that candidate production can outrun careful human review across several media. It does not follow that all content is equally cheap, or that the pile is equally valuable.
Part I explored cheaper, more adaptable representations. This part confronts an asymmetric consequence: producing or finding candidates may become faster, while judging fidelity, relevance and usefulness still requires evidence and attention. More output alone is not progress in communication.
The incoming side of my day shows the other half of the problem. I subscribe to more YouTube channels than I can watch. A channel subscription is an earlier choice about a source, not a fresh judgement about each video. Titles and descriptions provide useful but incomplete evidence about an hour-long talk. They may omit its decisive condition, or promise more than the recording delivers. Screening the metadata can save time, but it can also cause a false skip before the content has been examined. That makes it a good bounded test of selection, not a substitute for inspecting the video when the stakes demand it.
That is the starting point of Too Much YouTube, a small application in the reference implementation. It screens incoming titles and descriptions against a declared purpose and exposes the decisions made from those inputs. Chapter 21 discusses its first live run and its limits. At this point, it has not established whether important videos were missed, whether the chosen videos were valuable, or whether a person benefited. Its early role is to make a selection policy observable, including what evidence the policy did not inspect.
Three things a system can do with a good candidate
An eligible, plausibly relevant candidate can receive different delivery treatments. These are decisions about attention, not classifications of truth. A timing decision can also defer a candidate without pretending that it is irrelevant:
SHOW NOW        present in the current task view
MAKE AVAILABLE  keep accessible without claiming the foreground
DEFER           reconsider at a declared time or task boundary
WITHHOLD        exclude from presentation under the current policy
The sidecar discipline from Part I generalises: finding an item does not mean interrupting anyone. A view, an optional margin, a deferred queue and an excluded-candidate record each have different effects on the reader. “Show now” can mean a quiet placement in the main view; an interruption is a further decision requiring its own justification. Equally, withholding is not the same as deleting the underlying source, and deferral is not the same as pretending the item has no value. The reader’s chosen task, and the item’s urgency, evidence standing and timing, each bear on the choice. Later chapters examine how to make these judgements.
qualifies for attention ≠ deserves interruption
Consider how this plays out in the outage. A possible contradiction between the report and a runbook may matter to the manager’s current approval decision, but its assumptions still need checking. It might belong prominently in the main view with an explicit “unconfirmed” label. A related incident from last year could wait in the optional margin. Chat excerpts might be left out until requested, and sensitive excerpts must pass an access check even then. A non-urgent review item could be deferred until after the approval task. These are different actions over the same candidate pool. A scalar relevance ranking cannot, by itself, decide their timing, authority, permission or placement.
What withholding costs
The costs of selection are asymmetric in visibility. Excess display is immediately noticeable as clutter, noise or delay. An excluded item, by contrast, is normally invisible to the reader, including when it would have changed a decision. Yet false opens also matter. Under a fixed budget, time spent examining a weak candidate can displace the evidence that mattered. Neither error has a single universal price. A missed contradiction during an approval decision may be far more costly than a missed optional reading recommendation, and both differ from the cost of a wasted click.
That asymmetry calls for an inspectable exclusion policy, not simply a more attractive inbox. For candidates the reader is authorised to inspect, the system should retain the decision stage, source version, evidence considered, reason for exclusion, expiry or reconsideration conditions, and a way to request reconsideration where the source still exists.
An audit entry is not the same thing as recoverability. Removed content, revoked access or stale evidence may make literal restoration impossible. Nor may an audit trail reveal the existence or contents of restricted material; access controls must apply to both the candidate and its metadata.
Finally, what was never discovered cannot appear in the exclusion log at all. Evaluation therefore needs an independently assembled candidate pool that can expose missed retrieval. Logging makes some mistakes discoverable, but it does not prove that the right information was kept.
Importance is not a property of the item
A final point shapes the rest of the part. It is natural to rank items as if importance were a fixed property. Yet the same incident report serves different work. One engineer must approve a fix, another must write a review, and a third must decide whether a dependency puts her own service at risk. What matters is a relationship among an item, a declared purpose and the current decision context.
This is a design hypothesis here, not a measured superiority result. It also does not authorise a permanent profile of the person. Part II should first establish what can be achieved from the source and an explicitly stated task. Persistent personal knowledge is a separate intervention, and it must earn its value and permission later. A universal ranking may serve as a baseline, but it cannot stand in for a policy about task fit, timing and acceptable omission.
How selection would earn its place
The proposed test is not whether the Radar (the Personal Information Radar, which the final sections of this part introduce) displays fewer items. Instead, construct an authorised candidate pool for several tasks: incident approval, routine technical reading and a time-sensitive update. Have independent reviewers identify task-critical items, required caveats and plausible distractors before the selectors run, and record disagreements rather than hiding them in a single gold label.
Then compare a chronological feed, keyword filtering, a strong task-relevance ranker and a staged policy that can show, make available, defer or withhold. Give each condition the same candidate pool and attention budget. Measure critical-item recall and false skips at that budget, wasted inspections and elapsed decision time, and delayed delivery. Also measure whether the receiver’s answers or decisions improve. Keep task outcome separate from preference and click-through. Where an exclusion is permitted, test whether the reader can inspect and correct the reason without gaining access to restricted material.
An offline replay can assess detection and exclusion against independently labelled cases. It cannot measure whether somebody noticed, used or benefited from what was shown, so a human-task study is needed for those later rungs of the ladder. The study should also include stale sources, misleading titles, genuinely unknown relations and items missing from initial retrieval. Otherwise the selection mechanism would be evaluated only on candidates it was already able to find.
The proposed experiment has not been run. A staged selector that loses important items, or adds friction without improving decisions, should lose to the simpler baseline.
The questions ahead
The rest of Part II separates problems that this introduction has only named. First, a video or long thread must be divided into information units without severing qualifications from the claims they govern. Then source necessity must be distinguished from task relevance, and later from what a particular reader already knows. Standing interests introduce subscriptions without making every match an alert. Different levels of compression and delivery time introduce further trade-offs.
The Personal Information Radar will assemble these mechanisms, but its decisions must still be assessed by what readers missed, what distracted them and what they could do afterwards. The distinction between a declared task and a persistent personal model remains in force until the later parts address it explicitly.
Running it
Reference run. The reference implementation (ernanhughes/project-language) includes npm run example:radar: one invented afternoon, five candidate items, run through a Pi host with a scripted stand-in for the model. It calls no real model.
What it shows: the scripted Radar maintains a stage-by-stage decision record rather than a single numerical priority. Five constructed candidates pass through the implemented policy, and two are withheld with recorded stages and reasons. One keyword-matched item is excluded on eligibility grounds, because it lacks the required grant and falls outside the permitted domain. Keyword overlap cannot override an access gate. The implementation’s names and ordering of intermediate stages are specific to that program. They are not an execution of every conceptual rung in the diagram above. Tests can request reconsideration of a withheld item, which reruns the gates against its current version and permissions. They do not restore a result independently of those rules.
What it does not show: the run has no live model, no human reader and no independent assessment of what should have been found. It does not measure misses outside its five-item pool, the cost of withheld evidence, interruption burden or improved task decisions. Noticed, used and helpful therefore remain unknown, and a “presented” entry is not evidence of any of them. The separately implemented gate for admitting material into a model’s context protects a different recipient and must not be confused with this human-attention policy. The running example establishes record structure and bounded host behaviour. It does not establish selection quality.
Where this leaves us
A system able to generate representations faster than a reader can inspect them must decide which candidates are eligible, relevant and worth presenting under a limited budget. Availability is not relevance; selection is not noticing; use is not benefit. Information abundance and overload are different, and neither fewer items nor more attractive items establish improvement.
Candidates may be shown, made available, deferred or withheld, with permission and provenance checked throughout. Exclusion must be accountable without leaking restricted information or pretending that an audit log guarantees recoverability. Importance is relative to the task and moment. Whether a task-aware policy helps more than a simpler feed remains to be tested against false skips, wasted attention and reader outcomes.
Even relevant information need not be shown now. But before deciding what to deliver, the system must know what the selectable units are and which qualifications must travel with them. A paper offers paragraphs and sections; an hour of video does not announce its useful boundaries so conveniently. That is the problem of the next chapter.
References
- Simon, H.A. (1971). Designing Organizations for an Information-Rich World. In M. Greenberger (ed.), Computers, Communications, and the Public Interest. Baltimore: Johns Hopkins Press, pp. 37–72. (Attention as the scarce resource consumed by information.)
- Bailey, B.P. & Iqbal, S.T. (2008). Understanding changes in mental workload during execution of goal-directed tasks and its application for interruption management. ACM Transactions on Computer-Human Interaction, 14(4), Article 21, pp. 1–28. DOI 10.1145/1314683.1314689. (Empirical study of task boundaries and interruption cost; not an evaluation of the Radar.)
Research
Not yet researched
This chapter has not yet been researched.