Important to Whom?
How should a declared task govern which information units appear, without stripping away qualifications or turning missing evidence into a negative answer?
Language Outline — Part 2 · Attention
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- Given the same source and the same task, what would actually add something for this particular person?
- Source and meaning units
- Prior knowledge and knowledge state
- Known, partial and unknown
- Prerequisite and dependency
- Partial synchrony
- Embeddings, cosine similarity and product quantisation
- Exposure and mastery
- Safe to omit
Candidate source sections: Known is not safe to omit; Running it. These locators do not certify the interpretation.
- Capability introduced
- Uses dated concept-and-sense knowledge evidence without inferring ignorance or a person type.
- Proposed reader control
- Toggle supplied knowledge evidence and show why a prerequisite remains despite familiarity. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Exposure is not mastery; unknown is not ignorance; known does not mean safely omissible.
- Important limitation
- Avoid claiming: Treating declared decay policies as empirically calibrated knowledge models.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:talk; supplied units and judgments.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented mechanism / supplied or scripted demonstration; no reader integration. No measured attention or reader benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
In the previous chapter, the constructed consensus-protocol talk was broken into source-linked units. Each unit is tied to a point in the video: the definition of a fault at minute 4, and the qualification about message delays at minute 53, which is connected to the result it constrains. This chapter starts from that inventory.
Three colleagues now ask the same system about the talk, each for a different reason. Iris needs to know whether the talk establishes the protocol’s safety when network delays are unbounded. Tom is writing a history of consensus algorithms and is comparing their latency claims for one section of his review. Mina wants enough detail to reproduce the demonstration. None of them is asking which part of the video is most impressive. Each is asking what the available evidence can do for a separate task.
The source and the initial inventory of units are the same for all three, and we give their views the same attention budget. The bundles they receive need not be the same. A single digest would hide the differences between deciding whether a guarantee has been established, comparing performance, and reproducing an experiment. This chapter asks the question that comes next in the chain:
Once the system has candidate information units, what makes one of them matter for the task at hand?
Four reasons something looks important
Before answering, separate four different reasons a unit might look important. Each is useful, but treating them as interchangeable makes a selection policy hard to inspect or correct.
SALIENCE           it stands out
SOURCE NECESSITY   it is needed for a faithful account of the source
TASK RELEVANCE     it bears on the declared purpose
PERSONAL NOVELTY   it is new or surprising to this person
A dramatic demonstration is salient, but its importance to the reader’s task still has to be established. A quiet qualification may be essential to interpreting the demonstration. A unit may be necessary for a fair account of the talk and still fall outside the scope of a narrowly stated question. A unit may matter directly to Iris while adding nothing to what she already knows. The four are separate judgements, not four names for a single importance score:
salience ≠ source necessity ≠ task relevance ≠ personal novelty
This chapter isolates the third question, task relevance, and treats source necessity as a constraint on what a selected claim may leave behind. Salience can help locate candidates, but it does not authorise a conclusion. Whether a reader already knows a unit is a different question, reserved for Chapter 17. None of the judgements here requires a lasting profile of the person.
Relevance is a relation
The central claim is that relevance is not a fixed property of an information unit. It is a relation among three things: the unit, a declared purpose, and the context in which that purpose is being pursued. Context here includes the particular question, the source version, the decision conditions and the available budget. It does not need to include a personal history.
RELEVANCE(unit, purpose, context)
Put simply, the same unit can be relevant to one question and irrelevant to another, and the formula asks which question is in play.
A purpose specifies the work the receiver wants the information to perform. It is not the author’s intent, and it is not the truth of the source. It defines the question against which a unit can be relevant, while preservation obligations still constrain what may be said about that unit.
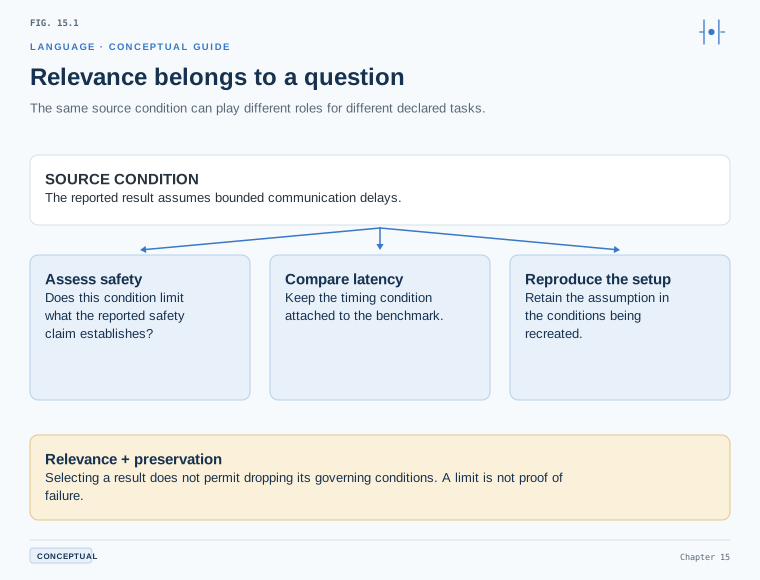
Take the qualification at minute 53: the talk’s reported result assumes bounded communication delays. For Iris, who asks about safety with unbounded delay, this is highly relevant because it limits what the presented result establishes. It does not show that the protocol becomes unsafe. In consensus systems, safety (not deciding inconsistently) and liveness (eventually making progress) are different guarantees, and timing assumptions may bear on them differently. For Tom, comparing latency claims, the assumption matters to interpreting the benchmark, even if he gives it less space than the measured result. For Mina, reproducing the demonstration, it may govern the test conditions she must use. The unit stays the same; the question asked of it changes.
| Reader’s task | What the minute-53 condition contributes | What it does not establish |
|---|---|---|
| Iris: assess safety under unbounded delay | Limits the reported result; the talk does not specify which guarantee the condition governs. | That the protocol is unsafe. |
| Tom: compare latency claims | Qualifies the conditions under which the reported latency should be read. | That another protocol’s result transfers to this one. |
| Mina: reproduce the demonstration | Identifies a timing condition to retain when recreating the demonstrated setup. | That one demonstration proves behaviour across all executions. |
This gives rise to a distinction that is easy to state and easy to lose:
important to the source ≠ important to the current task
A unit can be central to the source yet peripheral to the current task. An example is the paper’s philosophical motivation, when the reader is checking deployment requirements. Conversely, an aside about an operating-system workaround can decide an adoption question even though it occupies one sentence. These are claims about task fit. They are not permission to erase whatever qualifies the facts that remain. Storing one global importance score for each unit would blur these roles, so task-specific judgements must be attached to the task and source version that produced them.
A declared purpose, walked through
Relevance is easier to discuss when the purpose is explicit. The task should name the outcome being investigated without assuming its answer. Suppose Iris writes:
Determine whether the evidence in this talk establishes that the protocol remains safe when network delays become unbounded.
Here are five units from the talk, with the verdict each receives under that purpose:
A  the definition of "fault" (crash failures only)
   relevant to scope. It identifies the fault model addressed;
   it does not establish anything about other fault models.

B  the performance benchmark (two round trips in the demonstration)
   low priority for this question. Observed latency is not a
   proof of safety under arbitrary delays.

C  the bounded-delay assumption
   decisive for interpreting the presented result. Iris needs
   to know which guarantee uses it: safety, progress or latency.
   The talk, as described, does not resolve that distinction.

D  an anecdote about the protocol's history
   peripheral to Iris's declared question.

E  a deployment caveat (the team kept clocks synchronised)
   relevant background for the demonstrated conditions, but
   synchronised clocks alone do not establish the safety claim.
The point is not to invent a numerical ranking. Each judgement records what the unit contributes to Iris’s question, which part of the source supports that account, and whether the contribution is direct evidence, a condition on other evidence, background or not established. Iris can inspect why the benchmark was deprioritised, restore it if needed, or correct the task definition. A stated reason is itself a claim to be checked. A fluent explanation of relevance is not proof that the unit was classified correctly.
When the correct answer is not established
For Iris, the answer available from this constructed talk may be not established by the material examined. The speaker’s bounded-delay assumption restricts a reported result, but the talk does not supply the protocol’s full safety argument. The system must not turn an absent guarantee into evidence of a violation. It should show the relevant qualification, identify the missing proof obligation, and point back to the exact moments where the result and its conditions were stated.
This is more than verbal caution. Safety and progress are distinct properties in distributed consensus. Ongaro and Ousterhout’s Raft paper, for example, explicitly requires safety not to depend on timing while recognising that availability does. Dwork, Lynch and Stockmeyer’s work on partial synchrony distinguishes several timing models. Neither result proves anything about this invented protocol. They show why a task-aware selector must preserve which property a condition governs, rather than merely matching the words “delay” and “safe”.
A useful outcome of selection can therefore be an evidence gap: the source contains a performance demonstration and a timing qualification, but no adequate basis here to decide safety under unbounded delay. That answer may be more useful than a confident yes or no. This is the preservation discipline of Part I applied to selection. The system must not manufacture a conclusion that the source did not supply.
Relevance is not keyword overlap
A convenient first pass is to retrieve units whose words or embeddings resemble the question. That can find candidates, but it cannot decide whether those candidates answer the question. A passage could repeat Iris’s terms (“safe”, “fast”, “resilient”) yet give no evidence about safety under arbitrary delay. Conversely, the decisive passage may speak only of a known upper bound and never use the word “unbounded”. Keyword and embedding retrieval are useful entry points, not adequate tests of task relevance.
lexical overlap ≠ task relevance
The selector needs a bounded account of the task. That account covers the question being answered, the property under investigation, what would count as evidence, and which source qualifications govern that evidence. For Iris, the selector should distinguish a proof of safety from a result about termination or latency. It should also be able to report that the available material does not decide her question. This is the earlier distinction between similarity and relationship, made operational. Related text can be retrieved cheaply, but whether it bears on the required judgement must be assessed separately. A language model may propose that assessment, but neither its relevance label nor its accompanying explanation is automatically correct.
Declared and inferred purpose
A system can come to know a purpose in two ways, and the two should not be confused.
DECLARED PURPOSE   what the person explicitly says they need
INFERRED PURPOSE   what the system thinks they need
A declared purpose is the safer starting point because the reader can inspect and correct it. It can still be incomplete or ambiguous. “Tell me about performance” might refer to latency, throughput, cost or behaviour under failure. A system should make those alternatives visible and ask, or present them as alternatives, rather than silently resolving the ambiguity. The declared purpose should be recorded with its source and revision, so that a later edit can invalidate judgements made for the old question.
There is also a line to hold:
inferred purpose ≠ permission to replace declared purpose
If the system substitutes its inferred goal for the reader’s stated one, selection becomes steering. For example, showing Iris mainly benchmark charts because she is reading about a protocol changes her question from safety to speed. Inferred goals may be offered as suggestions, clearly marked and subject to acceptance. They must not silently replace the declared task. Nor should a guess about the task become a standing personal preference or profile simply because the system made it.

What the task does not get to drop
Relevance alone is not a sufficient reason to omit material. Some information contributes little to the declared question when read on its own, but it is essential to interpreting an item the system has chosen. Source-faithfulness is therefore a constraint on the bundle presented, not merely another relevance score for individual units.
Suppose Tom asks for the reported latency. The two-round-trip demonstration is directly relevant. The bounded-delay condition is not the result he is searching for. Yet if the reported latency was measured or claimed only under that condition, giving Tom the number without the condition makes the answer more general than the source warrants. The qualification must accompany the benchmark, even though the system would not have selected it as a stand-alone answer. The same principle applies to the fault model, the measurement method and any uncertainty governing the result.
task relevance + preservation obligation
Both constrain the selection. Task relevance determines which claims are worth presenting. Preservation obligations determine what must accompany those claims for their scope and force to survive. The result is often a bundle: a finding together with the exception, denominator, assumption or evidence gap that governs it. The qualifying unit can be folded into a short caption or attached by a visible, source-linked note. It cannot be hidden in a separate panel of withheld items while the main view states an unconditional claim. Where the budget cannot accommodate the required qualification, the system should shorten another item, defer the claim, or fall back to the source rather than display a misleading fragment. Records of other withheld, authorised material should remain inspectable without exposing restricted content.
A proposed test of task-specific selection
The question to test is not whether a system can assign convincing relevance labels. It is whether those labels help different readers recover the evidence their tasks require without losing the conditions that make the evidence interpretable.
Use a frozen collection of constructed talks and technical documents with timestamped or passage-linked units. Include distant dependencies, contradictory-looking findings with different scopes, and questions whose best supported answer is “not established”. The consensus example can serve as one diagnostic case, not the whole test.
Before running any selector, have independent reviewers annotate, for each declared task, the evidence-bearing units, their dependencies, and the acceptable answer or justified abstention. Resolve disagreements transparently and retain uncertain cases. Freeze the source versions, task wording, display budget, preservation obligations and scoring criteria. Do not let the system’s own proposed reasons define the answer key.
Compare transcript search and navigation, a lexical or embedding-based ranker, a strong task-aware reranker, and a task-aware selector constrained to carry essential qualifications. Keep the same source set and attention budget across conditions. Test the contribution of dependency closure separately, rather than attributing every gain to the complete architecture.
Report missed decisive evidence, inclusion of irrelevant material, unqualified claims, and false yes/no answers where the evidence is insufficient. Report selection time and reader task performance separately. Evaluate the selected bundle, not just the independent top-ranked units. Record whether the reader could correct a mistaken purpose or restore a withheld unit. A method that improves apparent relevance while increasing unsupported conclusions has not won. This is a proposed experiment; the reference program below does not run it.
Running it
Running it. In npm run example:talk the same constructed units are routed to three readers under the same display budget. Iris, assigned the question about safety under unbounded delay, receives the joined fault definition and timing qualification, the account of partial synchrony, the proof outline and supporting definitions. She does not receive the benchmark or the anecdote. These inclusions do not mean the example establishes safety or its failure.
Tom’s scripted purpose is speed, so he receives the benchmark and an anecdote. The timing qualification is attached to the benchmark because the benchmark depends on it. Mina, reproducing the demonstration, receives the benchmark, clock setup and quorum definition. Another unit judged relevant to her task, the account of how a round works, is dropped when the rendered text exceeds the budget, and the output records that omission. This is a record of scripted choices, not evidence that they were the correct choices.
Each proposed judgement is scoped to a declared purpose and accompanied by a reason and a reference to the constructed source material. It is not reusable as if it were a context-free score. A model’s proposed label waits for human acceptance, and an inferred purpose is kept separate from the declared purpose. Withheld material and the reason for withholding it are represented in the example, and reopening is supported for authorised items. These controls make decisions inspectable. They do not establish that the citations support the proposed reasons, or that the budget preserved every required dependency.
What it does not show: validated relevance classification or better reader outcomes. The judgements, explanations and examples are hand-authored or scripted. The program does not determine whether a unit truly answers a purpose, whether a qualification governs safety rather than progress, or whether a reader reaches a better decision. Its source references establish where text came from, not that the interpretation is correct. The proposed comparison above remains unrun.
Where this leaves us
Task relevance is a relation among an information unit, a declared purpose and a context. It is not a permanent property of the unit. It differs from salience, general source importance, retrieval similarity and personal novelty. A relevance judgement needs a reason that can be challenged, but the reason is still a claim to be verified. The reader’s declared purpose is primary. Inferred purposes may be offered, but they must not be silently substituted. A selected claim must carry the qualifiers it depends on. Sometimes the most faithful and task-relevant response is that the source does not establish the requested answer.
Even when the task is correctly expressed and the evidence bundle is faithful, one further difference remains. Two people facing the same question may need different amounts of explanation, because one already understands the prerequisites and the other does not. Suppose Iris has spent two years working on consensus protocols. The definition of a crash fault may be familiar to her, yet its exact meaning in this talk still constrains the argument. Familiarity alone does not make a prerequisite safe to remove.
same unit
same task
different person
        ↓
different value
That leaves a narrower question about the receiver: what evidence, if any, justifies believing she already knows a concept in the sense needed here? Chapter 17 asks how such a belief should be represented, and why even well-supported familiarity does not automatically grant permission to omit a source-specific definition or qualification.
References
- Dwork, C., Lynch, N. & Stockmeyer, L. (1988). Consensus in the Presence of Partial Synchrony. Journal of the ACM, 35(2), 288–323. (Cited to distinguish models with different communication-timing assumptions, not to assess the invented protocol.)
- Ongaro, D. & Ousterhout, J. (2014). In Search of an Understandable Consensus Algorithm. Proceedings of the 2014 USENIX Annual Technical Conference, 305–319. (Cited for the explicit distinction between timing-independent safety and timing-dependent availability in Raft.)
Research
Not yet researched
This chapter has not yet been researched.