A Video Is Not an Hour
Before a system can decide what deserves attention, it needs units smaller than the source. What counts as a unit, and why does the answer depend on both the source and the task?
Language Outline — Part 2 · Attention
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- Once the system has candidate information units, what makes one of them matter for the task at hand?
- Source and meaning units
- Salience
- Source necessity
- Task relevance and personal novelty
- Declared and inferred purpose
- Lexical overlap
- Safety and performance
- Preservation constraint
Candidate source sections: When the correct answer is not established; What the task does not get to drop. These locators do not certify the interpretation.
- Capability introduced
- Makes relevance a purpose-bound relation constrained by source necessity.
- Proposed reader control
- Switch among Iris/Tom/Mina declared questions and inspect attached qualifiers and withheld units. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Keep safety distinct from progress/performance; not established is not false.
- Important limitation
- Avoid claiming: Hand-authored relevance decisions masquerading as classifier accuracy.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:talk; supplied units and judgments.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented mechanism / supplied or scripted demonstration; no reader integration. No measured attention or reader benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
A person has an hour of video and ten minutes to decide whether it contains an answer she needs. (The person, her colleagues and the talk are constructed for this book, as are the examples that follow in this part.) The talk is a conference presentation about a consensus protocol, recorded last spring. She cannot watch the whole thing. She could scrub through random moments, or search an automatically generated transcript of perhaps fourteen thousand words of imperfectly recognised speech. The familiar interface offers one coarse choice: watch or skip. Her actual question is narrower: does this talk establish anything about the failure conditions our service faces, and where can I check the speaker’s answer? A title, a transcript hit or a convincing clip may each help her find the relevant part, but none of them alone guarantees that she has the whole answer.
Part II is about selection, and selection needs candidates at a usable size. A paper already offers visible sections and paragraphs, although its claims and their qualifications may cross those boundaries. An hour-long recording has playback time and perhaps captions or chapter markers, but its logical units are less obvious. A system that treats the recording as a single candidate can recommend the whole hour or reject it. It cannot reliably identify the two minutes that explain a decision without first locating and relating smaller pieces. The first task is therefore not ranking the fragments. It is proposing what the fragments actually are.
SOURCE VIDEO (one hour)
      ↓ locate observable moments
segments · speech acts · demonstrations · transitions
      ↓ extract and link source-grounded content
claims · results · assumptions · exceptions · relations
      ↓ assemble task-sized candidates
information units with evidence spans and dependencies
This chapter’s job is to specify how a long source could yield inspectable information units without letting its segments pass for meaning. The system may need smaller units, or a bundle of several distant moments. Occasionally the source as a whole remains the right unit. Whether any resulting unit is important to the current task is a later decision. Decomposition should not smuggle a relevance verdict into the source record.
Three moments in one hour
Here are three moments stipulated by the invented talk. Their timestamps make the example checkable as a design exercise; they are not observations from an actual recording.
At minute 4 the speaker quietly defines the fault model: in this talk, a “fault” means a node crash, not arbitrary incorrect behaviour. No slide flags the definition. At minute 42 she demonstrates a particular execution in which the protocol commits in two round trips while some nodes crash. At minute 53 someone asks whether the result still holds when message delays grow without bound. The speaker says that the demonstrated latency claim assumes bounded communication delays.
These are separate limits. One concerns which failures the protocol considers. The other concerns which timing conditions the fast-commit result assumes. Neither moment alone tells the reader everything about the protocol’s guarantees.
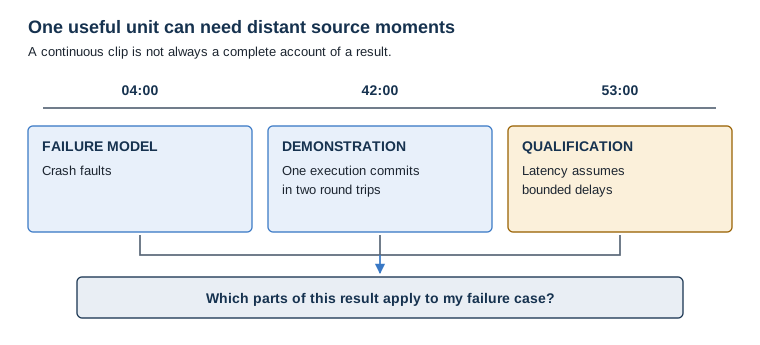

Each moment is brief, and the demonstration is the one most likely to attract attention. But an account of what the speaker showed needs all three: the failure model, the observed execution and the timing qualification. Without them, “two round trips” can be misread as an unconditional guarantee. Nor does a successful demonstration prove that the protocol is safe in every execution that satisfies those assumptions. In distributed systems, safety, termination and latency are different claims. A timing assumption that limits completion time does not, by itself, settle safety under unbounded delay.
So the decomposed unit must preserve the distinction between three things: an observed run, the speaker’s claimed scope, and any independently established result. This is why a polished summary that keeps only minute 42 can be substantively misleading, even if it invents not a single new number.
This also makes the recording too coarse to serve as the only unit. Fixed thirty-second windows have the opposite problem. The definition at minute 4 and the qualification at minute 53 sit forty-nine minutes apart, so no single window carries the relationship between them. Windows can still be excellent aids for indexing and playback. What fails is treating a window as if it were a self-sufficient claim. A usable representation must be able to link distant evidence while preserving the route back to each moment.
The live application introduced in the previous chapter, Too Much YouTube, still screens titles and descriptions. In its documented state, it does not process transcripts. A video whose important condition is spoken only at minute 53 can therefore be selected or withheld for reasons that never inspected that condition. Transcript-aware processing is a proposed next step, not an established capability of the live feed.
The chapter’s separate runnable example uses an invented, timestamped transcript to demonstrate the shape of source-grounded units. It does not establish that speech recognition is accurate, that the units can be discovered automatically, or that the live subscription screen can already use them.
Four things called a unit
The word “unit” can refer to at least four different objects. Conflating them is how a convenient slice of media becomes a misleading claim about its contents.
storage unit ≠ presentation unit ≠ meaningful event ≠ attention unit
The storage unit is the video asset, with its version and associated audio, images and captions. A presentation unit is what playback shows or navigates to: a chapter marker, a slide interval or a fixed window. It may or may not follow the talk’s logic. A meaningful event is an observable occurrence in the source: the speaker makes a claim, a slide changes, a demonstration runs, an objection is raised. An attention unit is a candidate the reader could consider for a specific job, perhaps one claim, or perhaps a linked bundle of claim, definition and qualification.
An event is evidence that something was said or shown. It is not automatic evidence that the assertion is true. Nor must an attention unit coincide with one event, one file or one continuous interval.
Four questions
Getting from the media to attention units means answering four connected questions. These form a workflow rather than an irreversible sequence. Finding a later qualification can change how an earlier span should be segmented or linked. A declared task may guide the search, but it must not change what the source is reported to have said.
What happened? Record observable events and speech acts: the speaker defines a term, claims that a result holds, runs a demonstration, receives an objection or changes topic. Attribution matters. “The speaker claims X” can be grounded by a faithful quotation even when X is false. “X is true” is a different assertion, one that requires further evidence. An introduction or applause may matter to an editor even if it is irrelevant to an engineer’s question. The first pass inventories candidates without pretending to know which one the reader needs.
Where does each begin and end? Temporal segmentation supplies addresses for events. It does not prove their meaning. A timestamped transcript may be a sensible, inexpensive first pass for a lecture dominated by speech. But captions can omit negations, confuse technical names or lag behind the sound. A silent failed demonstration, a slide that contradicts the narration or a meaningful gesture may never appear in text. Audio and visual inspection may therefore be necessary for particular claims, and human reviewers may disagree about exact boundaries. A system with transcript-only access should label its evidence accordingly and avoid implying that it inspected the recording. If the source cannot be checked, precise-looking timestamps do not remove the uncertainty.
What belongs together? Adjacent moments can discuss unrelated things, while non-adjacent moments may have a typed dependency: defines the term used by, qualifies the result at, contradicts the earlier claim, or supplies evidence for. Minute 4 scopes the terminology used at minute 42, and minute 53 limits the latency claim. Each link is an interpretation to be supported by the relevant spans. It is not a fact supplied by temporal proximity. A wrong link can be as damaging as a missing span, so the relation type, its direction and its scope each need their own checks.
What unit should selection operate over? A selected candidate might be the isolated definition, the demonstration, or a bundle containing the demonstration and every qualification needed to interpret it. The declared task and the available attention budget shape its presentation, but necessary dependencies constrain what may be removed. This is a packaging decision made after the evidence has been identified. It is not permission to rewrite the evidence to fit a summary length. The next chapter addresses which packages are relevant to a particular purpose.
Segment, event, information unit
The distinctions that follow from this can be stated plainly:
segment  ≠  event
event  ≠  information unit
information unit  ≠  relevance
A thirty-second segment can contain several events, and a demonstration can span minutes. An event may carry many claims, and a qualification may occur far from the claim it governs.
Call an information unit a source-grounded proposition, observation, demonstrated event or qualification. It has an identity, evidence spans and explicit dependencies on other units. An information unit is not necessarily safe to keep or drop independently. For example, the claim “the demonstration committed in two round trips” must stay linked to the failure-model definition and the timing qualification when the task is judging its applicability. Atomic pieces help indexing; the linked bundle preserves the interpretation. In short, information units are candidates for selection, while events identify where the evidence appeared.
The final distinction, information unit ≠ relevance, is especially important. The record may preserve that the speaker asserted a latency result and later narrowed its conditions. Whether a particular engineer should see that bundle now depends on the engineer’s declared question, access rights and decision context. Relevance should govern selection. It should not silently decide which parts of the source are allowed to exist in the record.
The Understanding Compiler could propose semantic units from an identified transcript, including the minute-42 result and the minute-53 qualification. Those proposals are candidate interpretations of transcript evidence, not recovered meaning from uninspected audio or images. Its source-linked units could feed selection without deciding relevance.
There is also a second boundary. An alert that says only “commits in two round trips” may discard the condition present in the source inventory. Comparing the alert’s proposed meaning with that inventory could expose the loss, subject to independent checking. It would not show that the recipient noticed, understood or benefited from the alert.
The same video, four decompositions
No single decomposition suits every use. A video editor, an engineer, a student and a legal reviewer need different boundaries. That does not mean every segmentation is equally defensible. Each proposed unit still has to correspond to evidence actually present, and each necessary relation must be preserved. The categories below describe tasks, not permanent types of people:
editor      scene changes, cuts, sections to reuse
engineer    fault transitions, failure modes, assumptions
student     concept explanations, definitions, worked examples
lawyer      claims, qualifications, what exactly was said
The same recording may therefore support several task-specific presentations built over a shared, source-grounded inventory. This matters for continuity with Chapter 7. Re-extracting the same fact from scratch for every task invites inconsistent readings. Freezing a single task-specific segmentation invites omissions. A plausible design keeps stable event addresses, source quotations and known relations, then assembles task-dependent units from them. That is an architectural option to evaluate, not a guarantee that a common record captures the whole video. The unmodified recording, and the versions of its transcript and captions actually used, remain the authority for what was said and shown.
This extends Chapter 14’s distinction between the existence of information and its usefulness to a recipient. Even candidate boundaries may change with a declared task, but their evidence must not. A derived unit should retain the source identity and version, the modality inspected, the relevant start and end times, and any non-contiguous spans. Links to the recording must remain usable. If a caption is corrected or an upload is replaced, affected units and dependent digests need reconsideration. Versioning and provenance make that reconsideration possible. They do not establish that the extracted claims are right.
Why scoring the pieces one at a time fails
Consider a selector that scores every thirty-second window independently for its similarity to the engineer’s question. The minute-42 demonstration will attract attention. The brief minute-4 definition may look unremarkable, so the selector could omit it, even though it governs the demonstration’s scope. The problem is not that every local score must fail. It is that local evidence alone does not capture distant dependencies. A score for the demonstration must not authorise a claim about the whole protocol while its qualification remains unchecked.
One response is to let candidate fragments refer back to the wider source, retrieve their dependencies and validate the resulting bundles before presentation. This need not mean feeding an entire hour into a model on every query. A first pass can index timestamps, speaker turns and tentative relations. Targeted searches can then fetch supporting spans, with escalation to broader inspection when a claim depends on material elsewhere. Any shortcut trades cost against the chance of missing an unseen qualifier. A design that never tests distant links may consistently retain the loud claim and lose the quiet limit that determines what the claim means.
A fixed output count is another compression decision disguised as extraction. An hour does not contain exactly five, fifteen or thirty independent ideas. Asking for five candidates imposes a budget. It does not discover that the source had five. A dense talk may lose essential conditions even at thirty, while a repetitive one may add nothing after eight. The record should distinguish how much source-grounded material was identified from how many items the display budget allowed. Experiments should vary the budget and report what happens to required qualifications, distant dependencies and false skips. Reporting only whether readers prefer the shorter digest is not enough.
Nor is a unit inventory self-validating. Two careful annotators may split a demonstration differently, disagree about whether a caveat qualifies one claim or several, and miss different specialist details. Agreement on obvious headline events cannot establish complete coverage. An evaluation needs independently assembled obligations, adjudication of disputed links and some deliberately difficult cases: implicit limitations, distant definitions, caption errors and claims whose status changes during questions. Disagreement is evidence about the difficulty of the task. It is not an instruction to erase the minority interpretation. A benchmark built only from easy, agreed-upon fragments would systematically favour neat but incomplete digests.
The same problem elsewhere
Video makes the difference between a file and its information particularly visible. But long threads, meeting recordings, podcasts, notebooks and codebases share the problem. Their parts can be separated for storage while remaining dependent in meaning.
LVBench (Wang and colleagues, ICCV 2025) offers one relevant background result. It evaluates long-video temporal grounding, summarisation and other skills separately, and reports difficulty for the evaluated multimodal models. Its visually heavy videos and task design do not establish that a transcript-based system can discover all the units in a technical lecture. Nor do they show that timestamped summaries improve human selection. Those are separate claims for this book to test.
Running it
Running it. The reference implementation (ernanhughes/project-language) includes npm run example:talk. It accepts an invented talk in the time-stamped caption format printed by the YouTube transcript skill, for example [4:02] For the purposes of this talk, a fault means a crash and nothing worse. The transcript is pinned by a hash. A source-grounded unit names one or more exact caption spans. A scripted stand-in for the model proposes the spans, role and dependencies. The program copies the text from the named spans rather than accepting free-form model quotations. It rejects references to nonexistent lines and refuses dependencies on rejected units. Its non-contiguous unit joins minute 4 with minute 53 and preserves both time addresses. These are implementation checks on an invented transcript. They do not prove that the captured captions match a recording, or that the proposed semantic links are correct.
The program also illustrates a specific, constructed failure of local selection. Fixed windows are scored against a task about unbounded delay. The isolated minute-4 definition is assigned no matching evidence and is dropped, while the later timing qualification is retained. This establishes only that the chosen synthetic scorer and fixtures exhibit the problem. It does not establish that all fixed-window retrieval fails, or that the proposed dependency-aware approach performs better on unseen talks.
What it does not show: that a real model can identify good units. The proposals are scripted. The input is a short constructed transcript rather than the audiovisual talk, and nothing in the example sees what was never transcribed. Exact span copying and valid timestamps protect against some fabricated quotations. They do not validate speech recognition, relation labels or completeness. No reader has been tested, and no claim about the live Too Much YouTube feed follows from the demonstration.
How the decomposition would be tested
The proposed experiment should start with complete, permitted recordings for which reviewers can inspect audio, video, slides and any available transcripts. Include material like the invented consensus talk: a headline demonstration, an earlier definition, a distant qualification and at least one plausible but incorrect link. Annotators independently identify source spans, claims, qualifications and necessary cross-span dependencies. Disagreements are retained and adjudicated before a test split is frozen. The final material is held out from any examples used to tune the extractor. Separate source versions and modality coverage should be recorded, so the experiment can distinguish transcript errors from reasoning errors.
Against the same recordings, declared tasks and time budgets, compare four approaches: human chapter markers or transcript search, fixed-window extraction, a strong transcript-based method that works across the whole source, and a dependency-aware method that can assemble non-contiguous evidence bundles. A multimodal condition may test whether visual and audio evidence helps on cases the transcript misses. It should not be mixed into claims about a text-only pipeline.
Measure span localisation, claim attribution, recall of qualifiers and dependencies, invented or reversed links, and selection failures at the specified budget. Then give readers realistic questions. Can they locate the evidence, state the assumptions and avoid conclusions the talk did not warrant? Measure time, task accuracy and false confidence separately from satisfaction. Compare the added value with indexing and review costs, and include an unchanged-source route for cases where uncertainty is high.
These are proposed tests, not reported results. A method that finds more timestamped fragments but drops their governing qualifications has not solved decomposition. A method whose complete provenance bundles impose more work than transcript search, without improving reader decisions, has not earned its place either.
Where this leaves us
An hour of video is one stored source, but it can carry many distinct claims, events and conditions. Presentation windows, observable events, source-grounded information units and attention units are not interchangeable. The path between them requires locating what was said or shown, placing temporal boundaries, identifying distant dependencies and assembling candidates for a stated task.
Those decisions may be revised, and a reader’s task may change the bundle. A task cannot change the source evidence. A timestamped transcript is useful only within the limits of what it captured. A non-contiguous bundle is useful only if its links are correct. Each representation needs source versions, time spans, modality coverage and a way back to the recording. Extraction accuracy, faithful preservation and reader benefit remain separate questions.
Suppose the system has identified candidate units and correctly linked the minute-4 definition and the minute-53 qualification to the minute-42 demonstration. It still has not decided what deserves this engineer’s ten minutes. A unit may be conspicuous, necessary to represent the source fairly, relevant to the immediate question or genuinely new to the reader. These are different judgements. The next chapter begins with one of them: important to whom, and for what purpose?
References
- Wang, W., He, Z., Hong, W., Cheng, Y., Zhang, X., Qi, J., Ding, M., Gu, X., Huang, S., Xu, B., Dong, Y. & Tang, J. (2025). LVBench: An Extreme Long Video Understanding Benchmark. Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), pp. 22958–22967. Preprint arXiv:2406.08035. (Background evidence on long-video evaluation, including temporal grounding and summarisation; not an evaluation of the transcript-to-unit method proposed here.)
Research
Not yet researched
This chapter has not yet been researched.