From Channels to Semantic Channels
What would it mean to subscribe not to a creator, a feed or a topic but to a relationship in the world? A standing, inspectable relational interest over changing information, and the care it needs.
Language Outline — Part 2 · Attention
Proposed reader guidance, pending authorial review. Preservation obligations are candidates, not author-accepted semantic truth. The ordinary chapter remains the primary source.
- Central communication question
- How should a qualifying item be rendered at different resolutions, and what determines where compression must stop?
- Source and meaning units
- Resolution and progressive disclosure
- Glance, brief, summary, detail and source
- Safety and liveness
- Preprint, peer review and lemma
- Omission, addition and distortion
- Compression stop rule
- Refinement and drift
Candidate source sections: What each level owes; Where compression must stop. These locators do not certify the interpretation.
- Capability introduced
- Defines task-sufficient resolution with a preservation stop rule.
- Proposed reader control
- Expand a prepared item from glance to source, keeping item/version and qualifiers visible. Availability is limited to the implementation status below.
- Preservation question / obligations
- Candidate obligation
- Compression cannot strengthen a claim; every retained claim brings its conditions and source path.
- Important limitation
- Avoid claiming: Nested unit IDs being called semantic monotonicity.
- Demonstration or source fallback
- Read the original chapter - no interactive website capability is claimed.
Reference implementation example: npm run example:radar; scripted policy trace.
- Actual implementation
- Website: OUTLINE_ONLY. Reference: BOUNDED_MECHANISM_REPORTED_TESTED.
- Evidence status
- Tested mechanism
Scripted demonstration
Implemented mechanism / supplied or scripted demonstration; no reader integration. No measured attention or reader benefit.
Semantic fidelity: NOT_INDEPENDENTLY_VERIFIED. Reader benefit: NOT_MEASURED.
Iris follows fourteen conferences, nine labs, thirty authors and four preprint feeds on distributed consensus. In this constructed example, a result appears in March in a distributed-databases paper by authors outside those channels. It describes a mechanism that operates under different timing assumptions from the ones her team adopted. The paper never uses the word “consensus”, so her usual alerts do not find it. In June she encounters it by accident, cited in a thread about something else.
She has spent three months designing around an assumption that the unfamiliar result might help her reconsider. But might matters. Another mechanism operating without a particular delay bound neither refutes her protocol’s safety claim nor shows that the mechanism transfers to it. Establishing either connection would take additional technical work.
Her subscriptions did what their channels were configured to do: deliver publications from selected sources. What they could not promise was to find work elsewhere that might bear on a specific assumption. Even a system watching the wider literature would have two separate jobs. It would need to discover the March paper, and then determine whether its result actually changes anything about Iris’s design. The second job cannot make up for a failure at the first.
Most of this part has begun with an explicit question. Someone asked what matters in a talk or a collection, and the system selected information for that purpose. Iris’s concern about the assumption persists when she closes the browser. She could ask a system to inspect incoming material on her behalf, within a boundary she declares. That does not make the system omniscient, and it does not authorise it to interrupt her. It raises a narrower question about the object of the standing request:
What would it mean to subscribe not to a source, a creator or a feed, but to a relationship in the world?
What people subscribe to now
The objects people subscribe to today are familiar:
a creator a publication a topic a feed a keyword
Each is a useful but coarse agreement. Following a creator admits what that creator publishes; it does not promise to find relevant work elsewhere. Keyword alerts depend on the language chosen by authors and indexers. Topic feeds can use richer classifications, and a well-configured search alert can be remarkably effective. But none of these by itself requires a testable claim about how a new item bears on one particular assertion.
The gap is not that existing channels are foolish. It is that finding material about a subject and finding evidence that changes a specified relationship are different tasks.
The earlier chapters provide a vocabulary for the second task. Part I distinguished textual similarity from source-supported relations. One claim may support, qualify, contradict or supersede another, and those labels require scope and evidence. A standing interest can therefore be expressed as a query for a particular kind of relation to a named anchor, meaning a fixed claim the watch is built around. The architectural ambition is to apply the same discipline as new material arrives. It should not assume that relation labels have become reliable merely because they have names.
typed relation
      ↓
standing relational query
      ↓
semantic channel
The difference is the one between two questions:
topic subscription ≠ relationship subscription
A topic subscription asks which new items belong to, or discuss, X. A semantic subscription asks which newly observed items might support, qualify, contradict or supersede a specified claim about X. The answer is initially a candidate with an evidence trail. It is not a determination that the reader’s understanding should change. Whether it actually changes belongs to further examination, either by the reader or by an appropriately validated process.
A small object
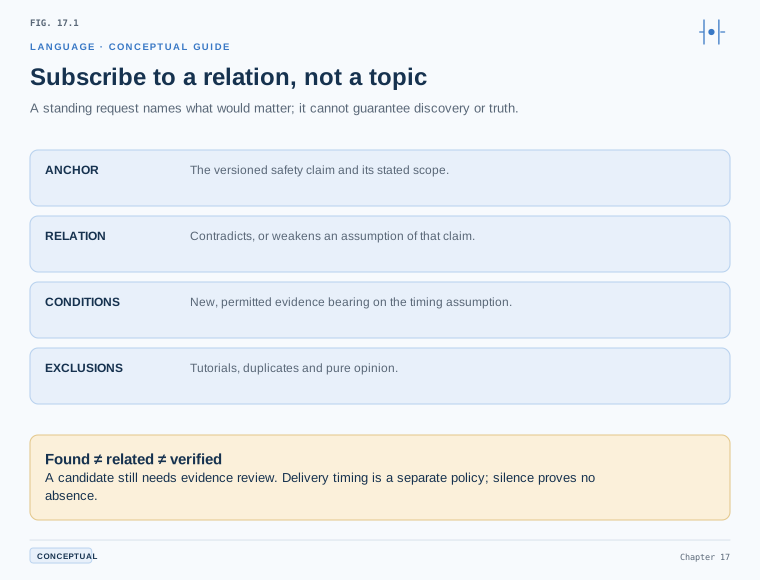
The declarative meaning of a semantic subscription can start with four fields. Keeping those four visible makes the request understandable. It does not mean an operational system can dispense with source identities, permissions, versions or an audit history.
ANCHOR       what the subscription is about
RELATION     what kind of change or connection matters
CONDITIONS   when something qualifies
EXCLUSIONS   what should not trigger it
Here is Iris’s, written out:
ANCHOR
this protocol's stated safety claim
(in the approved specification, including its scope)

RELATION
contradicts, or weakens an assumption of

CONDITIONS
a newly observed, peer-reviewed result
with evidence that bears on the stated timing assumption

EXCLUSIONS
tutorials
duplicate reporting
pure opinion
This is more specific than “subscribe: consensus algorithms”, but specificity does not solve discovery. To match the March paper, the system first has to encounter it through a permitted collection, search or citation trail. It then has to connect a claim in that paper to Iris’s versioned anchor, checking whether the timing model, failure assumptions and claimed property are comparable. The relation-first query tells the system what evidence to seek and how to assess a candidate. It does not guarantee that unseen evidence will be found.
An anchor should therefore identify the actual claim and source version, not merely a topic label or a document title. If the specification changes, the old watch must not silently acquire a new meaning. It should be marked for review, migrated with explicit approval, or retired. In each case, a record of what the earlier watch was asking should be kept.
Here are three more examples, to show how different these are from topic subscriptions:
"Tell me when a new result weakens the assumption that this
protocol needs bounded network delay."

"Show me new evidence that contradicts the causal claim in
this paper."

"Tell me when this API's recommended practice is superseded."
These are standing relational interests rather than ordinary topic labels. Each asks for a potential change affecting a declared anchor, and each carries a different evidential burden. Contradicting a causal claim requires comparable populations, measures and conditions. Superseding an API practice requires an authoritative version history, not merely a newer blog post. Weakening an assumption may mean providing a relevant counterexample or a workable alternative, and neither of these automatically falsifies the original result. The interface must say which claim is being made and which remains conjectural.
Delivery is deliberately absent from those four semantic fields. A subscription determines what may qualify for consideration. A separate policy determines whether a candidate should be made available, included in a digest or delivered now. Keeping those decisions apart matters. A possible contradiction can be important without being confirmed, and a confirmed update can be important without being urgent. The next chapters address amount and timing.

Subscriptions are not recommendations
Recommendation systems sit nearby, and the difference is worth being exact about.
RECOMMENDATION   the system infers what you may want
SUBSCRIPTION     the person declares what relation should matter
A recommender typically chooses items predicted to be useful or engaging, sometimes using behaviour and other context. A semantic subscription instead starts with a relation the reader explicitly declares. The two approaches can share retrieval, ranking and modelling techniques. They differ in who sets the criterion and in what counts as success.
Iris can ask to see evidence that challenges her design, even if she has never clicked on such material before. But this does not guarantee that a relation-based search will discover material a conventional search would miss. A strong keyword or hybrid-search alert remains a baseline the semantic channel must beat, not a straw man.
Matching is not confirmation
The discipline from Part I carries forward. Finding a paper is candidate discovery. Recognising passages that could connect it to Iris’s anchor is relation proposal. Establishing that the passages really share the relevant assumptions and support the asserted relation is a further evidential judgement. None of these stages may be silently substituted for the next.
candidate found ≠ relation established ≠ claim verified
A standing query may yield an unconfirmed candidate. It should then say something like: Possible challenge to the bounded-delay assumption; applicability to this protocol unresolved. It should also show the two passages on which that assessment rests. “Possible” and “confirmed” are not probability decorations. They should refer to explicit review states and to the basis for each state. A person confirming that two texts are related has not thereby certified either underlying technical claim. If a match is unsupported, the system should decline the stronger label rather than presenting uncertainty in confident typography.
Scope is where this becomes difficult. A paper about another protocol, another fault model or another timing assumption may offer an analogy, an alternative design or a genuine counterexample. These are not interchangeable relations. In distributed systems, even “bounded delay” can refer to different models. The classic work on partial synchrony distinguishes bounds that are unknown in advance from bounds that hold only after an unknown time. More importantly, an assumption used to prove progress need not play the same role in a safety guarantee. The system has to identify which property, under which assumptions, the incoming evidence bears on.
Iris’s March paper is therefore a reason to investigate, not an automatic refutation. Peer review, where the subscription requires it, is an eligibility condition. It is not a guarantee that the result is correct or applicable.
A standing query is not an all-seeing search
There is an older engineering precedent here. Continuous query systems register a declarative query and evaluate it as a stream changes. Arasu, Babu and Widom’s CQL is one example. The new question in this book is not whether a query can persist over time. It is whether the predicate, the condition the query tests, can express a useful, source-grounded relationship between claims while respecting the limits of extraction and interpretation.
A practical channel has at least three stages, and each can fail independently:
- Coverage: which permitted sources were actually observed.
- Candidate discovery: which observed items were retrieved for consideration.
- Relation assessment: which proposed links survived scope and evidence checks.
A failure in the first two stages cannot be repaired by a perfect relation classifier. A label that looks plausible cannot repair a bad scope comparison. An alert should be able to say what it searched and what it cannot claim to have searched. A promise to monitor “the world” would be indefensible. A promise to monitor named feeds and searches, with declared limits, could be audited.
An interest is not a profile
The last chapter introduced a narrow, correctable estimate of prior knowledge. Here the system needs a different object: an explicit request to monitor an anchor for a specified relationship. The request must not be inflated into a claim about the person’s tastes, identity or beliefs.
standing subscription  ≠  profile of the person
explicit standing interest  ≠  inferred identity
Iris can subscribe to “possible changes to the assumptions in this specification” without licensing a general profile of her interests. She should be able to inspect, pause, edit, expire and delete that request. She should also be able to see its original wording beside any machine-compiled query. Compilation may expand synonyms or follow citation paths internally, but it must not silently change the conditions that qualify an alert.
The operational record should show who authorised the watch, which version of the anchor it targets, when it last ran, what sources were covered, and why each reported candidate matched. Access to the subscription and its resulting items must follow the underlying document permissions. Even a title, or the mere existence of a match, can reveal a restricted project.
How a semantic channel goes wrong
The semantic request is small. Its failure surface is not. Besides the mistakes of ordinary alerts, a standing relational query can fail during discovery, interpretation, maintenance or delivery. Those failures need separate names because they need different remedies:
too broad          floods her with weak candidates
too narrow         misses consequential material
coverage gap       never encounters a relevant source
wrong relation     mistakes analogy or similarity for contradiction
scope error        ignores differing assumptions or claims
stale anchor       monitors an outdated claim or source version
silent expansion   changes the declared watch without approval
permission error   reveals restricted content or even its existence
Silent expansion is a particularly serious governance failure. The machine stops executing the reader’s standing request and substitutes another. But the most difficult technical failure may be the invisible miss. A poor alert is noisy. A missed paper may leave no trace in the reader’s view at all.
The subscription therefore needs a maintenance policy. Changes should be made through explicit edits, not covert broadening. Stale anchors should have an expiry or review point. The reader should be able to see enough about monitored sources and recent runs to notice coverage limits. Pausing or deleting the request must stop future monitoring. None of these controls proves that the watcher saw every relevant result.
Testing whether relational subscriptions earn their cost
The claim to test is not that the interface can store four fields. The claim is that a declared relational watch finds consequential changes with fewer harmful misses or distractions than simpler alternatives.
A proposed test would freeze a set of versioned anchor claims at a historical cutoff, then replay only material published afterwards. Human reviewers, blind to the method that retrieved each item, would decide which later sources genuinely bear on each anchor, which relations are supported, and where applicability remains unresolved. Disagreements and genuinely uncertain cases would be kept, not forced into a single label.
The test would run at least four conditions over the same accessible corpus and time window:
- ordinary feed and author alerts;
- carefully written keyword and citation alerts;
- a strong hybrid-retrieval alert;
- the proposed typed-relation channel.
A manual expert-review workflow would serve as a practical reference. The comparison would cover candidate recall (especially consequential misses), precision of the proposed relation and its scope, time to discovery, duplicate and false alerts, reviewer effort, and unsupported claims presented as established. It would also separate retrieval failures from relation-labelling failures. Held-out anchor versions and later sources should be used, not the examples used to construct the watch. A system that improves relevance among already-retrieved documents but misses the March paper has not solved the opening problem.
This is a proposed experiment, not a reported result. The baseline may win. That outcome would tell us whether typed subscriptions add anything beyond well-maintained conventional alerts, and at what cost.
Running it
Running it. The reference example, npm run example:radar, represents a subscription with an anchor, relation, conditions and exclusions. Its written condition asks for a “new, peer-reviewed result”. A retrieved preprint addressing the same claim does not satisfy that condition. The program records the reason rather than silently changing the user’s request to include preprints. If Iris wants preprints included, that is a new authorised condition.
A retrieved example of another mechanism working without a delay bound also remains an unresolved relation. The supplied evidence does not establish that its result applies to her specific anchor. In the tests, a model’s assertion alone cannot serve as that missing bridge. These are checks on the supplied case and on the program’s control flow. They are not a successful literature-discovery run.
What it does not show: successful discovery of the hypothetical March paper, reliable classification of relations, or an improvement in what a reader learns. The candidate relations and relevant source material in the example are supplied rather than found independently. The example also does not implement the complete reader-facing list of standing interests, nor does it demonstrate the proposed no-silent-expansion guarantee across an evolving watch. Its refusal cases are useful software tests. They are not measurements of missed relevant papers or false alerts.
Where this leaves us
A semantic channel is a standing request about the relation between new material and an explicit anchor. It is not simply a subscription to an author or topic. Its four semantic fields name the anchor, relation, conditions and exclusions. Its operational machinery must also respect source versions, coverage, permissions and change history.
Matching returns candidates with provenance and a review state. It does not automatically establish changes in the world. Declared interests should remain legible and editable. Discovery failures and omitted items stay part of the system’s evaluation rather than vanishing from the account.
That settles the shape of the standing request, but not its value as a service. A query may find nothing because there is nothing to find, because its conditions are too strict, or because the system never saw the relevant paper. And even a well-supported match does not tell the system when or how it should reach the reader. Qualification and delivery remain separate decisions:
qualifies
    ↓
candidate for attention
    ↓
delivery decision
A possible challenge found at three in the morning is a candidate for attention, not automatically an emergency. It may call for a short notice, a reviewable evidence bundle, a place in the morning digest, or no interruption at all. Confidence in the relation, the consequence of delay and the reader’s delivery policy must remain distinct. The next question is how much of a qualifying item should reach her first.
References
- Arasu, A., Babu, S. & Widom, J. (2006). The CQL Continuous Query Language: Semantic Foundations and Query Execution. The VLDB Journal. (Precedent for declarative queries that run continuously over incoming data streams; not evidence that semantic relations can be classified reliably.)
- Dwork, C., Lynch, N. & Stockmeyer, L. (1988). Consensus in the Presence of Partial Synchrony. Journal of the ACM, 35(2), 288–323. (Background for the distinct timing assumptions used in the constructed example.)
Research
Not yet researched
This chapter has not yet been researched.